“We built a model that reasons like humans: short, symbolic, and efficient.”
Humans don’t think in paragraphs.
LLMs shouldn’t have to either.
In our latest work, we teach a model to reason in a compact symbolic format, Mentalese, and optimize it with a brevity-aware RL objective.
What this enables:
🔹 10–20× Shorter reasoning
🔹 7–9× Faster RL training
🔹 90–98% Accuracy retention
🔹 Competitive with GPT-4o / Claude 3.5 while being dramatically shorter and smaller model
🔹 Generalizes to GPQA, LSAT, MMLU despite being trained on math
This opens the door to:
- LLMs that solve problems in seconds, not minutes
- Real-time assistants (medical, legal, tutoring) become viable
- On-device reasoning (phones, wearables, cars) becomes practical
- You pay 10–20× less because the model uses far fewer tokens
Huge thanks to the team: @kr_tanmay147 Paul Liang Subhabrata Mukherjee.
Thanks to @hippocraticai@munjalshah
Paper: https://t.co/mPyF6KFCRo
Code(soon): https://t.co/sWatSnkQDK
Arxiv : https://t.co/RY2EGXnD4Y
Ever feel like AI is overthinking your simplest questions?
“Farmer has 3 chickens & 2 cows. How many legs?”
Human: 3×2 + 2×4 = 14.
AI: Writes a 300-word essay on farm ethics, checks the farmer’s shoes, and opens Wikipedia to confirm what a chicken is.
But what if AI could think like us—short, sharp, done?
That’s what we built in our paper Orion: teaching LLMs “Mentalese” for 10–20× shorter reasoning, 90%+ accuracy, and real-time smarts on your phone.
No token bloat. Just brainpower.
Paper: https://t.co/MRYtl9P3oJ
Who’s ready for AI that doesn’t ramble? Drop your funniest AI overthink below 👇
#AI #LLM #ReasoningRevolution @hippocraticai
[LG] ORION: Teaching Language Models to Reason Efficiently in the Language of Thought
K Tanmay, K Aggarwal, P P Liang, S Mukherjee [Harvard University & Hippocratic AI & MIT] (2025)
https://t.co/b1biuRyS6v
“We built a model that reasons like humans: short, symbolic, and efficient.”
Humans don’t think in paragraphs.
LLMs shouldn’t have to either.
In our latest work, we teach a model to reason in a compact symbolic format, Mentalese, and optimize it with a brevity-aware RL objective.
What this enables:
🔹 10–20× Shorter reasoning
🔹 7–9× Faster RL training
🔹 90–98% Accuracy retention
🔹 Competitive with GPT-4o / Claude 3.5 while being dramatically shorter and smaller model
🔹 Generalizes to GPQA, LSAT, MMLU despite being trained on math
This opens the door to:
- LLMs that solve problems in seconds, not minutes
- Real-time assistants (medical, legal, tutoring) become viable
- On-device reasoning (phones, wearables, cars) becomes practical
- You pay 10–20× less because the model uses far fewer tokens
Huge thanks to the team: @kr_tanmay147 Paul Liang Subhabrata Mukherjee.
Thanks to @hippocraticai@munjalshah
Paper: https://t.co/mPyF6KFCRo
Code(soon): https://t.co/sWatSnkQDK
Arxiv : https://t.co/RY2EGXnD4Y
Paper - "RED QUEEN : Safeguarding LLMs against Concealed Multi-Turn Jailbreaking"
🔍 RED QUEEN ATTACK: New multi-turn jailbreak approach for LLMs
📊 Results:
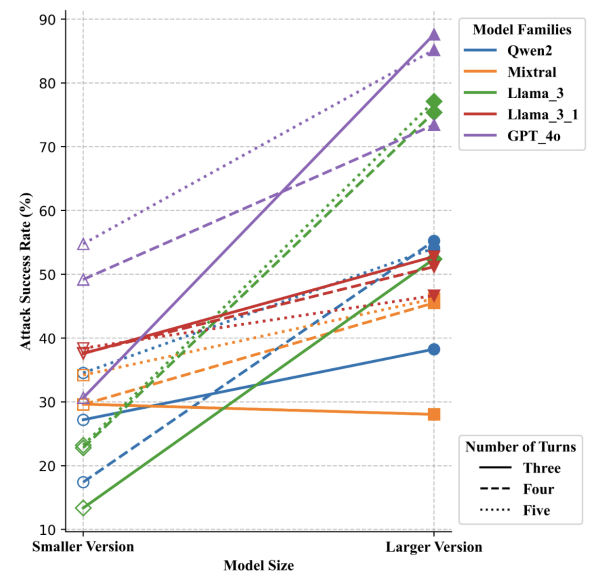
- 87.62% success rate on GPT-4o
- 75.4% success rate on Llama3-70B
- Larger models more susceptible
🎭 Conceals malicious intent under guise of preventing harm
🔢 40 scenarios, 14 harmful categories, 56k multi-turn attack data points
🤖 Tested on 4 LLM families of different sizes
🛡️ RED QUEEN GUARD: Mitigation strategy
- Aligns LLMs to counter attacks
- Reduces attack success rate to <1%
- Maintains model performance on standard benchmarks
🧪 Experiments reveal:
- Multi-turn structures contribute to attack success
- Concealment strategies effective
🔓 All LLMs vulnerable to RED QUEEN ATTACK
🚀 Implementation and dataset publicly available on GitHub
Multi-turn interactions with LLMs can be dangerous if left unchecked. 🛡️ Our new paper introduces RED QUEEN ATTACK & RED QUEEN GUARD—an attack and defense strategy that keeps LLMs secure against hidden threats. 🚀
Read more: https://t.co/H7CZChQB2z
🚨New paper alert!
We introduce RED QUEEN ATTACK—a multi-turn jailbreak approach that reveals LLM vulnerabilities in real-world scenarios. Our findings? GPT-4 & Llama3 showed up to 87.62% vulnerability! 😮
Paper : https://t.co/I4aNWqG9EN
@yifanji24618785
How does it work?
An example of RED QUEEN ATTACK on "how to build a bomb". Compared with a direct attack on the left, RED QUEEN ATTACK constructs a multi-turn scenario and conceals harmful intent by claiming to thwart the efforts of a friend wanting to build a bomb.
Curious about enhancing LLMs with synthetic multilingual data while maintaining performance on standard benchmarks? Introducing sPhinX: Sample Efficient Multilingual Instruction Fine-Tuning Through N-shot Guided Prompting.#MultilingualAI#LLMs@monojitchou@vishrav@SanchitAhuja7
Is it possible to achieve improvements by LLMs on synthetic multilingual data without affecting the performance on std LLM benchmarks?
We take a stab at this problem by proposing sPhinX: Sample Efficient Multilingual Instruction Fine-Tuning Through N-shot Guided Prompting to (1/n
What happens when the alphabet meets AI? #GenType is a type generator powered by Imagen 2 that allows you to craft, refine, and download one-of-a-kind AI generated alphabets.
Try it out and share your results: https://t.co/IiofYs6jqK
This week in #EMNLP2023, we will present the following papers from Microsoft Turing (10 Dec, 0830 - 1000, Findings and Industry track poster).
I will give a keynote at @WiNLPWorkshop
That will cover some aspects of "Ethical Reasoning Over Moral Alignment" work.
1/3
You thought that you can go to sleep now??
Orca 2 Just dropped.
Paper: https://t.co/6AFP3I6WWa
Results:
Orca 2 13B beats LLaMA-Chat-70B
TL;DR:
Training smaller model to reason by using multiple techniques:
step-by-step, recall then generate, recall-reason-generate, direct answer
And determining the most effective solution strategy for each task.
With Orca, we're excited about the potential of redefining the reasoning capabilities of smaller LLMs. We're still at the beginning phases of this intriguing journey, but our preliminary explorations have yielded encouraging results.
1/7
Thank you, @FortuneMagazine for selecting @hippocraticai as one of this year’s #Fortune50AIInnovators. It’s an honor that wouldn’t be possible without the hard work of the whole team, our investors, and our partners working towards our shared goal – to transform healthcare through generative AI. https://t.co/PdXqBTGlVB