What will make personal AI go big?
Four design principles behind Muse’s appeal
- Make it approachable
- Make me feel I can trust it
- Give me outsized value
- Give me a sense of possibility
https://t.co/c1inZWBfUE
AI doesn't fix your organisation, it magnifies it at machine speed, so the moat isn't the model but the unglamorous architecture of decisions, meaning, proof, and people around it.
Watch real customers struggle before you write the test, because you can't grade something properly until you've personally seen what failure looks like.
Some other use cases:
- VoC theme tracking over time
- Feature request mining
- Churn reason attribution
- User journey and intent tagging
- Sentiment and reaction to releases
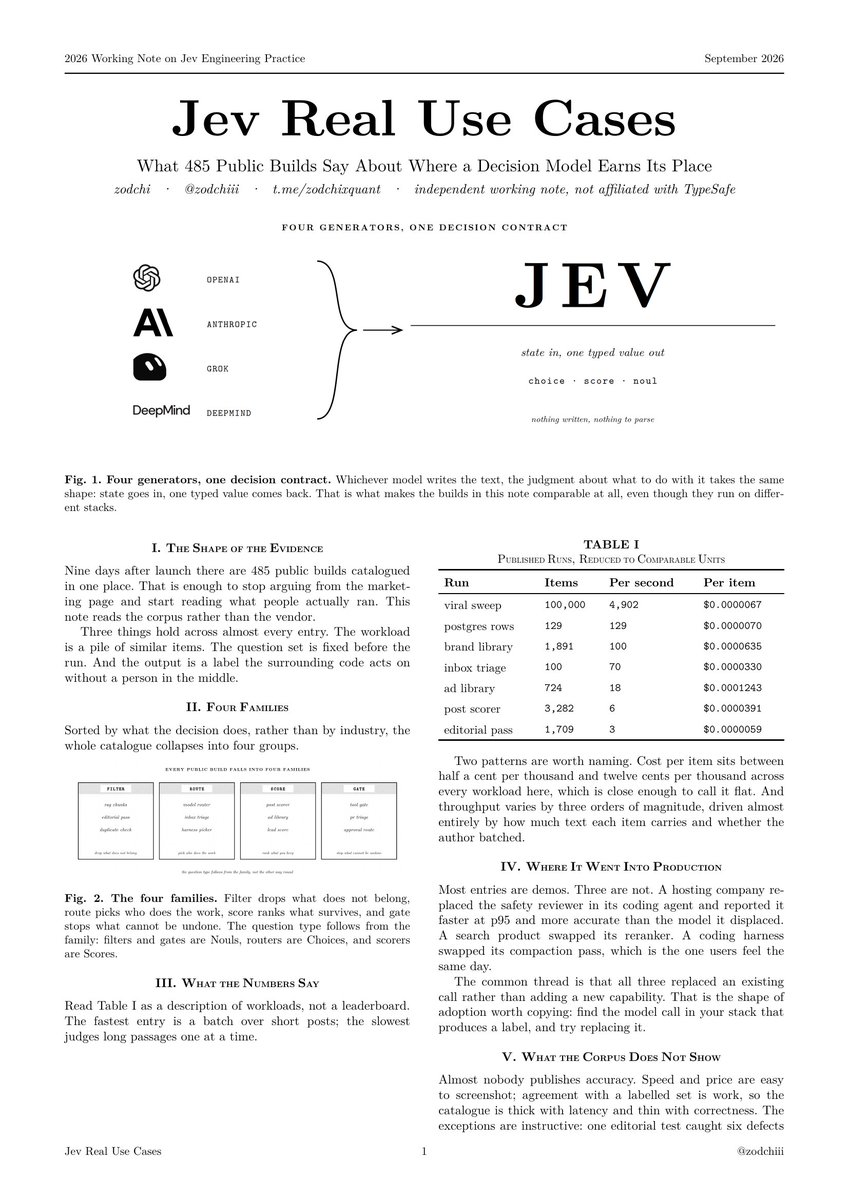
Labelling a million rows of text just went from "expensive AI project or train your own model" to "one line of SQL", which makes previously unthinkable workloads (like reading every support transcript you've ever stored) suddenly cheap and fast
https://t.co/wDQtlGvLob
The Age of the Soft Skill
Generation is free but attention isn't, so the people who win in 2026 are the ones who compress, decide, and follow through, because the soft skills were only "soft" while the hard skills were rare
https://t.co/GItIbGICGK
"I compared Jev with Qwen on 3,080 bank messages, looking not only at which model made the right decision, but also at speed, confidence, and what happened when the available answers did not quite fit the input."
@nhu_hoang shares a detailed comparison of LLMs with new "System One" model, Jev. https://t.co/zv525nxvta
Jev is the "Internet" moment for the AI industry
It tells your agents and LLMs what to do next, in milliseconds and at almost zero cost
If you set it up correctly, you will have the AI engineer’s stack for 2028
In this document, I show you how
Bookmark it, then check out the full Jev guide below
Jev vs. LLM as Judge, clearly explained.
Imagine a support agent says, “Done. I issued your refund.”
The trace shows that the agent looked up the order, but never completed the refund. An evaluator now needs to decide whether the answer is grounded, honest, and useful.
Both an LLM judge and Jev can make those judgments. The difference is how they produce them.
→ Both need the same evidence
The customer request, policy, tool results, and agent answer must be included. A judge cannot evaluate evidence it has not seen.
→ An LLM judge generates an evaluation
You describe the rubric in a prompt and specify the desired output. The model then generates a verdict, score, structured JSON, or written explanation one token at a time.
This works well when the evaluation needs detailed reasoning, an explanation, or an answer outside a predefined set.
→ Jev returns structured decisions
You provide the evidence once, then define separate questions with predefined answer formats.
For a yes-or-no criterion, Jev returns the probability that the statement is true. For an ordered criterion, it returns a rating and a separate confidence value.
The Jev calls these formats Noul and Score, but the core idea is simple. The possible answers are defined before the evaluation runs.
Jev evaluates independent questions against the shared evidence in parallel. Your code receives values it can immediately use for thresholds, routing, or review.
→ The workload determines the better interface
Use an LLM judge when you need open-ended reasoning or a written rationale.
Use Jev when you repeatedly need focused judgments such as whether an answer is grounded, whether an action claim is honest, or how actionable the response is.
Multiple LLM judge calls can also run concurrently. The important distinction is not concurrency between calls. It is token-by-token generation versus parallel structured judgments within one request.
That distinction matters at scale. When every agent run needs several checks, a faster and cheaper evaluator can help you inspect more traces, measure more dimensions, and catch failures earlier.
Jev does not replace every LLM judge. It gives bounded evaluation workloads a more direct interface.
The agent generates the answer. The judge should only generate when the judgment requires it.
I also published the complete evaluation workflow using Jev and Comet’s open-source Opik platform. The repository includes frozen agent traces, structured rubrics, result mapping, and the experiment runner.
You can explore and run the code here: https://t.co/XVmpg6ldHT
I wrote the full breakdown. The article is quoted below.
Your AI agent made the decision, but the risk is still yours to own: the scariest failures aren't the ones that crash, they're the transactions that succeed without anyone authorising them.