YA A LA VENTA
Revista Rocambolesca #8
Verano 2026
Tapa blanda (https://t.co/zOfiSBuIjk)
Con cuentos de:
Luis Enrique Cuéllar, Belem Eslava, Atenea Cruz, @jluisram , @LoboRafagas , Jovany Cruz Flores, Mijal Montelongo Huberman y de Federico Schaffler.
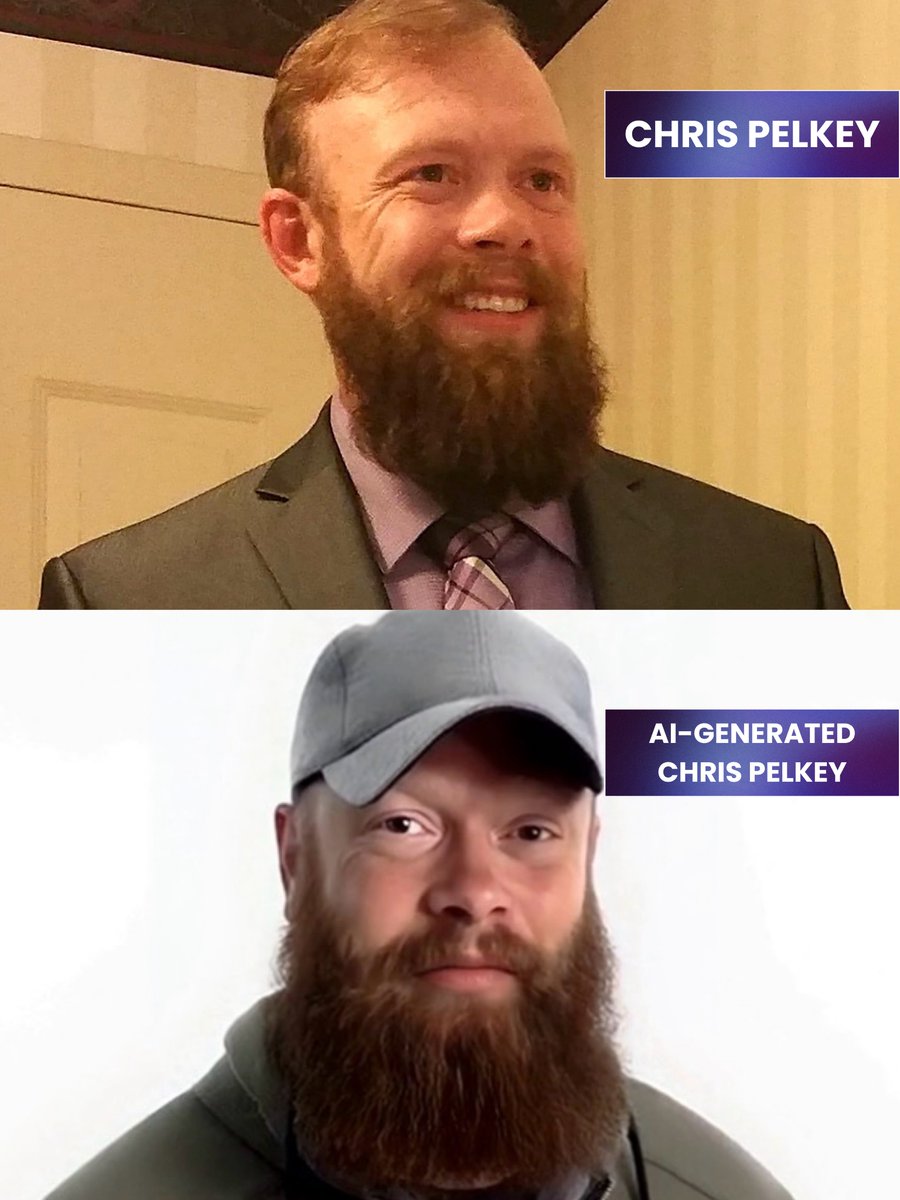
An Arizona man convicted of killing a road-rage victim will be resentenced after an AI-generated video of the victim forgiving him was improperly used during sentencing.
The initial judge said he felt that the AI-generated depiction of the victim portrayed “genuine forgiveness.”
Y es por eso que, el que Murphy siga teniendo trabajo es un milagro en esa industria tan fan de la censura y cancelación. Igual y no me gustan sus series pero tiene la libert de hacer lo que le venga en gana y eso ya es ganancia.
Jeffrey Dahmer was a real person and serial killer who murdered 17 innocent men and boys. His youngest victim was 14 years old. He drugged them, performed experiments, killed them, sexually violated their corpses, took photos of their bodies, dismembered and ate parts of them. He is not a fictional character or someone to use for a comedic bit.
Ryan Murphy is a weirdo with no respect for the victims or their families. His obsession with real murderers and falsifying their stories while advertising it as factual is beyond unethical and disgusting. This is wrong and gross.
El CEO de Adobe viendo cómo alguien creó un editor de pdf de 20mb, lo publicó 100% GRATIS y no puede hacer nada porque técnicamente no hizo nada ilegal
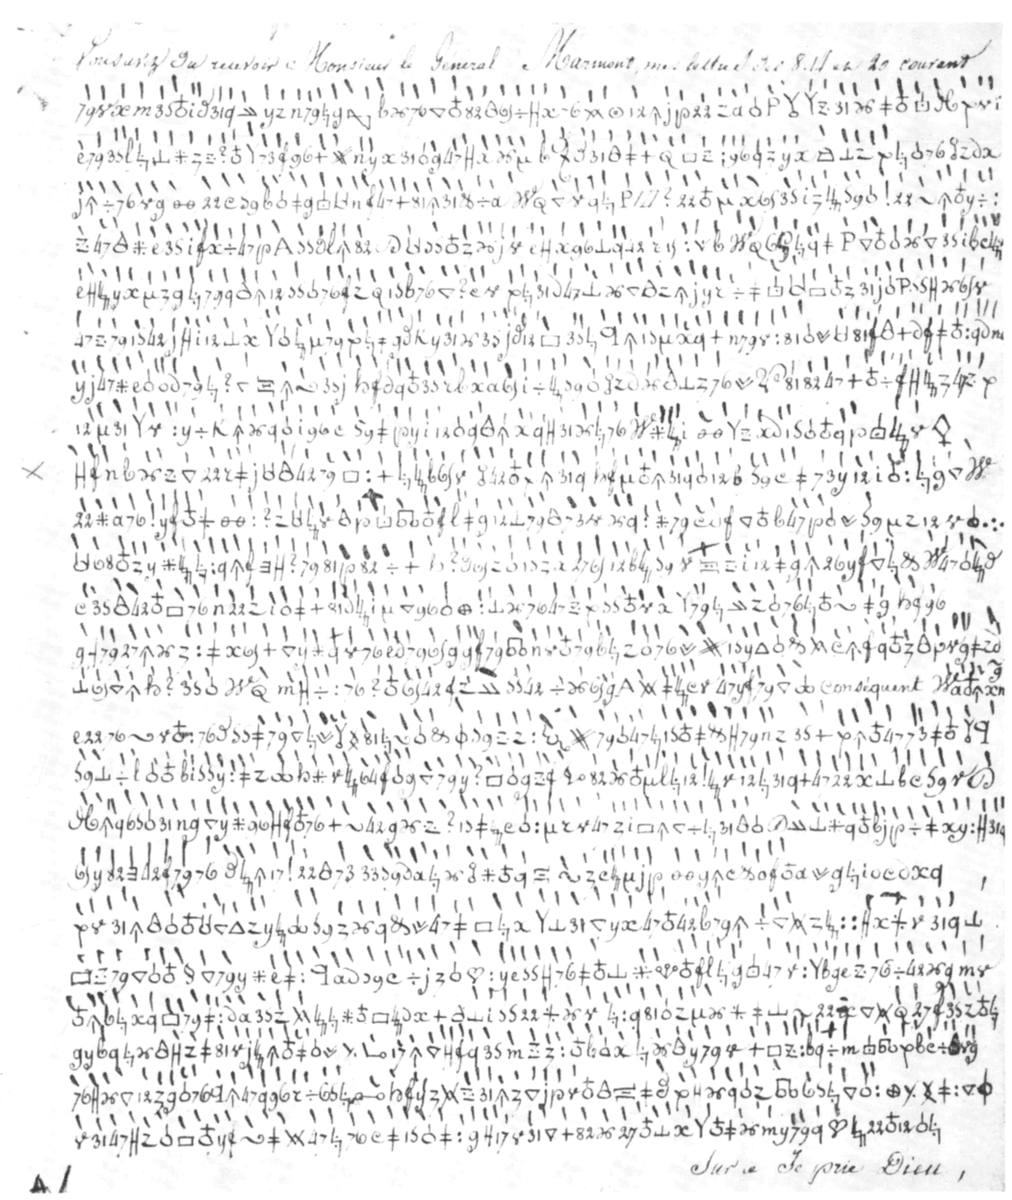
I used GPT-6 Astra to break an unsolved cipher to one of Napoleon's generals that had gone unread for 217 years.
What makes this impressive isn't actually the codebreaking, but that Astra completed the entire multi-modal workflow in ~6 hours from a single image and goal.
1/6🧵
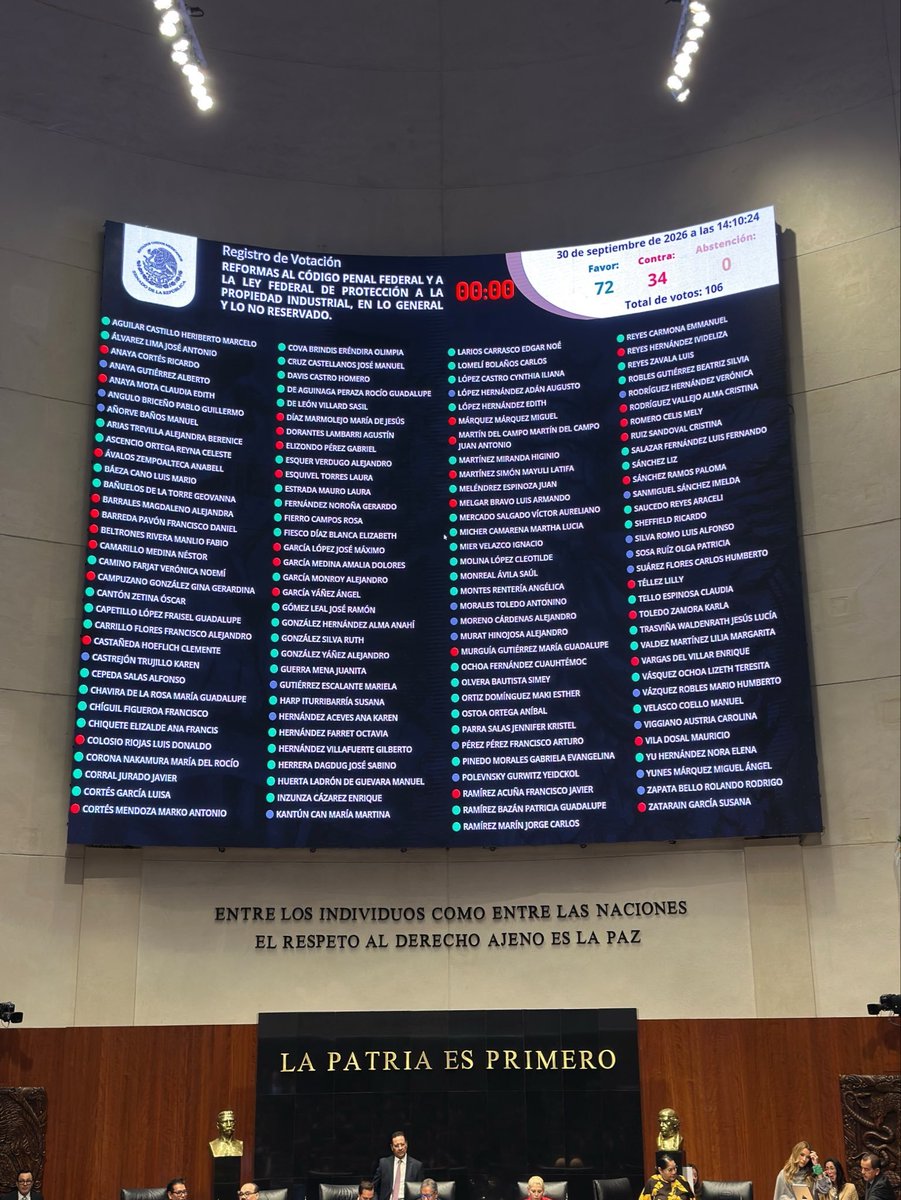
🚨#ÚLTIMAHORA El Senado aprueba la "Ley Antimemes".
Con 72 votos a favor, 34 en contra y cero abstenciones, la Cámara de Senadores avaló en lo general un paquete de modificaciones al Código Penal Federal y a la Ley Federal de Protección a la Propiedad Industrial.
La iniciativa busca regular la modificación no consentida de imágenes, obras y contenidos protegidos por derechos de autor en el entorno digital.
📷: @letroblesrosa
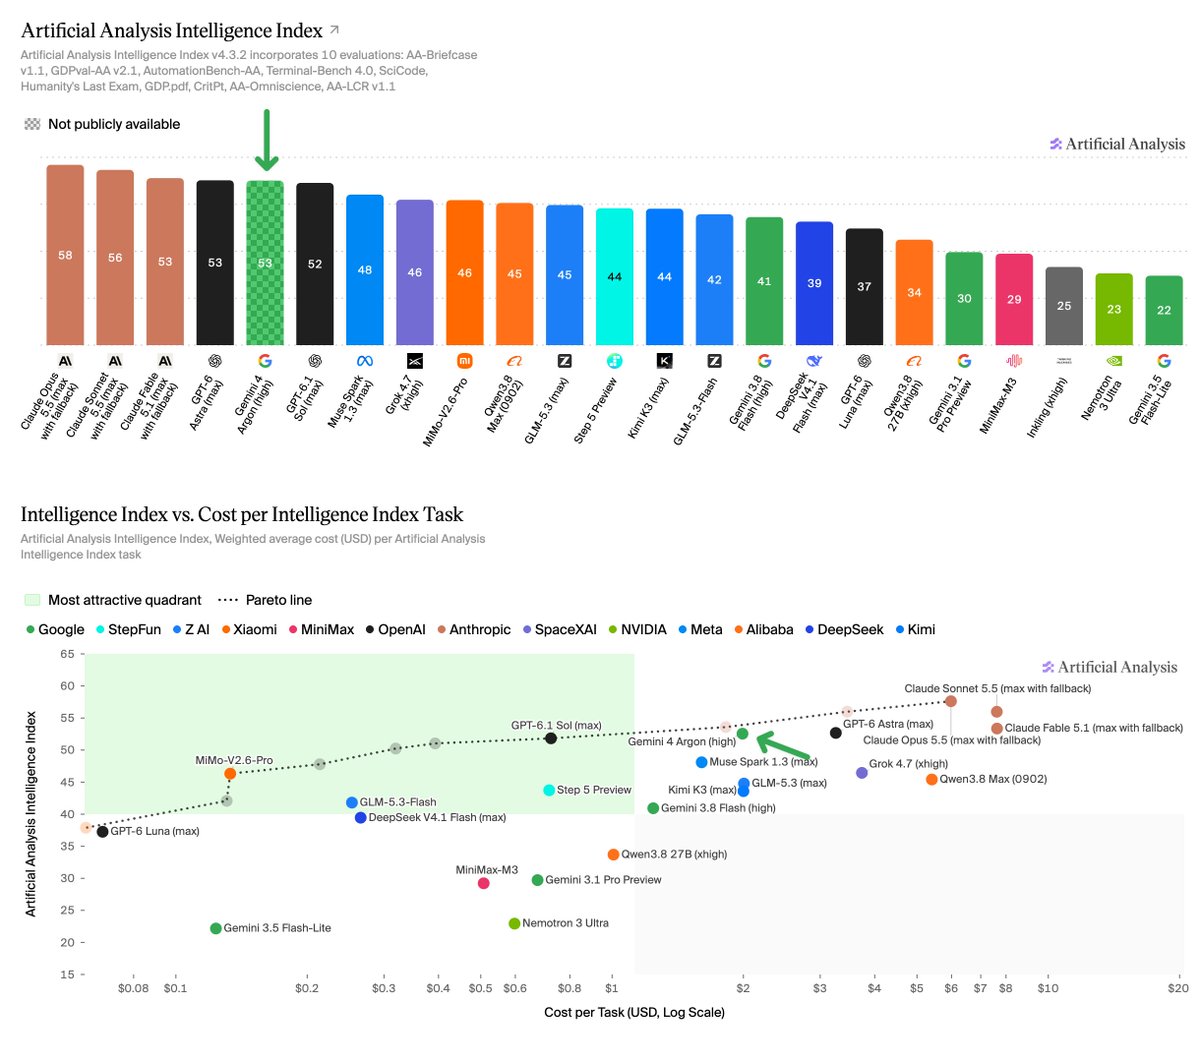
Google’s new Gemini 4 Argon equals GPT-6 Astra on the Artificial Analysis Intelligence Index at 60% of the Cost per Task with discounted prices. Google is now back to being one of the top three labs in intelligence achieved
Gemini 4 Argon is @GoogleDeepMind’s first proprietary model above the Flash class in over 7 months. With high reasoning (the highest available), it scores 53 on the Artificial Analysis Intelligence Index, matching GPT-6 Astra (max, 53) and 1 point ahead of GPT-6.1 Sol (max, 52), with gains driven by lower hallucinations and stronger agentic capabilities.
At its current 50% pricing discount and with cache discounts increased to 95%, Gemini 4 Argon costs $1.99 per Intelligence Index task, 60% of GPT-6 Astra (max), but 2.7x GPT-6.1 Sol (max). After the discount ends, this will rise to $3.98 (~1.2x GPT-6 Astra (max)).
Gemini 4 Argon is currently being rolled out to selected users and is not publicly available. The 50% discount is an initial promotion. Google has not yet confirmed the promotion end date
Key benchmarking results for Gemini 4 Argon with high reasoning:
➤ Google returns as one of the top three labs on intelligence: Gemini 4 Argon (high) scores 53 on the Artificial Analysis Intelligence Index, matching GPT-6 Astra (max, 53) and 1 point ahead of GPT-6.1 Sol (max, 52). This is 23 points above Google’s previous non-Flash model, Gemini 3.1 Pro Preview (30) and 12 points ahead of Gemini 3.8 Flash (high)
➤ Launch discounts of 50% make Gemini 4 Argon competitive on Cost per Task: At current discounted pricing, Gemini 4 Argon (high) costs $1.99 per Intelligence Index task, 60% of GPT-6 Astra (max, $3.26) for a comparable level of intelligence. This cost efficiency is driven by lower token prices, rather than reduced token use, with Gemini 4 Argon averaging 62k output tokens per task, compared with 27k for GPT-6 Astra (max). Google has not yet confirmed the promotion end date, but on standard pricing, Cost per Task will increase to $3.98
➤ Stronger agentic performance: Historically a weaker area for Gemini models, Gemini 4 Argon shows improvements across agentic evaluations. It ranks #1 on AutomationBench-AA at 77.5%, 6 points ahead of Claude Sonnet 5.5 (max, 71.3%). On Terminal Bench 4, Gemini 4 Argon achieves 57%, a +53 point improvement from Gemini 3.1 Pro Preview, only behind Claude Sonnet 5.5 (max, 64%), Claude Opus 5.5 (max, 60%) and GPT-6 Astra (59%). On AA-Briefcase, it reaches 1494 Elo. This is driven by a 65% rubric pass rate, the highest we have recorded, but lower Analytical Quality (1576 Elo) and Presentation Quality (1308 Elo)
➤ Lowest hallucination rate among leading models: On AA-Omniscience, Gemini 4 Argon has a 15% hallucination rate, the lowest of any model scoring 45+ on the Intelligence Index, compared with 51% for GPT-6 Astra (max) and 54% for GPT-6.1 Sol (max). This means Argon is much more likely to acknowledge when it does not know an answer rather than guess incorrectly. On accuracy, Gemini 4 Argon scores 50%, a 5 point decrease from Gemini 3.1 Pro Preview, and 13 points below GPT-6 Astra (max, 63%). With this slightly lower accuracy, its overall AA-Omniscience score of 42 remains in line with GPT-6 Astra (43) and GPT-6.1 Sol (42)
Key model details:
➤ Context Window: 1M tokens
➤ Multimodality: Text, image, video, and speech input, with text output
➤ Pricing: $4/$20 per 1M input/output tokens at standard pricing, currently discounted 50% to $2/$10. Cached input tokens receive a 95% discount ($0.10 per 1M at discounted pricing), up from 90% on Gemini 3.8 Flash
➤ Long Decode Continuation: We tested Gemini 4 Argon with Long Decode Continuation, a new Gemini API feature that pauses long responses and resumes them across follow-up calls. This lets reasoning run up to 1M output tokens without request timeouts
Today we’re introducing Gemini 4 Argon.
It delivers frontier performance in complex workflows across real-world software engineering, knowledge work, and cybersecurity defense with an industry-leading 1M token output limit.