1/ OpenRouter's cheapest price is not your lowest inference cost.
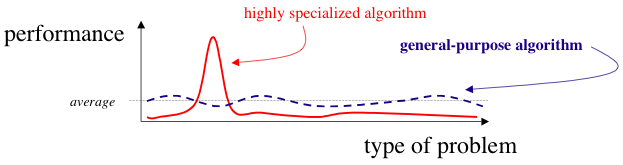
That price was set for everyone who shares the endpoint. A stack tuned to your own traffic can cost far less.
What that takes, and what we've measured:
Does your AI agent or service spend a lot on LLM, voice or image models?
Join us for Korean dinner in SF 🍲 Let's swap notes on building and running AI in production.
Nov 1, 6–9pm PT
Dinner's on us. BYOB if you'd like.
Small table. Seats by approval.
https://t.co/dVmepLTPR4
@thtrkim@harvey Thanks, Terry. The size of the gap surprised us too. Having a real task-level eval is what let us optimize the serving stack aggressively without guessing about quality.
1/ $4.03 → $0.03–0.07 per task.
Same model, Qwen3.8-27B, on @harvey's LAB benchmark. About 60x below the leaderboard entry, with no new model and no fine-tuning.
What we changed:
@_jong_hyun_park@harvey Yes, potentially, but this result is specifically for text inference. Video generation and understanding have different bottlenecks and need their own quality evals. If you have a model and workload in mind, we’d be interested in profiling its cost, latency, and quality.
6/ We'd like to see how this does on the full eval, held-out set included. @harvey@nikogrupen@ValsAI, happy to share the endpoint, configs and traces.
https://t.co/FqIR7KFyd5
1/ OpenRouter's cheapest price is not your lowest inference cost.
That price was set for everyone who shares the endpoint. A stack tuned to your own traffic can cost far less.
What that takes, and what we've measured:
6/ The catch: that takes your own benchmark, and most teams don't have one yet.
That's where we'd start with you. Agree on what "good" means for your workload, then find the cheapest stack that meets it.
DMs are open. Full write-up: https://t.co/dpYosKZfkR
This is exactly what we've seen from multiple clients.
the OpenRouter price is not your optimal solution.
You have to build your business from your data. ☕️
There's an interesting distortion in inference pricing that appears to be driven by openrouter's routing.
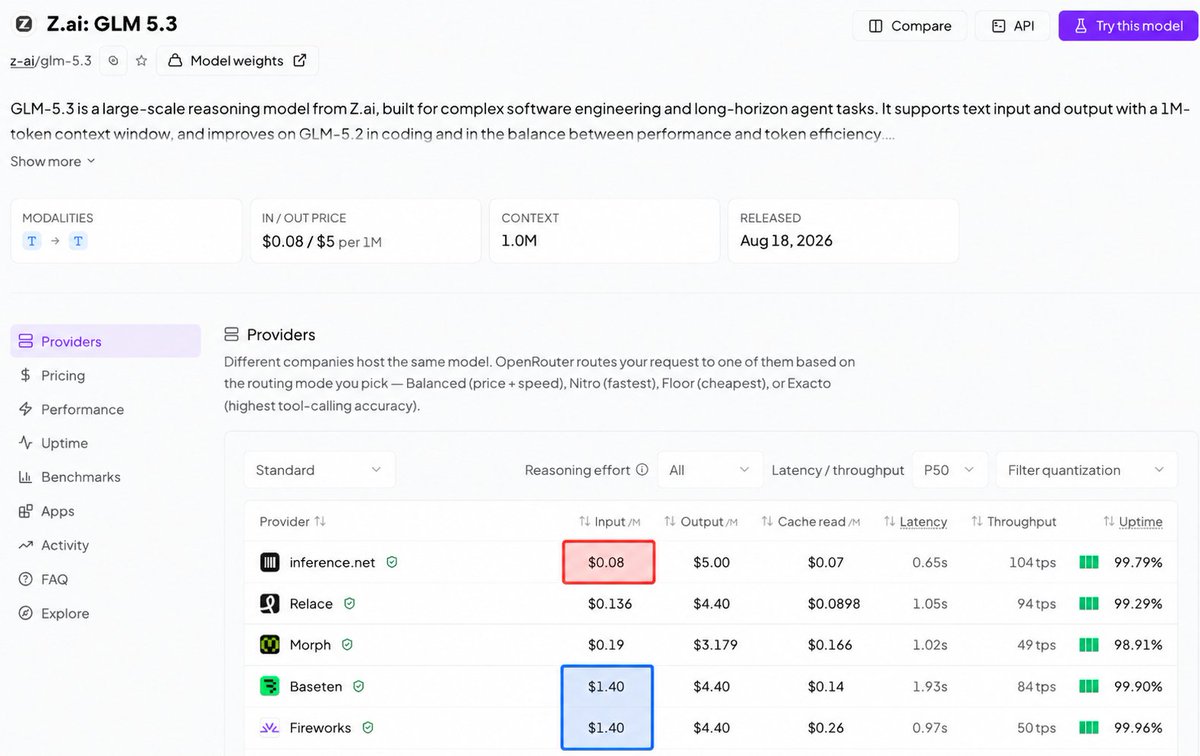
Namely, ridiculously cheap prefill and very expensive decode. For GLM 5.3, https://t.co/07u3tv4AS4 (highest volume provider) charges $0.08/M input but $5.00/M output!(1/5)
1/ OpenRouter's cheapest price is not your lowest inference cost.
That price was set for everyone who shares the endpoint. A stack tuned to your own traffic can cost far less.
What that takes, and what we've measured: