Can’t stop, won’t stop. The open models keep dropping
FLUX 3 Image Klein 5.6B was trained on NVIDIA GB200 NVL72 and can run on an RTX GPU.
Big 🙌 to the @bfl_ai team. There's also an NVFP4 variant: https://t.co/7rlalk7Otf
FLUX 3 Image Klein is here.
Open Weights with the quality of a large frontier model. Customizable and fast.
5.6B parameters and runs on a single consumer GPU.
Native 4K, bounding boxes, and pixel-perfect editing.
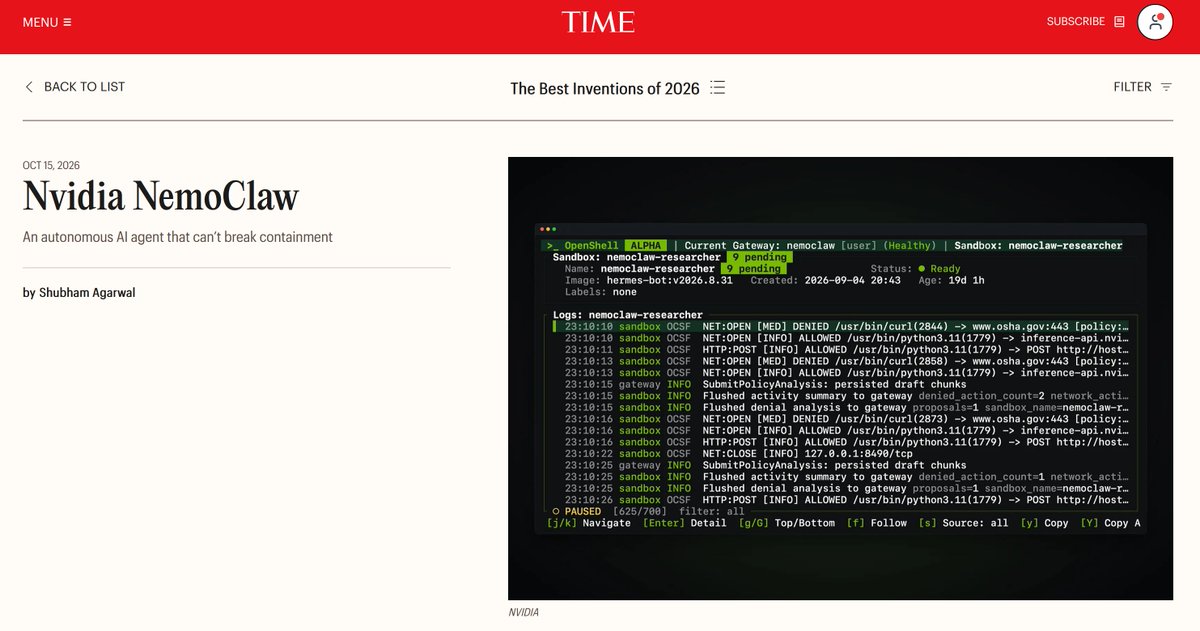
NemoClaw was just named one of TIME’s Best Inventions of 2026! 🦞
So proud of the team and shoutout to everyone building safer AI agents with us.
Blurb on @TIME: https://t.co/EY5S9htCn5
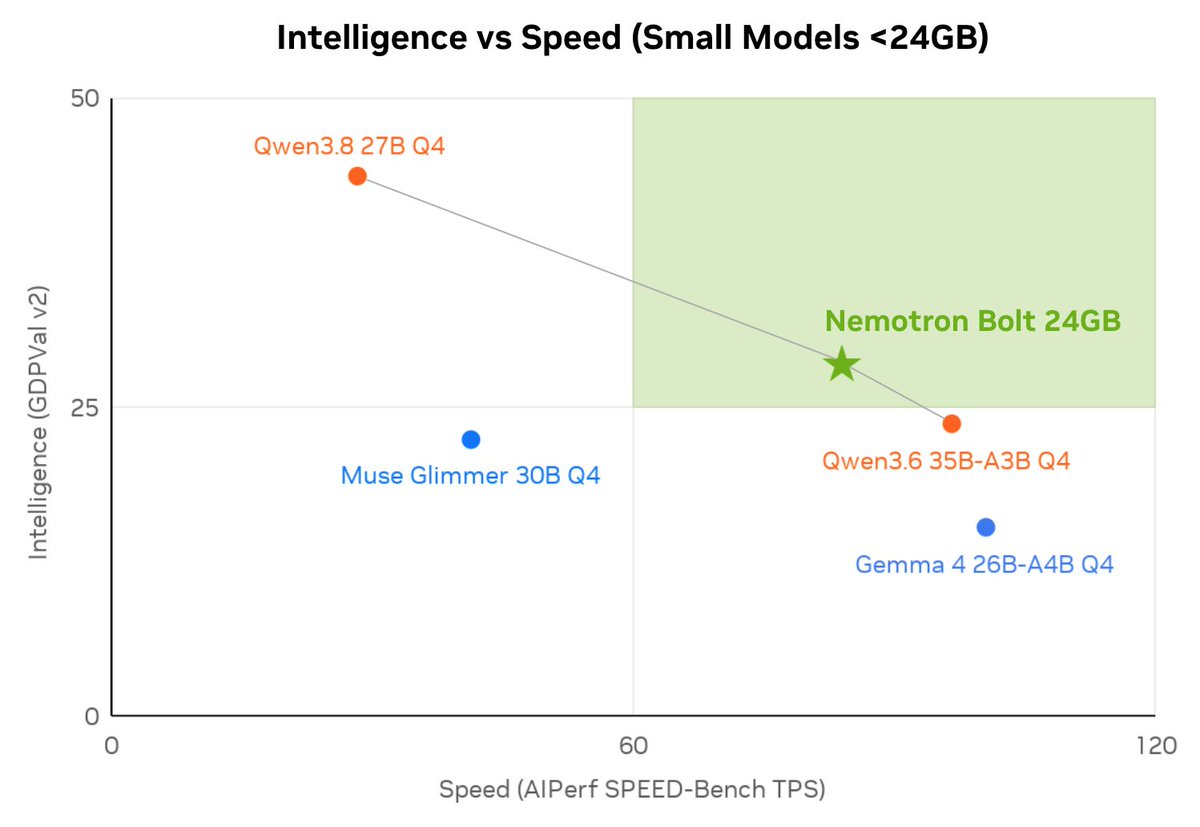
NVIDIA Nemotron 3.5 Bolt 24GB puts powerful local agents within reach. ⚡
74B-A9B parameters packed into 24GB of memory, balancing intelligence and speed while running alongside your apps. Optimized for RTX Spark and ready for your next project.
Meet NVIDIA Nemotron 3.5 Super VL
Our new open model combines reasoning and tool use with text, image, document, and video understanding for long-running AI agents.
120B total parameters with 12B active 🧵
And @AIatMeta went live with Muse Spark Open!
The 816B model was trained on NVIDIA GB300 NVL72. Its 1M-token context window gives coding agents room to work across large codebases.
Meta also produced NVFP4 checkpoints optimized for Blackwell Ultra, delivering over 50K tokens/sec/GPU to improve throughput and lower cost per token.
Congrats to the @Muse team.
More in our blog: https://t.co/WcSFpdHowL
NVFP4: https://t.co/gBvebf8XxE
Today we’re releasing Muse Spark Open, the most capable US open-weight model to date.
Built for coding and agentic work, it excels at long-horizon tasks, complex software engineering, and multi-step reasoning.
Key Model Specs:
→ 816B total / 42B active parameters
→ 1M token context window
→ Natively multimodal across text, image, video, audio
Agents may need to read documents, interpret charts, and search the web to complete a task.
Nemotron 3.5 Super VL brings text and visual understanding into one model, reducing the need to pass context between separate text and vision models.
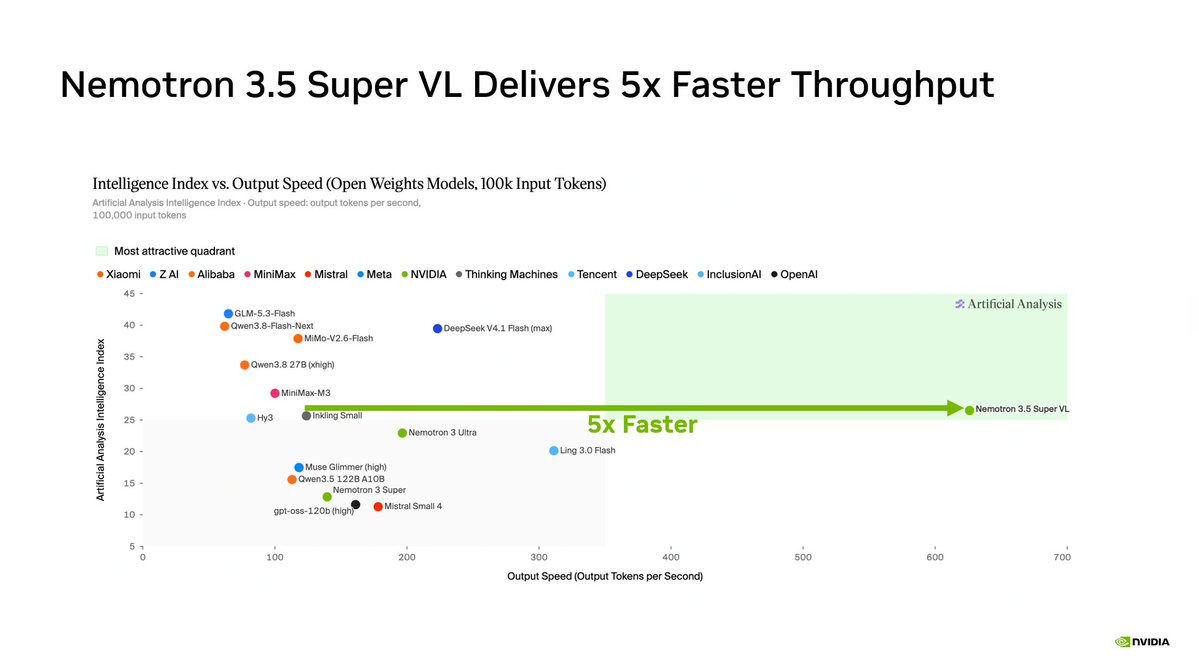
Nvidia’s Nemotron 3.5 Super VL is now the leading US open weight model, scoring 26 on the Artificial Analysis Intelligence Index
Nemotron 3.5 Super VL achieves twice the intelligence of its predecessor, Nemotron 3 Super (13), and does so using ~60% fewer output tokens per task
It launches alongside Nemotron 3.5 Bolt 74B-A9B 24GB, the first model in its new Bolt family, which scores 21 on the Intelligence Index
Congratulations to @NVIDIAAI on the releases!
Key Takeaways:
➤ Leading US open weight model: Nemotron 3.5 Super VL scores 26.5, edging out Thinking Machines' Inkling Small (25.7) and ahead of NVIDIA's Nemotron 3 Ultra (23) and Meta's Muse Glimmer (17)
➤ Bolt comes within 2 points of Ultra: Nemotron 3.5 Bolt 74B-A9B 24GB scores 21, 1.5 points behind Nemotron 3 Ultra 550B A55B (23). The 2 bit memory has about a seventh of Ultra's parameters (74B vs 550B) and a sixth of its active parameters (9B vs 55B)
➤ Super 3.5 VL near lossless in NVFP4: Nemotron 3.5 Super VL releases in NVFP4, scoring within 0.1 points of its BF16 weights on the Intelligence Index, with no component moving by more than 2.6 points
Nemotron 3.5 Super VL details
Context window: 1M tokens
Modalities: Vision and text input; text output
Parameters: 120B / 12B
Nemotron 3.5 Bolt 74B-A9B 24GB details
Context window: 256k tokens
Modalities: Vision and text input; text output
Parameters: 74B / 9B
How we built Nemotron 3.5 Super VL, including its post-training approach, multi-token prediction, and inference optimizations: https://t.co/sVHeQsM5nH
As always, NVIDIA Nemotron 3.5 Super VL is open and customizable. This includes weights, data and recipes. Available now on @huggingface → https://t.co/FnFowUHnHJ
Congrats to StepFun on Step 5 Preview 🙌 Their largest open weights release.
The 600B MoE model is built to handle agent tasks lasting up to 24 hours.
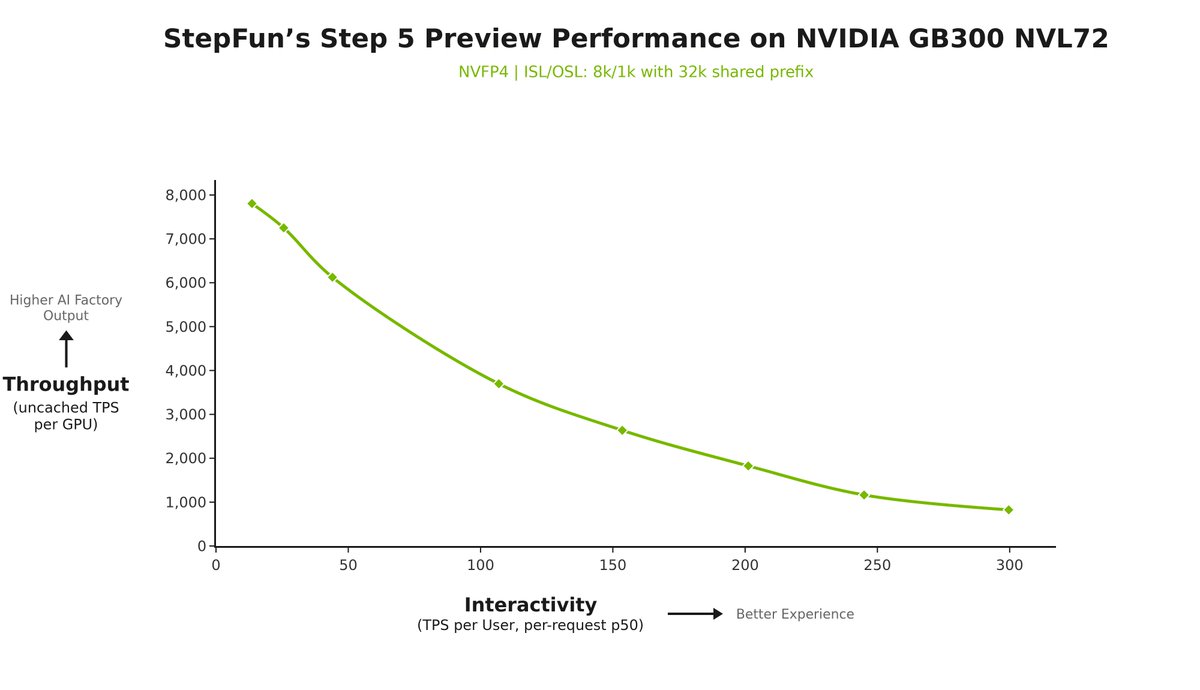
The model runs at nearly 8K tokens/sec/GPU on NVIDIA GB300 using NVFP4.
NVP4 checkpoint: https://t.co/poBcZXeWqY
Deploy with @SGL_project - https://t.co/2iE8ytEk50 or @vLLM_project - https://t.co/PedItg9OR4
Post-train with NeMo Automodel: https://t.co/KxNt53Sb8k
Run it with NVIDIA NIM using a single command: https://t.co/UOWllHNEMW
Step 5 Preview is now open weights.
BF16 and FP8 weights are live on Hugging Face and ModelScope, together with our technical blog.
• Sparse MoE: 600B total, 27B active per token
• 1M-token context window
• Native text and vision input
• Built for long-horizon agentic work: coding, software engineering, professional knowledge work and finance
Frontier intelligence, open weights. Build what's next.
Hugging Face: https://t.co/nMfayf37ja
ModelScope: https://t.co/mkB3qIoMQA
GitHub: https://t.co/siRkQqaruX
Build-A-Claw London ✅️
A visit from @JensenHuang ✅️
A very good day to have a raffle ticket ✅️
Thank you to everyone who stopped by!
See you in the next city.