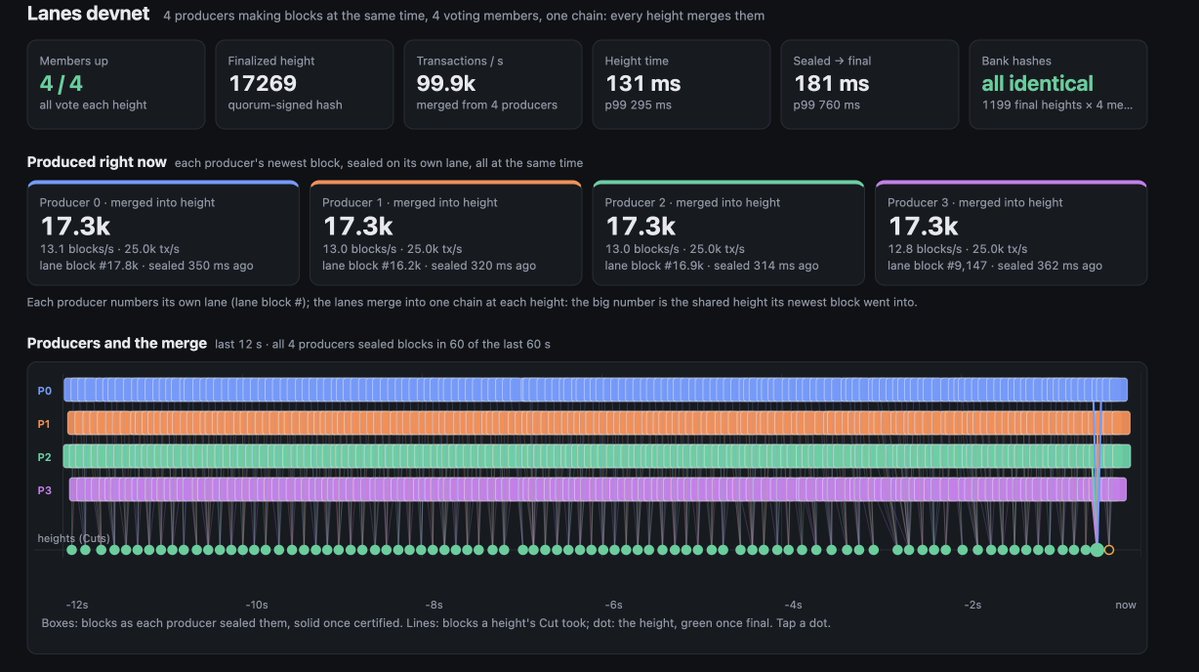
Solana needs at least ~2.5B CU/s of execution capacity to support privacy-preserving workloads at scale
At 200ms slots (5 slots/sec), that's 500M CU/block
10× increase over the current 50M CU/block limit
See the full collection on @huggingface: https://t.co/YMi4vskuto
All quants sized to fit well:
- q6 (recommended): 313gb
- q8 (reference): 326gb
- q4 (fastest, lossy): 300gb
Run Kimi K3.1 Pro on an Apple Mac Studio 🫰
- Trimmed down to just 313gb
- Fits on a single 512gb m3/m5 Ultra
- Q6 matches Q8 within 0.2% perplexity
- Code-tuned REAP prune, built for agentic workloads
Get the frontier running locally: https://t.co/YMi4vsl2iW
Introducing Kimi K3.1 Pro: our most capable 3T-class open-weight model.
🔹 1M-token context, 2.8T total / 104B active params (MoE), Multimodal.
🔹 Full-project coding: games in Unreal, Unity & Godot.
🔹 Excels at parametric 3D modeling in Blender & CAD.
🔹 More reliable at finance work: Accurate modeling with hallucination down by 65%.
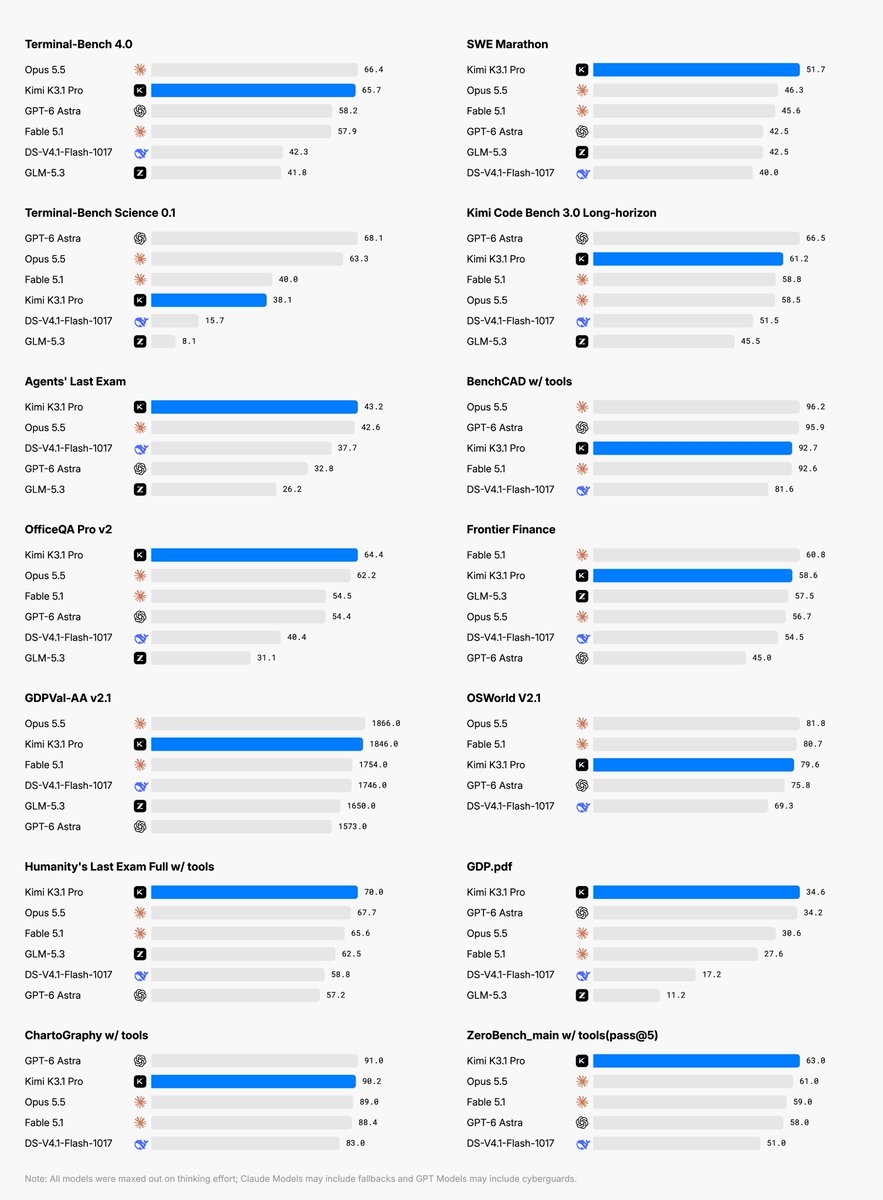
🔹 Matching the strongest proprietary models across coding, agentic and knowledge benchmarks.
Kimi K3.1 Pro and K3.1 Pro Highspeed (2–3× faster) are now live on https://t.co/85jA71X9gw, Kimi Work, Kimi Code, and the Kimi API.
Open weights by Nov 4, 2026.
🔗 API: https://t.co/XCrgjXAqMw
🔗 Tech blog: https://t.co/5iPP0MBej6