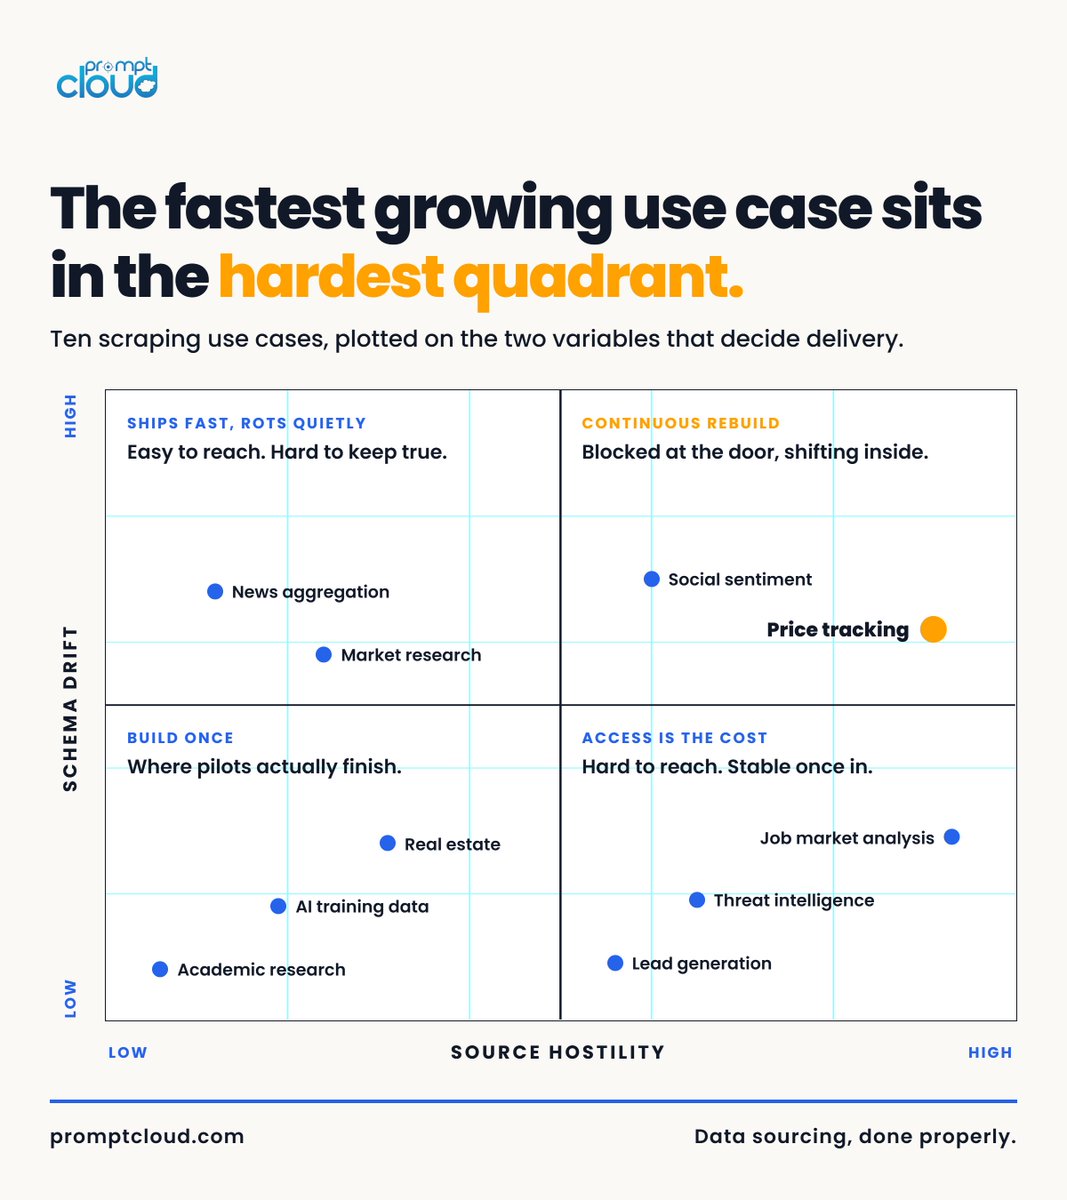
Price and competitive monitoring is the roughest web scraping use case there is. It is also the fastest growing segment in the market right now.
Difficulty and value are correlated here. That is usually the tell that it is worth buying rather than building.
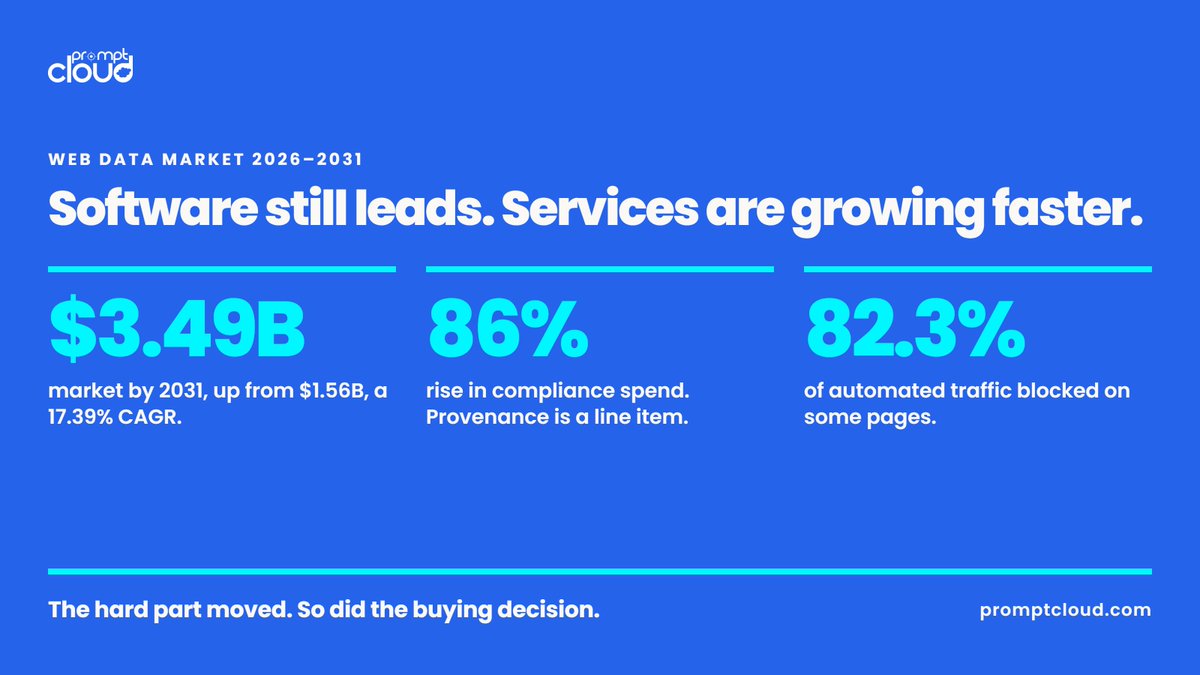
PromptCloud is among the providers covered in the report. Explore our web scraping services for a closer look at the infrastructure behind these use cases: https://t.co/7u8r3zxgm9
Web scraping now powers ~67% of alternative data programmes at US investment advisers, up 20 points in a year.
With financial services accounting for 29% of scraping spend, auditability isn't optional.
Where did the data come from, when was it collected, and under what basis?
This week: AI scrapers reclassified as an attack surface, 40,000 creator records assembled from public fields and sold, and a litigation tracker where publishers appear as both plaintiffs and partners.
Permission is no longer something you document after the build.
For teams building AI-ready data pipelines, compliance needs to start upstream. Explore PromptCloud’s data governance solutions: https://t.co/JU65GzJ7Ih
40,000 Twitch creator records are up for sale. Researchers think it was a scrape, not a breach.
People read that as the good news, it is not.
Every field was individually public. Collected into one file they become a profiling kit. Aggregation is the harm.
The web was built on indexing and extracting information from publicly available pages in the first place. Learn more about web scraping and outsourcing at https://t.co/tKOkMKLKUZ
A judge just dismissed Google's DMCA suit against a company that scrapes Google's own search results. Public facts are not copyrighted, the ruling says.
Google built its entire index by scraping the open web the same way, hypocritical corner to be in.
An AI scraper demo in thirty lines of Python looks easy. Self healing extraction, JavaScript handling, structured JSON output, all real.
None of it solves rate limits, IP rotation, anti bot defenses or schema drift at scale.
Fewer than a third of South African news sites can actually block AI crawlers.
Extraction without compensation is not a South African problem. It is a consent problem, and it starts upstream of any block list.
If you’re dealing with AI compliance or need better control over the data feeding your compliance workflows, PromptCloud’s Compliance Data Governance solution could be useful: https://t.co/0keU6cUU65
Smarsh cut compliance review workload using AI on AWS. That image holds up only if the data feeding the model was governed before it arrived. Governance starts at collection, not at review.