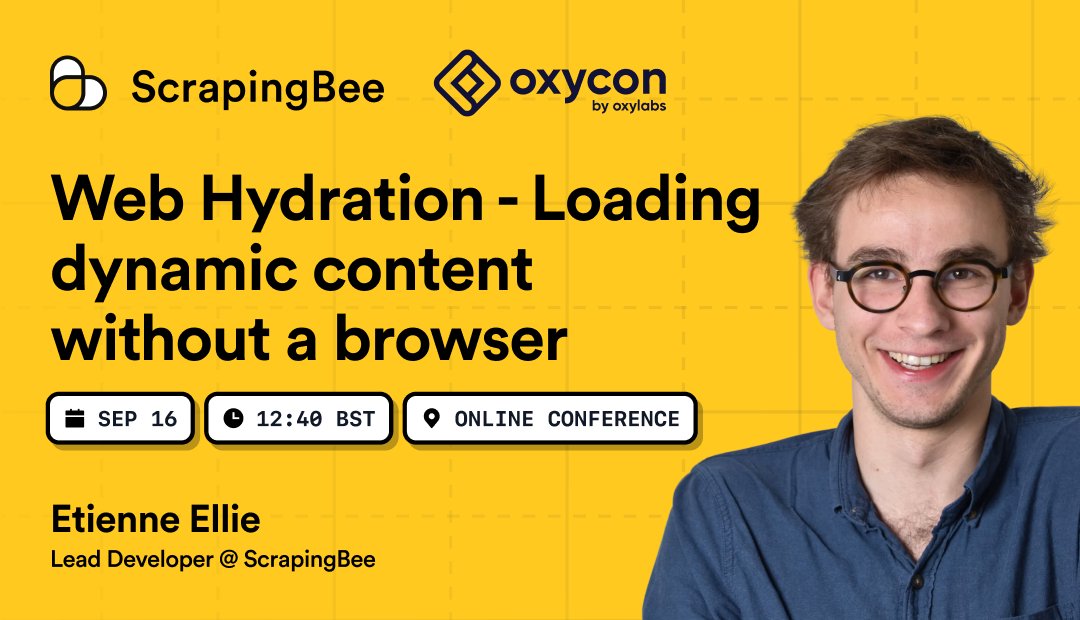
What actually happens under the hood during Web Hydration? Our lead engineer, Etienne Ellie broke this down live at OxyCon, and the demo repo is now public
https://t.co/1petODuYkX
If web scraping is core to your work, keep this on your radar. Tomorrow at OxyCon® 2026, our Lead Engineer, Etienne Ellie, presents Web Hydration: Loading Dynamic Content Without a Browser.
Register for free: https://t.co/fEqJzCOV5h
#oxycon
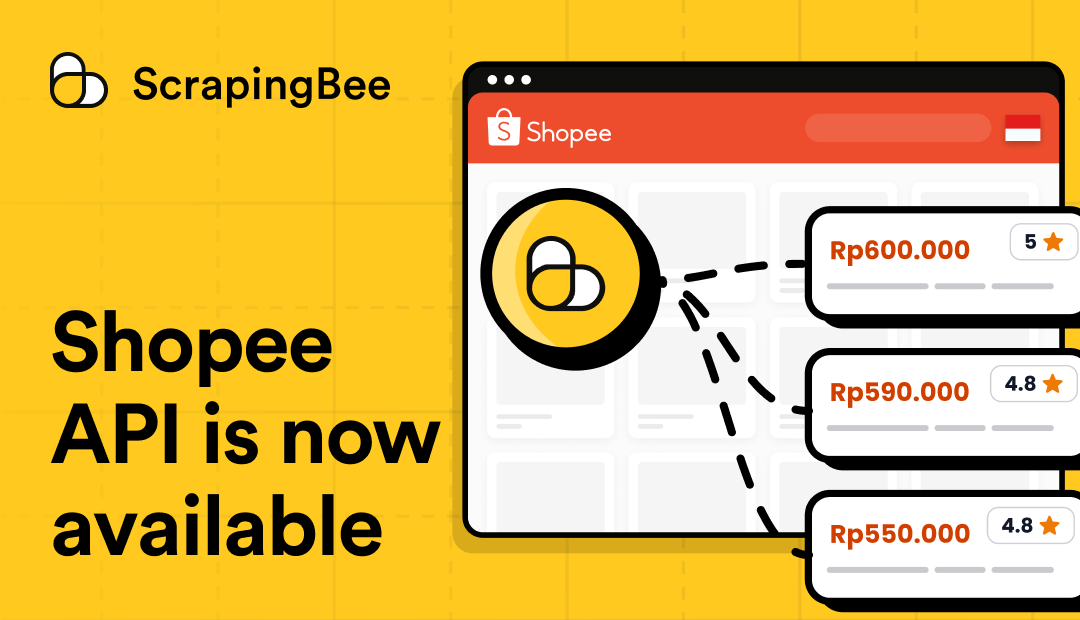
From prices and product variants, up to seller info and category data - all essential product data from Shopee Indonesia is now easy to extract with our freshly released Shopee API.
Docs are right this way: https://t.co/vK9nBhwL96
Need to find data analysts in France, software engineers in Portugal working for US firms, or Fortune 500 CTOs?
Skip setting up complex search filters. With our Agentic Employee Search, describe who you need in a plain English prompt and get structured profiles back in seconds.
Docs linked below 👇
https://t.co/xDFSswVnys
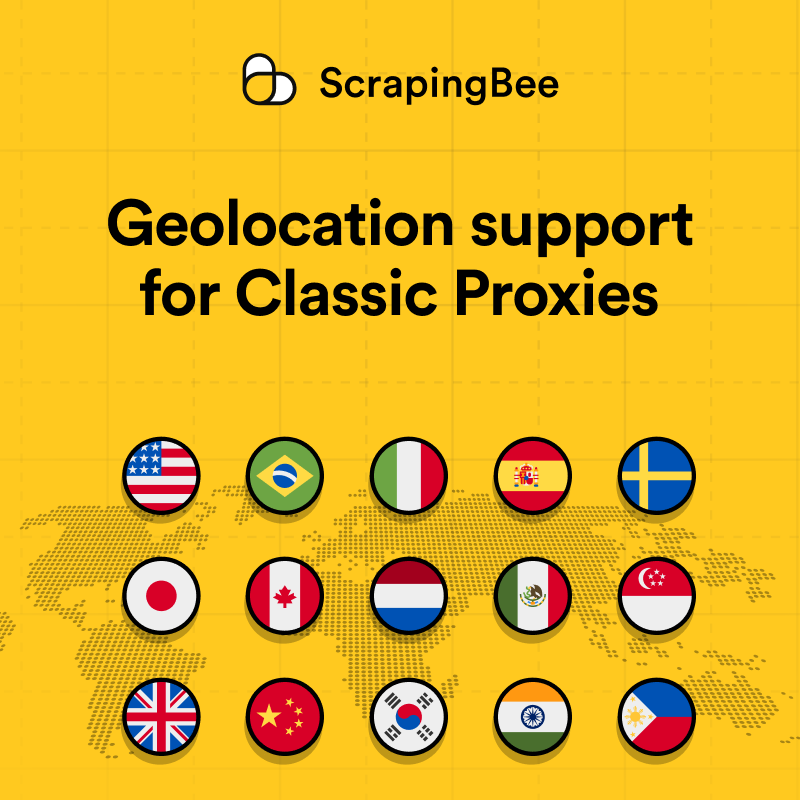
From Brazil to Australia, our classic proxies now support 42 countries.
Testing localized content in Tokyo? Tracking prices across European markets? Scraping geo-specific data from Canada? Just pick your country from the dropdown.
The full list of supported countries is right this way https://t.co/WkC29ZNbSm
Fresh from the hive: Auto-Mode is live.
The problem? Every scraping target behaves differently. One blocks standard proxies. Another needs JS rendering. A third requires premium infrastructure.
Auto-Mode solves this. Add mode=auto and it tests configs automatically, starting simple and escalating only when needed. Stops at first success.
Set max_cost to cap how far it goes. Check sb-auto-cost to see what worked.
Manual mode stays for full control. Auto-Mode is for when you want extraction to just work.
The ScrapingBee CLI now has Interactive Mode (REPL).
Run scrapingbee without arguments and you get a persistent terminal session. Set parameters once with :set and they stick across every command. Type :view to check results without opening files. Watch crawl progress in real time.
You stop arrow-up-editing the same 200-character command five times to test one flag change.
Live in v1.5.0+. Upgrade: uv tool upgrade scrapingbee
Docs: https://t.co/ecNEVw3Y49
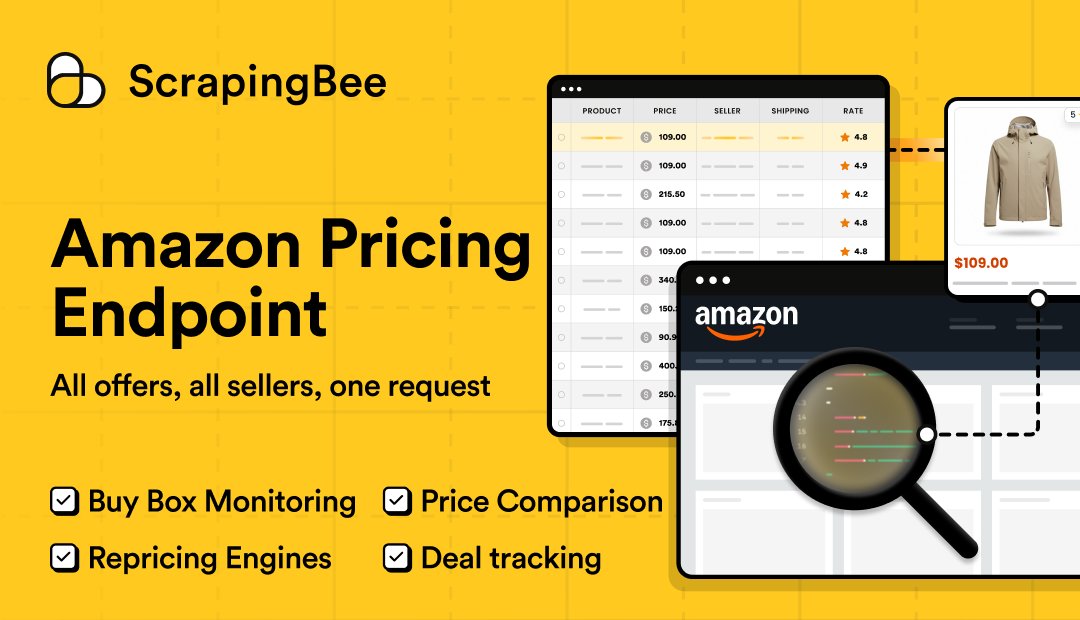
If you're tracking Amazon prices, you probably need more than just the Buy Box winner. Our new Pricing endpoint gives you the full seller stack for any ASIN: who's winning the Buy Box, what everyone else is charging, FBA vs merchant-fulfilled, shipping, Prime eligibility, ratings
Geolocation targeting for Google APIs is live.
Now, you can run searches from exact coordinates instead of country-level targeting. Set latitude, longitude, and radius in meters.
Docs 👉 https://t.co/A3SHg8v2aj
Your ScrapingBee account just got a direct line to Google Gemini.
You can now send a prompt to /api/v1/gemini, get back structured answers in plain text, markdown, and with citations. Same API key, same infrastructure, now connected to Gemini.
Docs: https://t.co/ox1w2ag3ae
"Why can't I just pull all the ads Google shows for a keyword?"
You can now.
Our Google API supports search_type=ads and returns every ad position + full copy, sitelinks, extensions
Same endpoint, same cost as a standard search
ScrapingBee just upgraded: 2x to 5x more concurrent requests across all plans.
We improved our infrastructure to deliver faster job completion and more headroom for production-scale workflows. The upgrade is already live.
Hey devs and tech product folks! This is the second and last day of @devworld_conf in Amsterdam!
There's a lot happening on each stage today, but if you're here – make sure to stop by our Booth T007 and chat with our team!
Your AI coding agent keeps failing to scrape dynamic pages?
Give it eyes.
ScrapingBee CLI handles the JS rendering, anti-bot defenses, and messy HTML so your LLM can actually get the data.
pip install scrapingbee-cli
3 days until @devworld_conf !
Amsterdam is officially the AI capital this week. 🇳🇱 Our team is buzzing to talk web data and building AI products. 🐝
Will you be there? Come find us at Booth T007!
Heads up, devs! ScrapingBee just achieved SOC 2 Type 2 compliance.
Secure data handling for your web scraping projects, validated. Long story short - focus on your code, devs, we've got the compliance. 🐝
Your terminal just got superpowers.
ScrapingBee CLI is live: → Batch process thousands of URLs → Schedule recurring scrapes with cron → Extract data with plain English AI rules → Export RAG-ready chunks for your LLMs
Docs: https://t.co/MpHIiakMl6