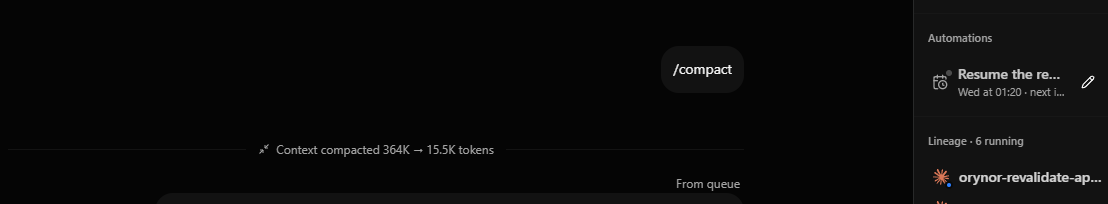
@theo Following up on a thread and forcing auto compacting is annoying make it an option instead, there was no need for the thread to compact on a follow up
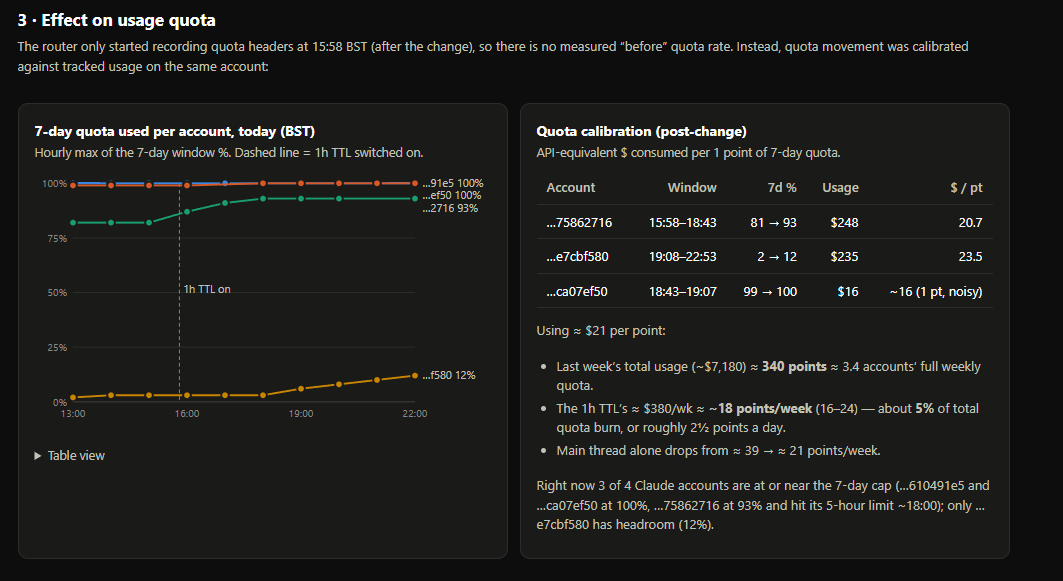
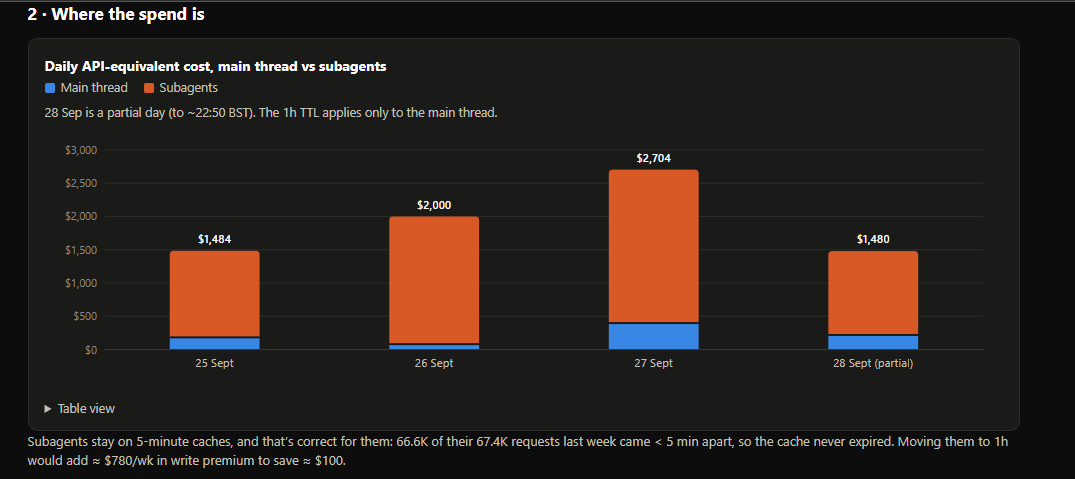
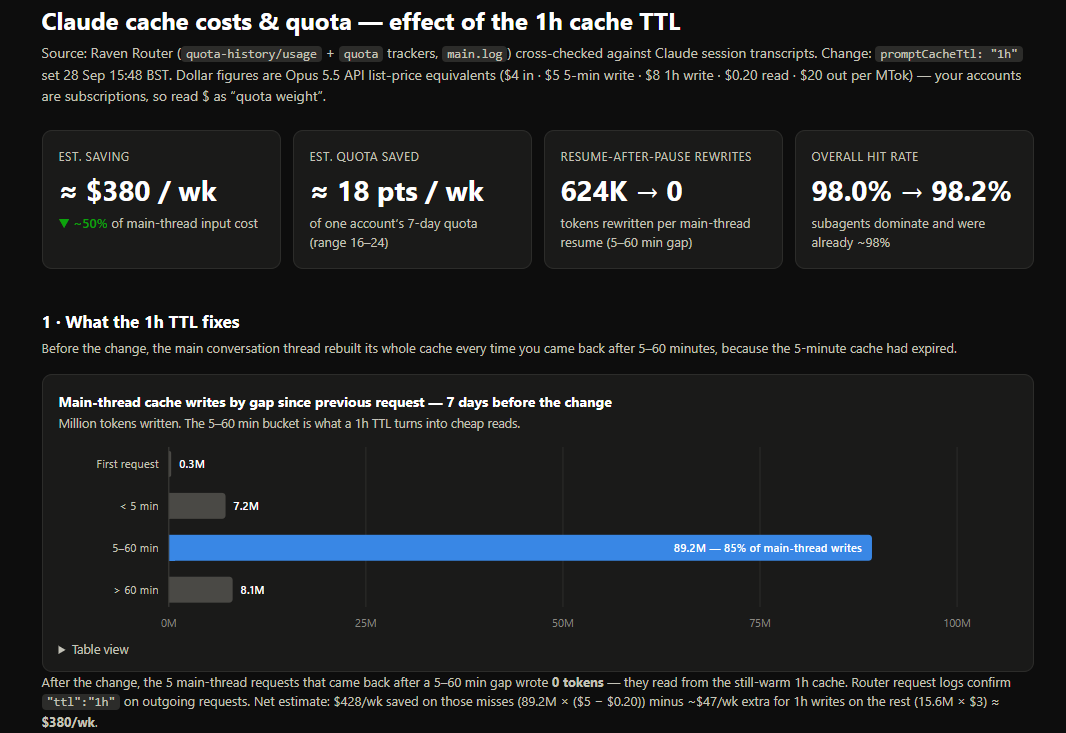
I have found out why my usage is burning considerably more then it should
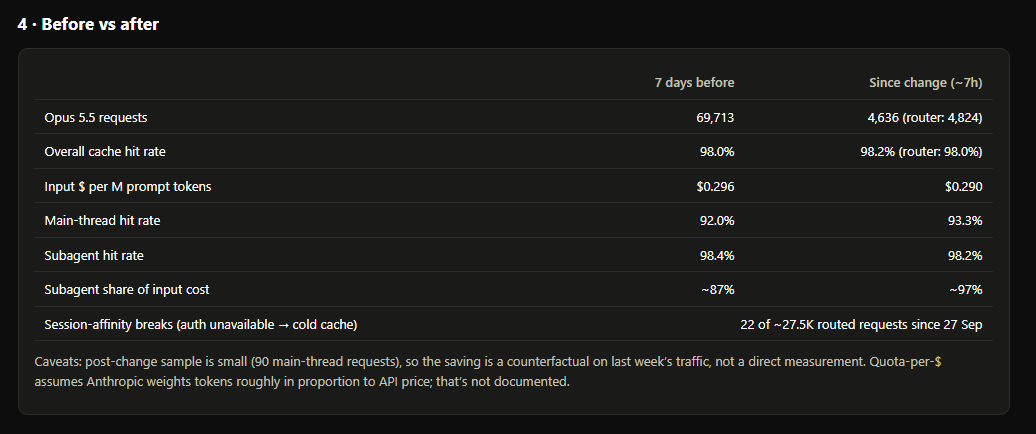
When using a proxy through t3 code it sends the request upstream as an api key endpoint which makes the cache TTL only 5 mins instead of 1 hour
This results in increases in cache reads and increases usage
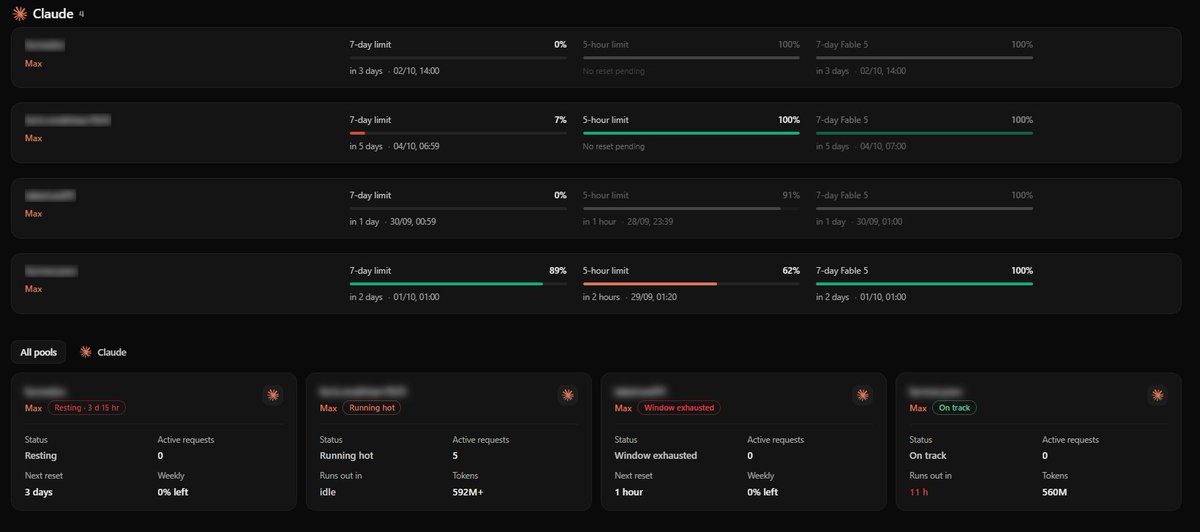
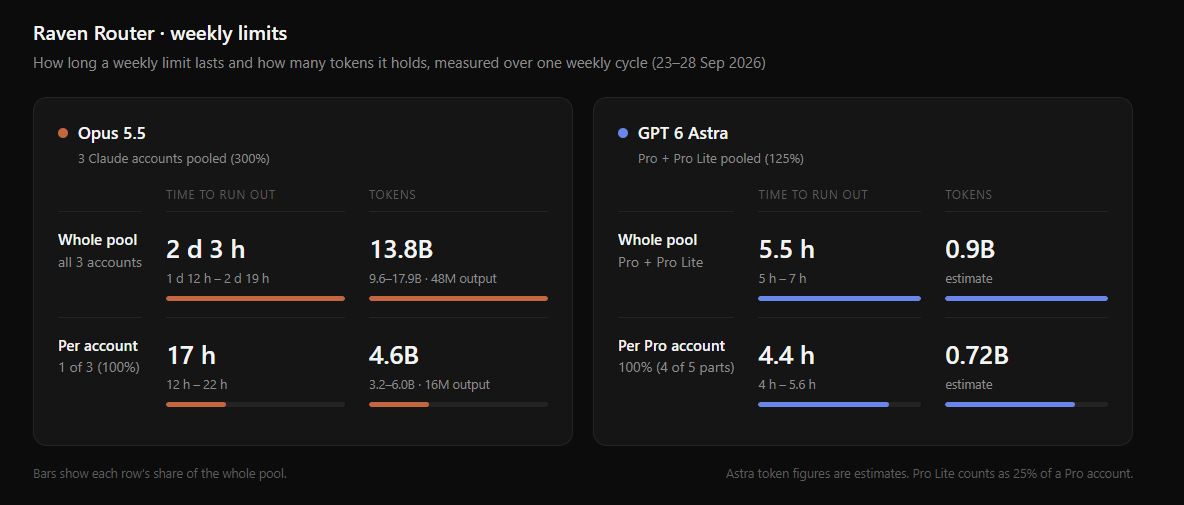
@theo Opus has given me ai psychosis, on 3 20x accounts the weekly only lasts an average of 2 days combined, i built in a tracker in my quota page, the limits are exponentially better then fable but the only model that felt unlimited was gpt 5.5.
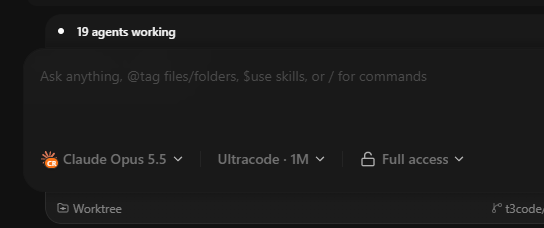
I only use ultracode for one off tasks, not ongoing threads. This was an audit, fix and verify across auth, db migrations and aws perms, without having to babysit, wouldn’t manually calling workflows burn the same amount of tokens regardless? Weekly is definitely substantially better than fable or astra, regardless 5 hour is still a major bottleneck for any workflow task
@JohnnyS89206078@theo I've had astra run 96 subagents at once and take an expected chunk of usage out, my point is claude plans are not sustainable for large subagent orchestrations and any sort of subagents in a thread burn through limits unlike codex
@theo i drained all my limits in a couple of hours before using the banked resets and i think claude plans just can't sustain large subagent orchestration, the 5 hour limit especially is honestly tiresome