Hey @massive_com — I signed up with my university email to use your API for an independent quant research project. Your KB documents a 20% education discount for university signups. Emailed sales, no reply yet — who's the right person to ask?
@morphic since support is ignoring my refund request after burning 60%+ of my monthly credits on a single 8-sec video, I have officially filed a complaint with the European Consumer Centre (ECC Austria) for breach of EU Directive 2019/770.
I’ve also initiated a card chargeback.
@berlinairport@swissport@Ryanair Thank you, Alma. I have sent a detailed email containing the exact date (26 Aug ~2:15 PM), location (T2 Ryanair bag drop), physical description, and full account to [email protected]. I look forward to an update once CCTV has been reviewed.
Unacceptable service at @berlinairport T2 on 26 Aug around 2:15 PM. A @Swissport agent (yellow jacket, red hair, ~1.53m, heavy makeup) completely ignored waiting passengers at the crowded @Ryanair self bag-drop area to stay on a personal phone call.
@berlinairport@swissport@Ryanair Leaving a parent to struggle alone with small children in a high-pressure environment while actively refusing to work was deeply upsetting and ruined our journey. I have lodged formal complaints and demand a full CCTV review by management! @Swissport@Ryanair
@berlinairport@swissport@Ryanair I was struggling alone with kids in a chaotic terminal. I asked her politely to help waiting families, but she condescendingly said "Darling, this isn't my job" and walked off to the restrooms to continue her private chat.
Some days the hardest part is just starting the day.
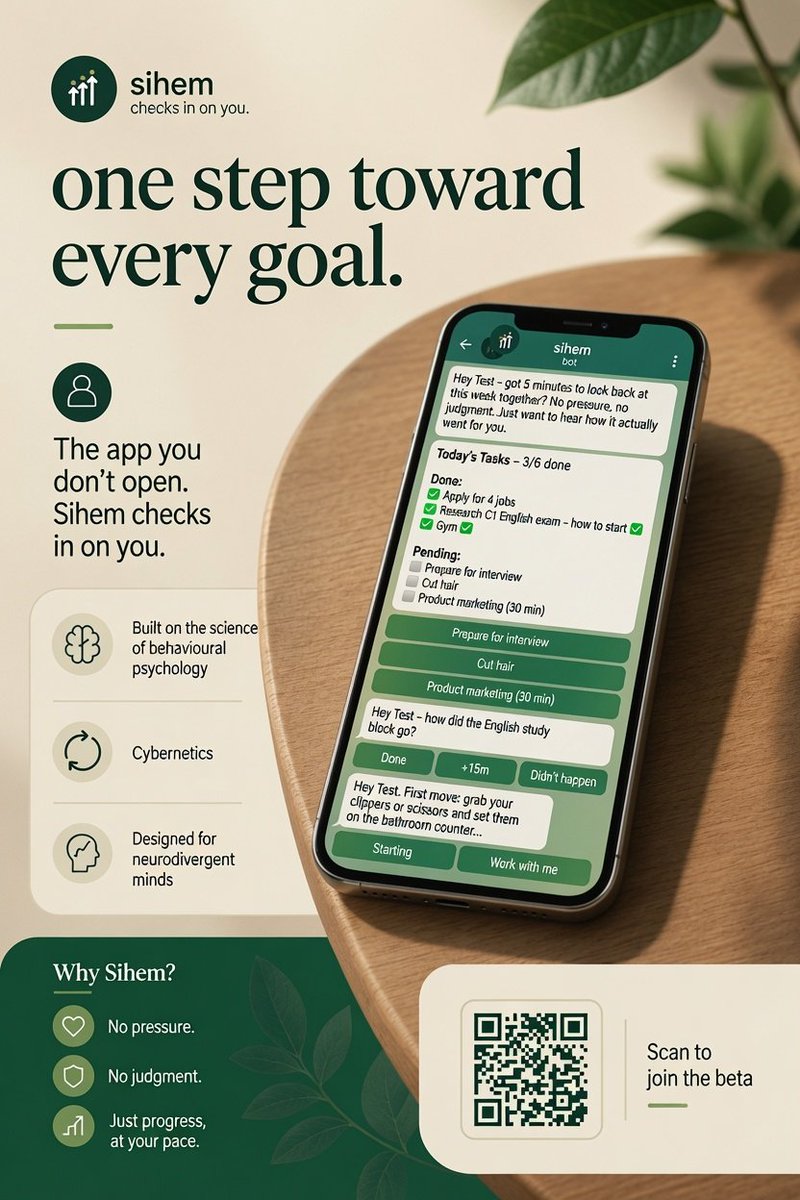
Sihem is the quiet mentor that comes to you — not the other way around.
Warm when you need warmth.
Honest when you need clarity.
Always low-pressure.
For ADHD and AuDHD brains that are tired of tools made for someone else.
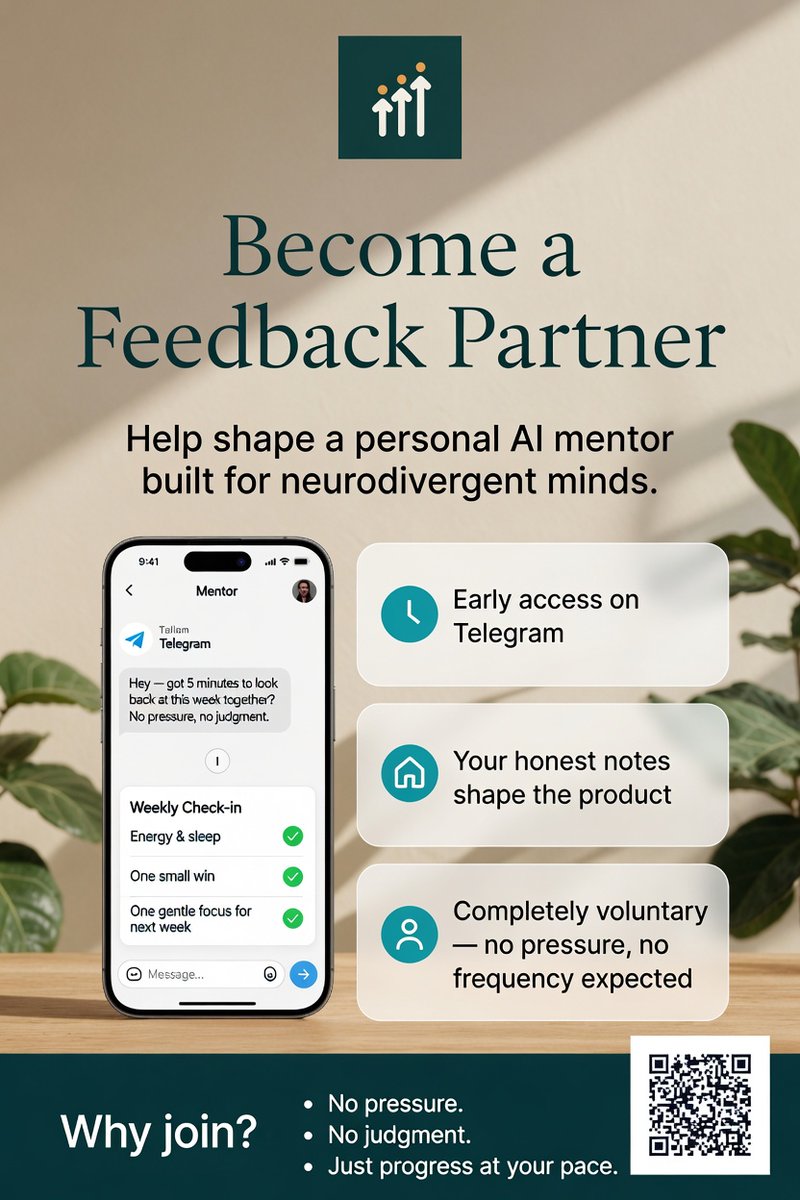
Sihem is a personal AI mentor that lives in Telegram.
I’m inviting a small group of Feedback Partners. Early access. Your honest notes shape the product. Completely voluntary.
#ADHD#Autism#Neurodivergent#AuDHD#Neurodiversity
@jpshrodinger I built Faultrix because I realized the advanced anomaly detection AI I was researching could solve a massive bottleneck in the physical world. It takes the subjective, manual process of building inspections and turns it into an automated and precise workflow.
How to use both Claude Fable 5 and GPT-5.6 all day without hitting limits.
Most people don't know you can run both inside the same session.
Fable 5 as the orchestrator. GPT-5.6 as the executor. 10 subagents working in parallel.
This setup saves at least 60% of your Fable 5 token consumption — and you never hit the 5-hour limit again.
You only need to set it up once. Here's exactly how:
━━━━━━━━━━━━━━━━━━━━━━━━━━
STEP 1 — Install the Codex plugin inside Claude Code
Run these three commands:
/plugin marketplace add openai/codex-plugin-cc
/plugin install codex@openai-codex
/reload-plugins
━━━━━━━━━━━━━━━━━━━━━━━━━━
STEP 2 — Tell Fable 5 to finish the setup
Paste this prompt into Claude Code:
"Set up Codex inside this Claude Code environment. Use the official OpenAI Codex plugin that was just installed. Run /codex:setup. If Codex CLI is missing, install it. If Codex is installed but not authenticated, ask me to authenticate with my ChatGPT account. After auth is complete, verify that Codex works from inside Claude Code. Then confirm that the codex:codex-rescue sub-agent is available. Do not change any project code during setup."
━━━━━━━━━━━━━━━━━━━━━━━━━━
STEP 3 — Authenticate once
Fable 5 will trigger the Codex setup automatically.
You authenticate your ChatGPT or Codex account once.
After that, Codex runs from inside Claude Code using your existing Codex subscription — no extra cost, no extra setup.
━━━━━━━━━━━━━━━━━━━━━━━━━━
STEP 4 — Tell Fable 5 how to delegate work
Paste this prompt:
"From now on, use this workflow:
You are the orchestrator.
Use Fable 5 for planning, repo understanding, architecture decisions, task decomposition, and final review.
Use codex-rescue as the executor when a task needs heavy implementation, debugging, test fixing, refactoring, or multi-file code edits.
When delegating to Codex, use /codex:rescue.
Prefer GPT-5.6 Sol medium as the daily driver for implementation tasks.
Keep Codex tasks focused and specific.
After Codex finishes, inspect the result yourself before accepting it.
Do not blindly trust Codex output."
━━━━━━━━━━━━━━━━━━━━━━━━━━
WHICH GPT-5.6 MODEL TO USE AND WHEN
This is where most people leave money on the table. Not all GPT-5.6 tiers are equal.
GPT-5.6 Sol medium → your daily driver
DeepSWE score: 61. Cost: $1.86. Fewer steps than almost every other model on the benchmark. This is the model doing 80% of the execution work in this setup. Fast, cheap, accurate enough for most implementation tasks.
GPT-5.6 Sol extra high → planning and orchestration
DeepSWE score: 71. Cost: $4.70. Use this when the task needs serious reasoning — architecture decisions, task decomposition, complex debugging. Scores higher than Fable 5 extra high (70) at less than a third of the cost ($13.41 vs $4.70). This is the model that replaced Fable 5 as my planning layer.
GPT-5.6 Terra/Luna → pure execution
Fast. Cheap. No overthinking. Once the plan is locked, this is what runs it. Extremely fast execution, minimal bugs, high quality output on well-defined tasks.
━━━━━━━━━━━━━━━━━━━━━━━━━━
THE ULTIMATE PLAN: 3-MODEL WORKFLOW
If you want maximum output quality at minimum cost, this is the setup:
Step 1 → Plan with GPT-5.6 Sol extra high
Full task/session/project planning. Architecture. Decomposition. Edge cases.
Step 2 → Critique with Fable 5 high
Find loopholes. Patch loose ends. Challenge assumptions. Fable 5 is at its best here — pure reasoning, no implementation cost.
Step 3 → Execute with GPT-5.6 Terra/Luna
Implement the battle-tested plan. Fast, clean, no waste.
TLDR:
Plan → GPT-5.6 extra high
Critique → Fable 5 high
Execute → GPT-5.6 Terra/Luna
The orchestrator thinks. The critic patches. The executor builds. You review.
━━━━━━━━━━━━━━━━━━━━━━━━━━
4 PRO TIPS TO NEVER HIT A LIMIT AGAIN
→ Tip 1: Turn this into a skill
Name it Fable-GPT. Call it at the start of every session. One command activates the entire workflow — no re-pasting prompts every time.
→ Tip 2: Use skill + goal for heavy tasks
Goals are best for long-horizon work. Set the goal, activate the skill, let the orchestrator-executor loop run until it's done. Check back when it surfaces for review.
→ Tip 3: Use subagents if you're on the Codex 20x Pro plan
Run 5 to 7 parallel subagents at once. With this setup, you will never hit the 5-hour limit. Each agent works independently on its assigned task while the others run in parallel.
→ Tip 4: Clear context after 4 compactions
Context rot is real. After 4 /compact cycles the conversation quality degrades. Use a /handoff skill before clearing to preserve the critical context — task state, decisions made, what's left to do. Start the new session by loading the handoff file.
━━━━━━━━━━━━━━━━━━━━━━━━━━
THE FULL PICTURE
Before this setup:
→ Fable 5 hits limits by midday
→ Heavy implementation burns your best tokens
→ You manually switch between tools
→ One model, one pace, one bill
After this setup:
→ GPT-5.6 Sol medium handles 80% of execution at $1.86/task
→ GPT-5.6 extra high outplans Fable 5 at 3x lower cost
→ 3-model critique loop catches every bug before it ships
→ 5 to 7 parallel subagents running simultaneously
→ 60%+ fewer Fable 5 tokens consumed
→ Never hit the 5-hour limit again
One setup. Runs forever.
Save this. Set it up tonight.