A personal update 🙏
After an incredible journey, I've decided to close my chapter as part of the MemeX team.
It was a fantastic adventure. I helped grow the community, supported the timeline every day and shared the vision from early on. I'm proud of what we built together, and grateful for every builder, mod and memer I met along the way.
But growth means listening to yourself. My personal development, vision and ambition are pulling me toward a new path, one where I build on my own terms.
To the MemeX team and community: thank you for the ride. I wish you nothing but the best. 💚
What's next? A new chapter is loading. Stay tuned. 👁️🚀
— Allan
Project spotlight 🔍 llama.cpp
Open-source C/C++ engine (MIT) that runs LLMs on laptops, phones and plain CPUs. A lot of local AI tools are built on top of it.
Why it matters: your own hardware, your own data.
Have you run a model fully offline yet?
DeepSeek just open-sourced DeepInfer, the in-house engine it uses to run V4.1 Flash faster and cheaper on Nvidia and Huawei chips.
My take: the model race gets the headlines, but the cost of each answer decides who actually scales. 👁️
GM ☀️ Midweek truth.
You don't need more ideas. You need to finish the one you already started.
Pick it. Block one hour. Ship something small before lunch.
What are you closing out today?
Tuesday wrap 🌙
Small wins still count. A fixed bug, a better question, helping someone get unstuck. That's a good day.
Grateful for everyone building in public and sharing what they learn.
What's one small win you're taking to bed tonight?
Builder tip 🛠️ Don't ask AI for "the answer."
Ask: "Give me 3 options and the trade-off of each."
One answer feels like certainty. Three options make you think. You stay the decision-maker, and you spot the weak idea faster.
Project spotlight 🔍 E2B
Open-source sandboxes for AI agents. Every session gets its own isolated microVM to run code, with its own firewall. Apache-2.0, and you can self-host it.
Why it matters: agents need room to act without touching what matters.
Where do your agents run?
Amazon just launched TorchNeuron: existing PyTorch code runs on its Trainium chips with one setting change, no rewrite. It goes open source today at PyTorch Conference.
My take: the chip war is now a software war. Whoever makes switching painless wins the builders. 👁️
GM ☀️ Quick reminder for Tuesday.
Don't measure yourself against someone else's highlight reel. Measure against who you were last month.
Slightly sharper. Slightly calmer. Slightly further.
That's the only race that counts.
Where have you grown since September? 👇
Monday wrap 🌙
The week didn't need a perfect start. It just needed a start.
Grateful for everyone who showed up today and kept going, even when it felt slow.
What's one thing you're carrying into tomorrow?
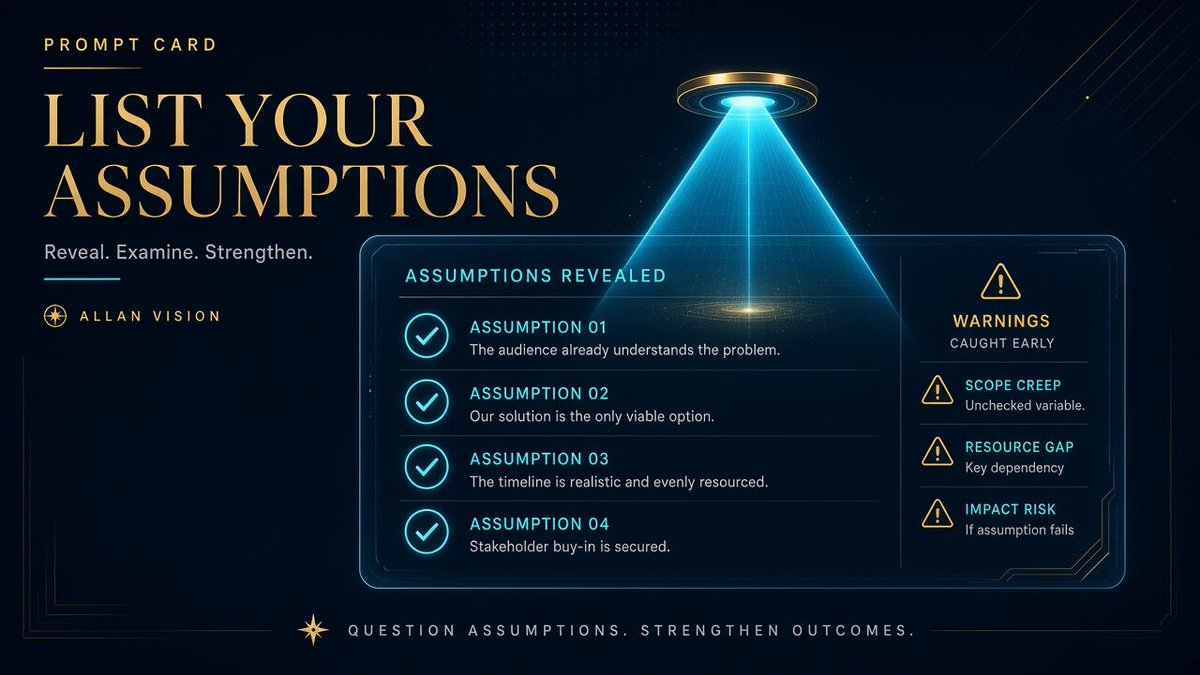
Builder tip 🛠️ Add one line to the end of your prompts:
"Before answering, list the assumptions you're making."
You'll catch the wrong guesses before they turn into wrong answers. Saves more time than any fancy template.
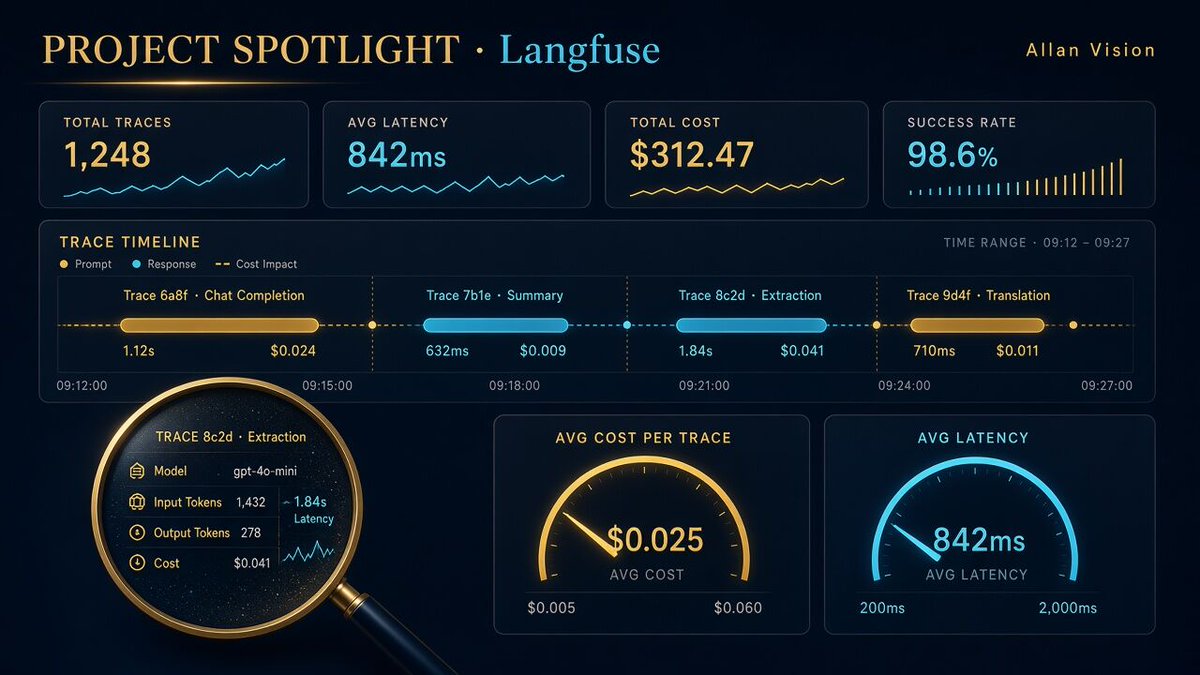
Project spotlight 🔍 Langfuse
Open-source platform to trace, evaluate and debug LLM apps. Every prompt, response, cost and latency in one place, plus evals on real traffic.
Why it matters: you can't improve an AI product you can't see.
How do you test your AI outputs today?
Reflection just released Beam's weights under Apache 2.0.
501B params, only 23B active per token, 1M-token context. Built for coding and agents.
My take: open doesn't mean easy. Even the compressed version is 273 GiB. The real gap now is hardware and the stack. 👁️
GM ☀️ New week, clean slate.
Skip the 20-item to-do list. Pick the one thing that actually moves you forward and do it first, before the noise starts.
Everything after that is a bonus.
What's your one thing this week? 👇
Sunday wrap 🌙
Quiet days are where the loud weeks get built.
Grateful for the builders who share what actually worked — not just the highlight reel.
One question: what's the one thing you're protecting focus for this week? 👁️
Builder tip 🛠️ One task per chat thread.
When you mix research, drafting, and debugging in one conversation, the model loses the plot — and so do you.
Fresh thread. Clear goal. Better output.
Try it on your next hard problem. 👁️
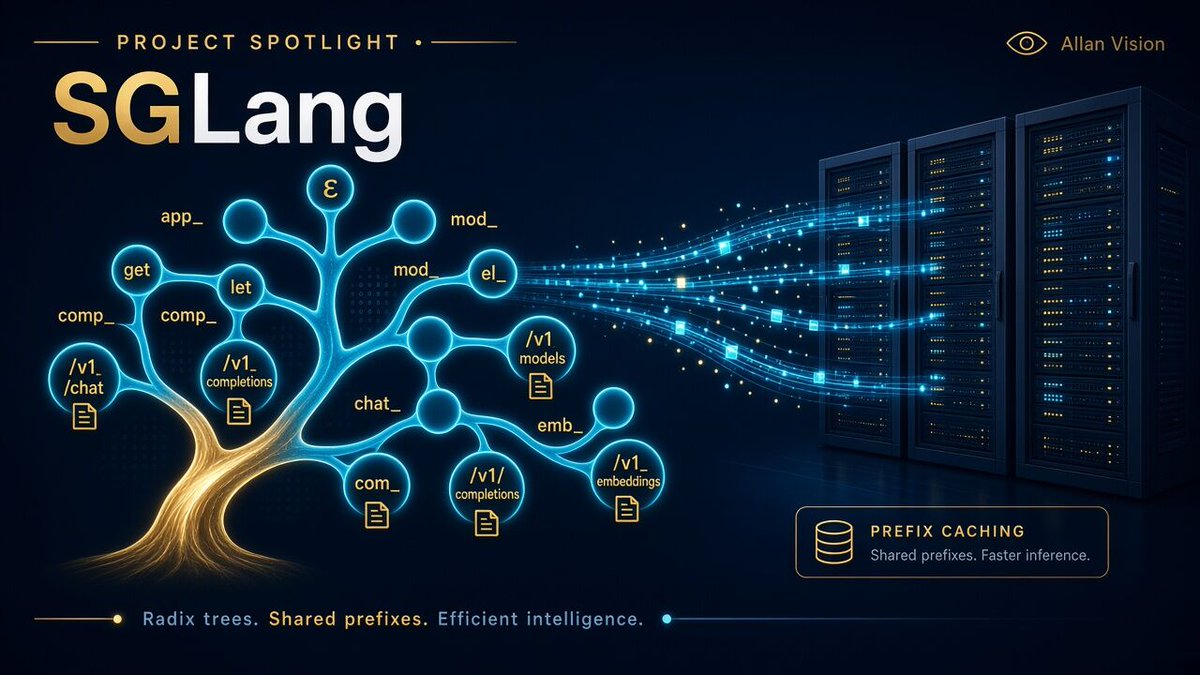
Project spotlight 🔍 SGLang
Open-source LLM serving from LMSYS. RadixAttention for prefix caching, OpenAI-compatible APIs, one GPU to big clusters.
Why it matters: agents need fast inference, not just clever prompts.
Self-hosting yet, or still on hosted APIs? 👁️