Arrow-optimized Python UDFs are on by default in Apache Spark 4.2: existing UDFs take the faster columnar path with no rewrite, dropping the row-by-row JVM/Python serialization cost. Plus Pandas 3 and zero-copy handoff to Polars and @duckdb.
🔗 Download Spark 4.2: https://t.co/i96ON3AVx4
#ApacheSpark #PySpark #ApacheArrow #Python
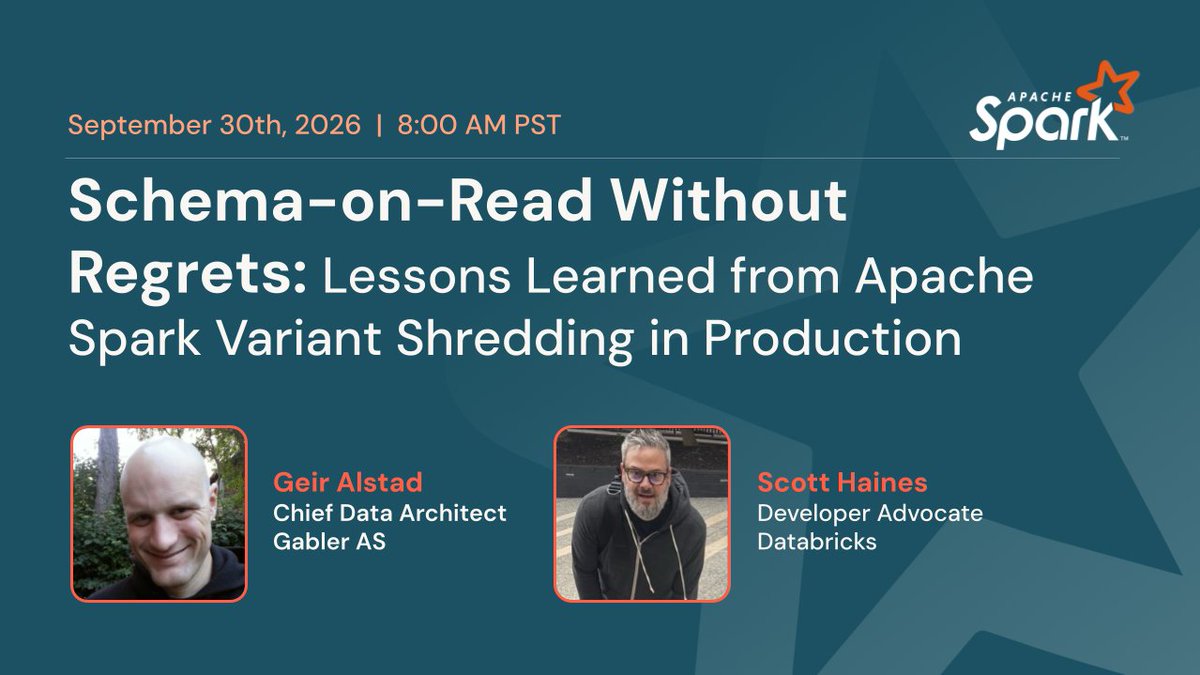
Join us next Wednesday for Schema-on-Read Without Regrets!
Geir Alstad (Gabler AS) and @newfront (@databricks) will walk through Spark Variant shredding in a real pipeline.
🗓️ Wed, Sept 30 · 8:00 AM PT
🎟️ Register: https://t.co/9S3AvF68nd
#ApacheSpark
Open Lakehouse + AI hits Bellevue in two weeks! 🎉
Felix Cheung (@nvidia) will cover GPU-accelerated Spark, Delta Lake, Iceberg, and Spark Connect. Micah Kornfield (@databricks) on a unified future for @DeltaLakeOSS and @ApacheIceberg, plus a panel on connecting the open lakehouse and AI ecosystem.
🗓️ Wed, Oct 7
🕜 5–9 PM PDT
📍 Databricks Bellevue
Register: https://t.co/qssOg3jNz1
#ApacheSpark #ApacheIceberg
Apache Spark 4.2 is out, and it adds vector primitives to Spark SQL: distance and similarity functions, normalization, aggregation, and NEAREST BY (a top-K ranking join). Retrieval and recommendations run in SQL at Spark scale, next to your data.
🔗 Download Spark 4.2: https://t.co/i96ON3AVx4
#ApacheSpark #VectorSearch #SparkSQL
At Airflow Summit, Meni Shmueli from DataFlint covers how #ApacheSpark and @ApacheAirflow run together in production, including splitting CPU work (like reading Parquet) off GPU machines so AI jobs aren’t paying GPU rates for CPU-only steps.
Apache Spark 4.2 is out: auto CDC and Real-Time Mode for streaming, DataSketches as first-class operators, and Spark Connect so client/server queries come back in milliseconds instead of spinning up a full app.
#SparkConnect #DataSketches #ApacheAirflow
📣 Schema-on-Read Without Regrets: Lessons from Apache Spark™ Variant shredding in Production
Join Geir E. Alstad (Gabler AS) + @newfront (@databricks) on Tuesday, Sept 30 at 8 AM PT. 🗓️
Learn how Variant shredding turns schema-less XML into fast streaming tables and a clean Kimball star schema, with real lessons on schema drift, reloads, and the Medallion Spoke pattern.
🎟️ Register: https://t.co/HxvYSODVRu
#OpenSource #ApacheSpark #Schema
Real-Time Mode now reaches PySpark in Apache Spark 4.2, out now: stateless streaming queries (no Python UDFs) at millisecond end-to-end latency, a path previously reachable mainly from the JVM. Stateful + UDF support is in progress for an upcoming 4.x (SPARK-54699).
🔗https://t.co/i96ON3AVx4
#ApacheSpark #StructuredStreaming #RealTime #PySpark #Streaming
In this video, @lisancao walks through Apache Spark 4.2, starting with metric views: define the measure once in YAML, store it in the catalog, and everything downstream hits the same number.
🔸 Real-time mode — Structured Streaming at millisecond latency; same DataFrame API. Now in PySpark for stateless queries
🔸 Vector search in Spark SQL — top-K nearest join on the arrays you already have. No extra vector store
🔸 Arrow-batch Python UDFs on by default, no code change
🎥 Watch: https://t.co/i9w50mGquD
#ApacheSpark #Spark #PySpark #OpenSource
Apache Spark is built for large, fault-tolerant jobs: query plans, stages, tasks, and retries. On small local data, such as about 20 MB of Parquet or JSON, those scheduling steps can add roughly 100 milliseconds each, and the iteration loop gets slow.
Project Feather is a SPIP to make that laptop and local-mode loop faster without a new engine or API changes. Spark committer Daniel Tenedorio, a co-author of the proposal, walks through the work here 👉
https://t.co/8GsyKsUaka
#ApacheSpark #OpenSource #DataEngineering #Spark
Data Source V2 takes a major leap forward in Apache Spark 4.2, out now. 👇
First-class CDC through the new CHANGES clause, behaving consistently across connectors. SELECT * FROM orders CHANGES FROM VERSION 10 TO VERSION 20;
Also MERGE INTO codegen, INSERT schema evolution, UPDATE/DELETE metrics, and transaction API foundations.
🔗 https://t.co/i96ON3BtmC
#ApacheSpark #Lakehouse #CDC #DataSourceV2 #DataEngineering
A lot of data engineers end up hand-rolling CDC, and the edge cases are where it breaks.
In this video, Anish Mahto and Andreas Neumann walk through Auto CDC in Spark Declarative Pipelines:
🔹 Declare your change data feed and SCD Type 1 or Type 2; SDP handles reconciliation
🔹 Type 1 in Spark 4.2; Type 2 code complete for Spark 4.3
🔹 Works with feeds like Debezium, Postgres, or CockroachDB; changes API produces feeds from Delta Lake or Apache Iceberg
🔹 One decorator, or pure SQL
🎥 Watch the full video: https://t.co/azqKCZQ4cm
#ApacheSpark #CDC #DataEngineering
Apache Spark 4.2 is now available and it continues maturing Spark Connect. 🙌
It's a thin client over gRPC and Arrow: the client builds the plan, the server runs it, results return as Arrow batches, no full runtime or JVM on the client. 4.2 also keeps closing the compatibility gap with Spark Classic.
🔗Download Spark 4.2: https://t.co/i96ON3AVx4
#ApacheSpark #SparkConnect #PySpark #ApacheArrow
Apache Spark 4.2 is out. It adds metric views, a semantic layer in Spark SQL: define a metric once in YAML, then query it from SQL, BI, and AI on one governed definition, so ratios and distinct counts stay correct across groupings.
🔗Download Spark 4.2: https://t.co/i96ON3AVx4
#ApacheSpark #SparkSQL #SemanticLayer #MetricViews #DataEngineering
At the Open Lakehouse + AI Meetup on Oct 7 in Bellevue, Felix Cheung (@nvidia) will present: Modern Analytics at GPU Speed: Accelerating Spark, @DeltaLakeOSS, @ApacheIceberg, and Spark Connect
The session covers GPU-accelerated Spark, faster Delta Lake and Iceberg data access, and an end-to-end architecture with Spark Connect.
🗓️Wed, Oct 7 | 5–9 PM PT
📍Databricks Office, Bellevue
🎟️ Register: https://t.co/qssOg3kloz
#OpenLakehouse #OpenSource #ApacheSpark
New video: @lisancao + Szehon Ho (Spark committer / Iceberg PMC) on Data Source V2 (DSV2) and how Spark connects to Iceberg and Delta Lake.
Inside the episode:
🔧 What DSV2 is: richer metadata beyond Hive Metastore
🔄 Unified DML across Iceberg and Delta Lake
📚 Pluggable catalogs + what’s next in Spark 4
Full conversation below 👇 https://t.co/EFdcAMWDRr
#ApacheSpark #DSV2 #ApacheIceberg #DeltaLake
Apache Spark 4.2 is here and brings the modern data and AI stack deeper into the engine.
📊 Governed metrics with metric views
🌐 Spark Connect + Arrow-first PySpark
🤖 Vector search, NEAREST BY, geospatial in SQL
⚡ Auto CDC, CHANGES queries, Real-Time Mode for PySpark
✅ Modernized Web UI, JDK 25, Data Source V2 improvements
🙌 1,900+ commits from 260+ contributors. Thank you to the Apache Spark community.
🔗 Read the full breakdown: https://t.co/y9o1rO5sTx
#ApacheSpark #PySpark #SparkSQL #MetricsViews