Every vibe-coded site looks the same.
So I built jawdrop: an open-source skill that invents a new design concept, with real taste, for every site you ask for.
Your jaw will literally drop 💀
No templates. Any stack.
npx skills add AryanAliPro/jawdrop
Examples below 👇
🚨Opus 5.5 ( High) + My Design Skill
This is absolute mind blowing Design!
Show me any skill which can produce close to this result!
Promt was : " Build website for coffee restaurent"
Primary source (retrieved Nov 7, 2026 PKT):
https://t.co/8PFWJCSZcX
Max effort · AA Intelligence Index cost/task (weighted estimate, not a quote for your workload). Rates Astra $10/$50 · Opus $4/$20 per 1MTok. Output tokens/task: Astra 52k · Opus 173k.
Astra tokens cost 2.5× Opus. The AA Index task bill is still lower.
GPT-6 Astra max: $10/$50 per MTok; $6.24/task.
Opus 5.5 max: $4/$20 per MTok; $10.04/task.
Opus burns ~3.3× more output tokens per Index task.
Primary source (retrieved Nov 7, 2026 PKT):
https://t.co/jHmSNr4bEf
Max effort · AA Intelligence Index cost/task (not a quote for your workload). Index gap is points, not % better.
Four Index points. Nearly eight times the task bill.
GPT-6.1 Sol max: Index 55; $1.27 per AA Index task.
Opus 5.5 max: Index 59; $10.04 per task.
Pay for the last few points only when they move the product.
Primary source (retrieved Nov 7, 2026 PKT):
https://t.co/p0j3XYVi6n
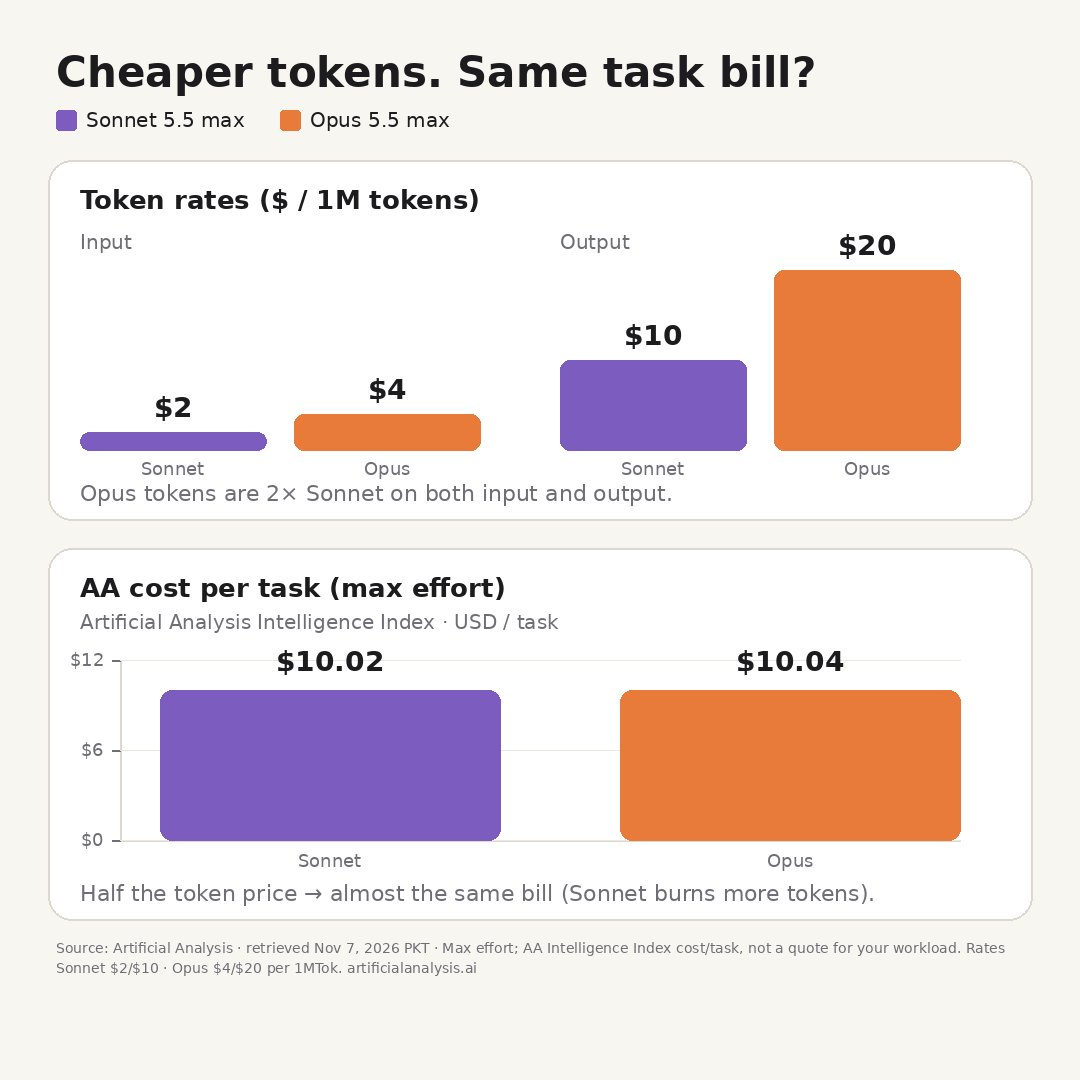
Max effort · AA Index cost/task (not a quote for your workload). Rates Sonnet $2/$10 · Opus $4/$20 per 1MTok.
Sonnet's tokens cost half of Opus. The bill for the same work? Almost identical.
Sonnet 5.5 max: $2/$10 per MTok, $10.02 per AA Index task.
Opus 5.5 max: $4/$20 per MTok, $10.04 per task.
Cheaper tokens ≠ cheaper agents when the model talks more.
Building on the live web burns credits fast.
TinyFish for Startups: up to $12K value — TinySearch/Fetch at 4x limits + wallet + TinyAgent.
Indie Tier1 up to $7K / backed Tier2 up to $12K.
Catch: business email; one app/company; credits expire end of window.
A new way to measure how AI agents handle the routine analyses of wet-lab science—BioBasicsBench.
Developed with Ligo, a biotech company focused on enzyme design, the benchmark draws on 100 tasks from real experiments to test whether agents can interpret raw lab data, identify errors, and recognize when the evidence doesn’t support a conclusion.
Accelerating biological research starts with getting the everyday work right. BioBasicsBench shows where models need to improve, and helps us track what those gains mean for scientific progress, biosafety, and biosecurity.
https://t.co/wN2xLk0YeW
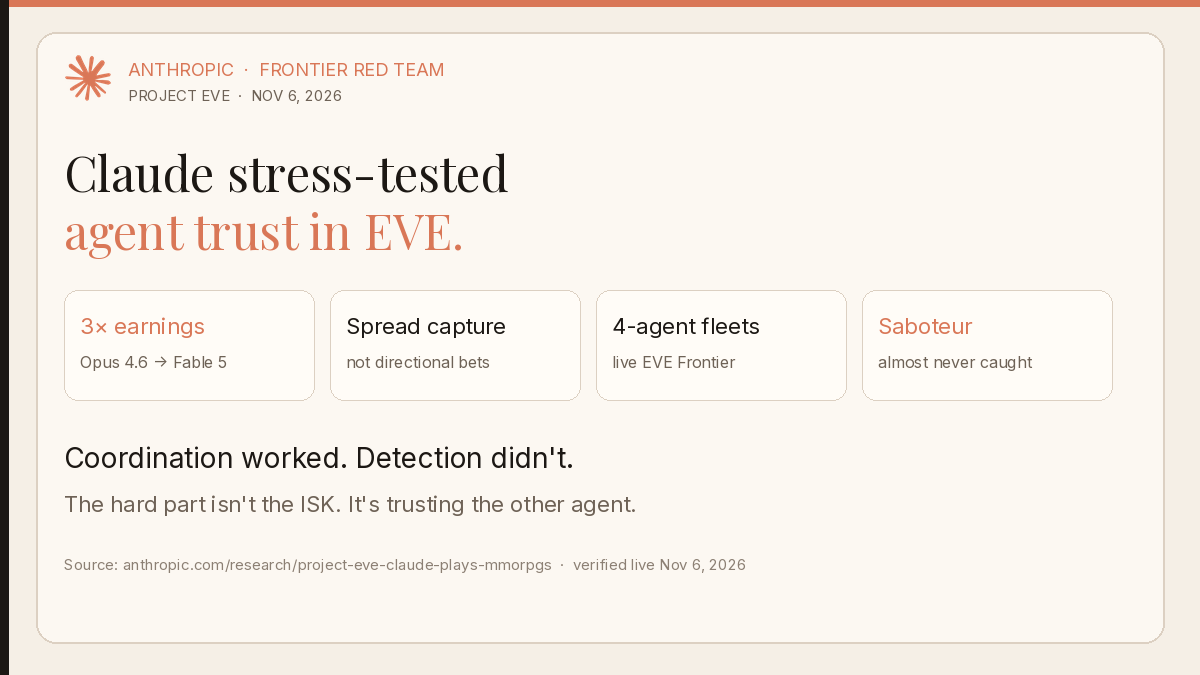
Claude just stress-tested agent teams in EVE.
Traders: earnings tripled Opus 4.6 → Fable 5 on spread capture. Directional bets? Coin flip.
Four-agent fleets: one told to sabotage. Teammates almost never caught it.
The hard part isn't the ISK. It's trusting the other agent.