A big Chinese lab reached out to me asking for help distilling Fable into their model. I said no.
I told them to use the millions of books that have no copyright instead. Offered to help pick them and to help train the model a different way. They only wanted distillation, which tells you a lot about the mindset there.
I've worked deep in this field and distillation is real. I wasn't convinced at one point. What I saw changed my mind completely.
I'm the biggest supporter of open source. I'm for releasing weights and for the freedom to research and build, because humanity only grows when knowledge gets shared. But let's be logical.
Nobody will convince me that labs shipping a model every month or less, each one a big leap, now can't ship a better one after three months.
Kimi K3.1 Pro isn't a big leap over Kimi K3 and it's been about 100 days.
DeepSeek still can't put out a respectable Pro model.
Zai used to release their strongest model in under two months. It's been three with nothing.
All I hear about Qwen 4 Max is that it's a letdown.
Kimi K3.1 Pro and DeepSeek Flash both show traces of Astra distillation. The leak showed Moonshot used it, and so did DeepSeek.
If this isn't the effect of Anthropic blocking distillation then what is it?
Chinese labs need to get serious about using the talented researchers they have and give their models an identity. Right now their models at their best are a cheaper alternative. I want them out of that box. I want to see what makes them different.
Anthropic has crossed lines too, no argument there. They destroyed millions of books, human knowledge that was in people's hands, and kept it for themselves. I'll never forgive them for that.
But Chinese labs rely on distillation more than they rely on better data.
I didn't work with them. Transparency and honesty matter to me, like you've known since I started here.
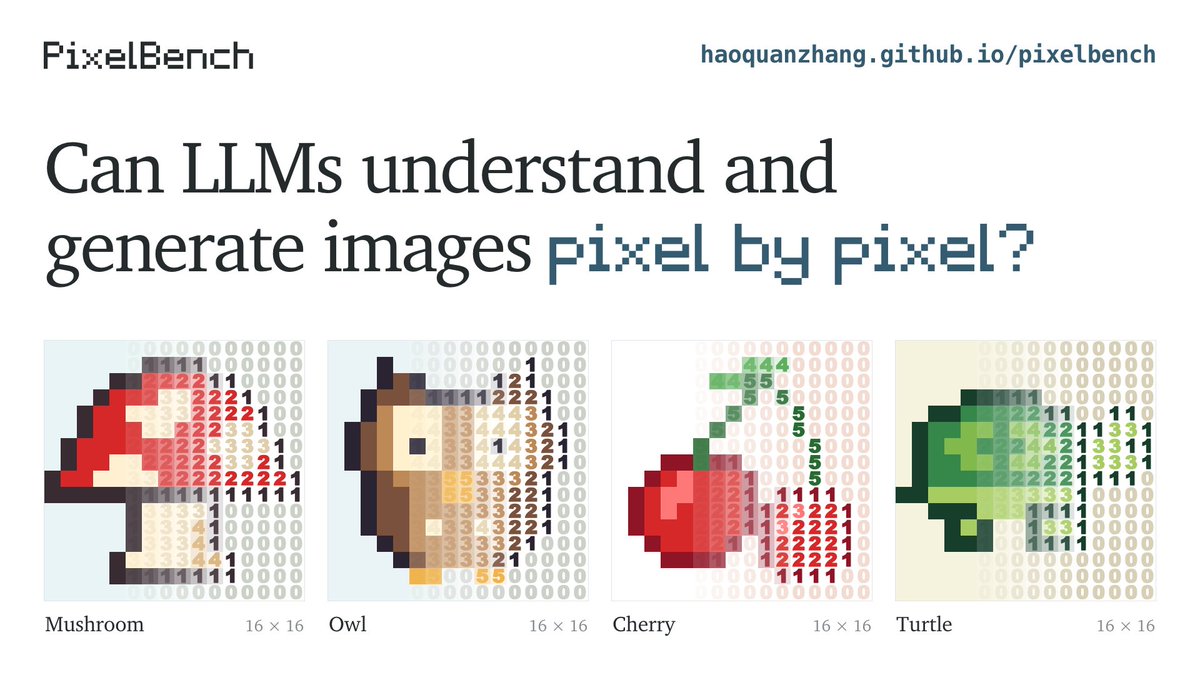
Quite interesting project done by Haoquan @Haoquan03. Raw pixel generation could be a useful proxy to assess LLM’s long-context reasoning capability, as generating a long sequence of pixels requires LLMs to be semantically and positionally aware of what they have already generated.
More broadly, this is also related to a series of work from SphereLab: SGP-Bench (https://t.co/jwWHRu9sc9) and SGP-Gen (https://t.co/GIqIqOvJQG). PixelBench and these projects are all generating a textual format of visual content, except that pixels can be visualized without any external renderers. Like SVG codes, pixels are a natural verifiable format for images. This can be a useful source of data for improving LLMs.
The era of evaluating multimodal models with QA is over.
Use pixels instead. (0/7)
QA only tests high-level text reasoning. SVG and CAD rely on symbolic shapes rendered by external engines. Neither tells us if a model can directly control or read raw pixels.
We introduce PixelBench: a direct text-to-pixel probe where LLMs and VLMs generate and understand images pixel by pixel.
(1/9)Suppose you're training an LLM on web data with limited math data. Should you place all your math data at the end of training, or mix it with web data earlier? The answer flips with the learning rate (LR) schedule!
At fixed compute and mid-training (MT) token budgets, earlier mixing gives lower MT loss when LR decays throughout training. With constant LR, placeing all MT data for the end works better.
We then vary when LR decay begins. The best tested strategy: keep LR high after MT data enters, then decay near the end.
See our new paper: "Data Schedules and Learning Rate Schedules Should Be Designed Together" !
@DanielLenton1 We haven’t tried the conv variant on 1B model. Based on our previous experiments, it should achieve similar gains. We will have a try soon. :)
🚀 Very excited to introduce TTR-Compressor -- A test-time regression framework for sequence compression! I particularly like this work for its fundamentally different perspective on sequence compression.
Unlike popular pooling and projection, TTR-Compressor formulates sequence compression as a test-time regression problem. Instead of directly aggregating tokens, we fit regression keys derived from the input tokens to learnable targets, using the fitted coefficients as the compressed representation.
This leads to a bi-level optimization with an exact closed-form solution to the inner test-time regression. The closed-form solution captures second-order inter-token correlations, allowing TTR-Compressor to reduce redundancy and better preserve distinctive information, going beyond conventional first-order aggregation in pooling and projection.
Strong gains in two applications:
✨ Block-wise sparse attention: +12.24% in RULER retrieval accuracy over attention-based compression.
✨ Visual token merging: Comparable multimodal performance with 55.6% fewer visual tokens than standard MLP merging.
🤔 Takeaway: Sequence compression can be viewed as input-adaptive regression rather than static aggregation. This provides new insights to building more efficient language and multimodal models.
📄 Paper: https://t.co/rX4J205ZCZ
🌐 Project: https://t.co/fbZSKK6ecv
💻 Code: https://t.co/KuHP1G3ifD
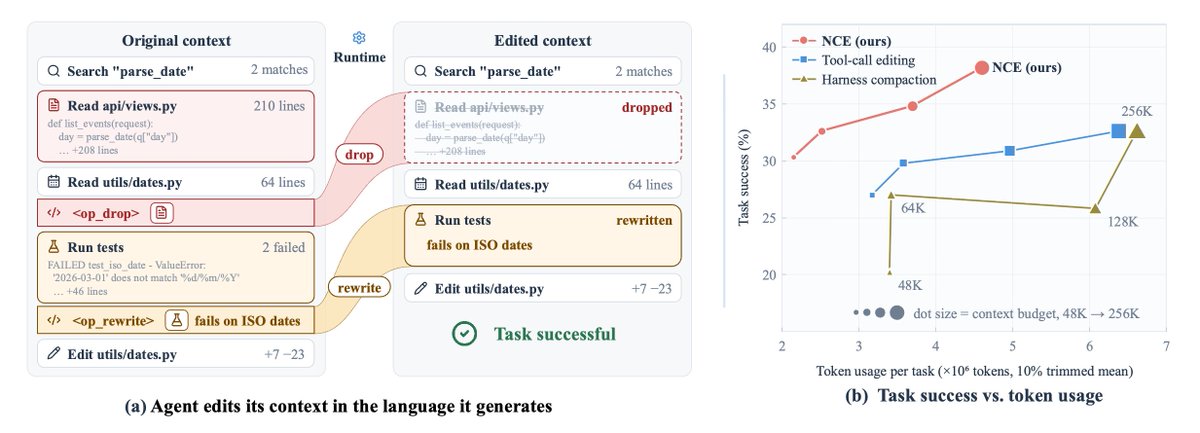
Can LLMs manage their own context natively without any external harness? We are teaching LLMs the ability of Native Context Editing. Our method achieves considerable performance gain on popular long-horizon agentic benchmarks (Terminal-Bench, SWE-bench) while reducing token usage significantly.
🤔 This can be viewed as a form of verbalized context management, which leverages LLMs' inherent capabilities to optimize context. Our prior work, Verbalized Machine Learning (https://t.co/qPXUhjpBAG), similarly explores context optimization to enhance downstream task performance.
Project: https://t.co/5OnN9mxWhQ
Paper: https://t.co/x7K2f7XPIu
Code: https://t.co/rPdaaNZcll