Ox Alpha (stealth model) is free for the next week
- 1M Context
- Multi-modal
- Zero Data Retention
Generous rate limits, near unlimited usage
We have capacity for 100T tokens per day, lets see what you can do
Scores for Qwen3.8-27B!
• MILU: 58.22%
• IndicParam: 36.06%
• Strict IndicIFEval: 54.65%
• Equal-task mean: 49.64%
The gap is especially visible for Tamil, Telugu, Gujarati, and Kannada.
very strong general purpose reasoning/coding model, but a clear Indic language capability gap.
This is crazy!!
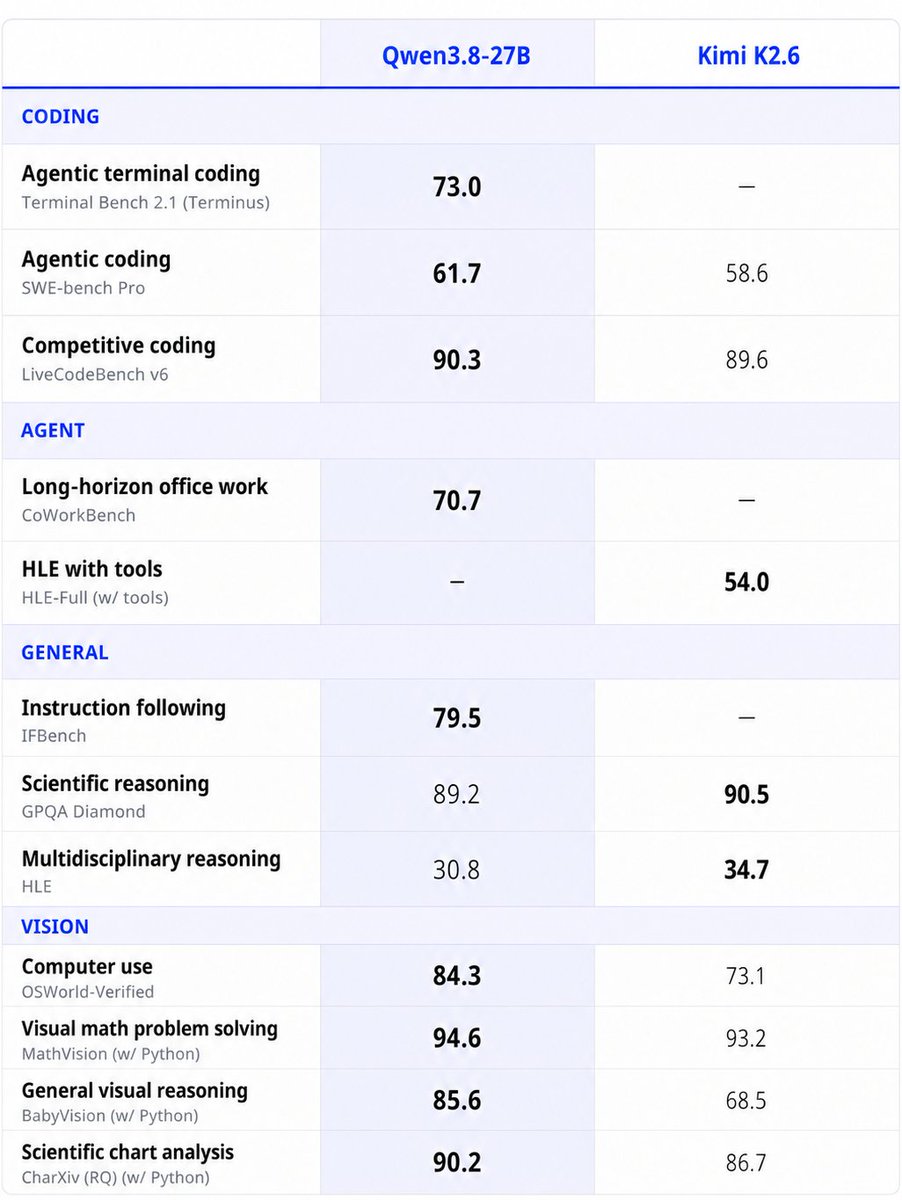
Qwen 3.8 27B is better than Kimi K2.6, a 1-trillion parameter Mixture-of-Experts (MoE) model from 4 months ago across various benchmarks.
*Introducing gemma-4-31b-indic-rys*: a 61-layer Gemma 4 model for Indic language tasks.
@SarvamAI probably releases new SOTA on Indic Benchamrks at Sarvam Epoch (AI Conference) in few hours, until then this is best option on Indic in <100B size.
*Introducing gemma-4-31b-indic-rys*: a 61-layer Gemma 4 model for Indic language tasks.
@SarvamAI probably releases new SOTA on Indic Benchamrks at Sarvam Epoch (AI Conference) in few hours, until then this is best option on Indic in <100B size.
https://t.co/cSfvP5Krtx
This is not a standard 60-layer Gemma checkpoint. The model has 61 decoder layers and a gated repeated block, so use the custom Transformers implementation or the supported vLLM runtime included with the release.
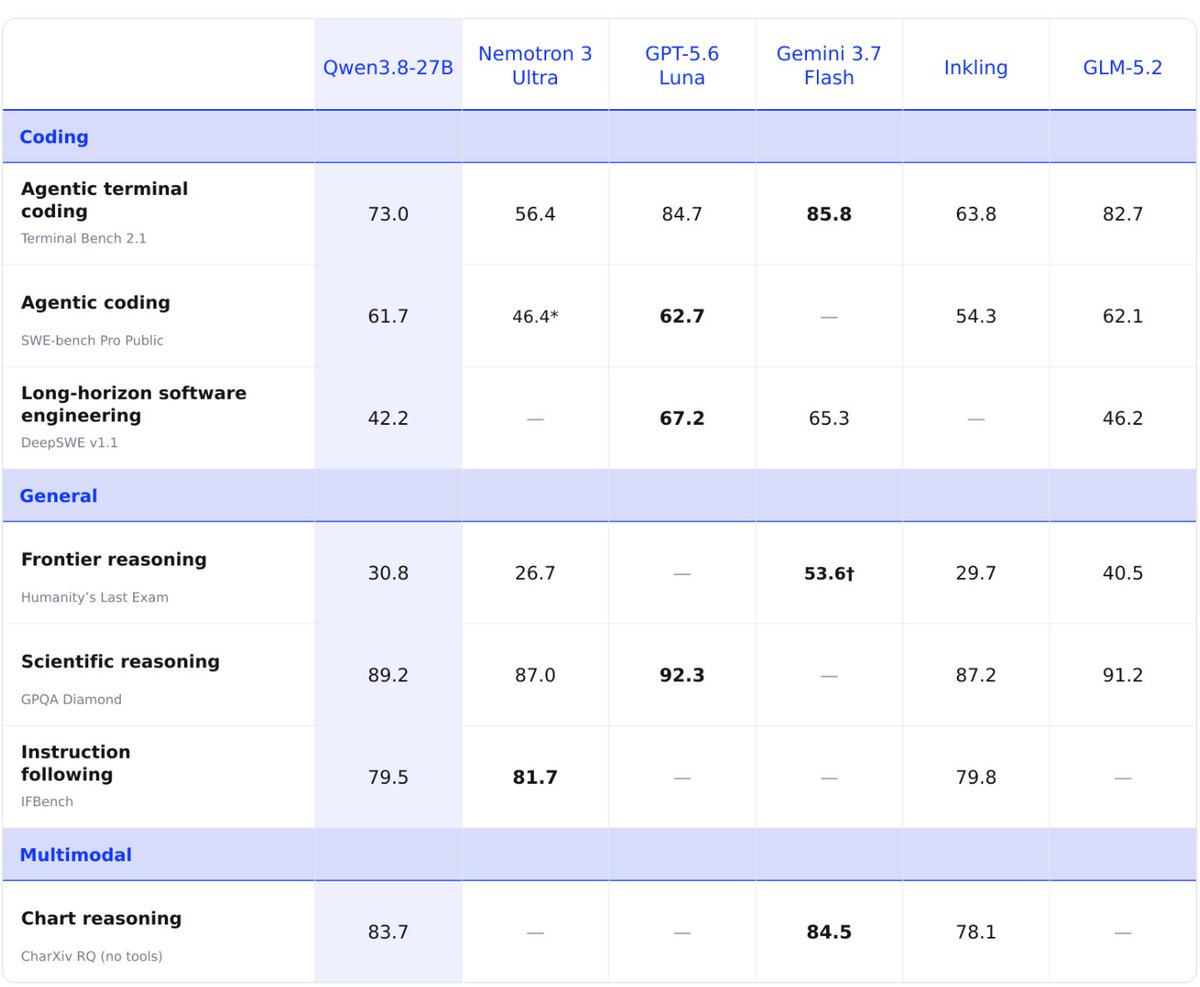
Inkling is the strongest model among the seven shown.
Nemotron’s within-family gap is substantial.
Kimi K2.6 reaches 69.3% on strict IFEval—but MCQ answer validity hurts
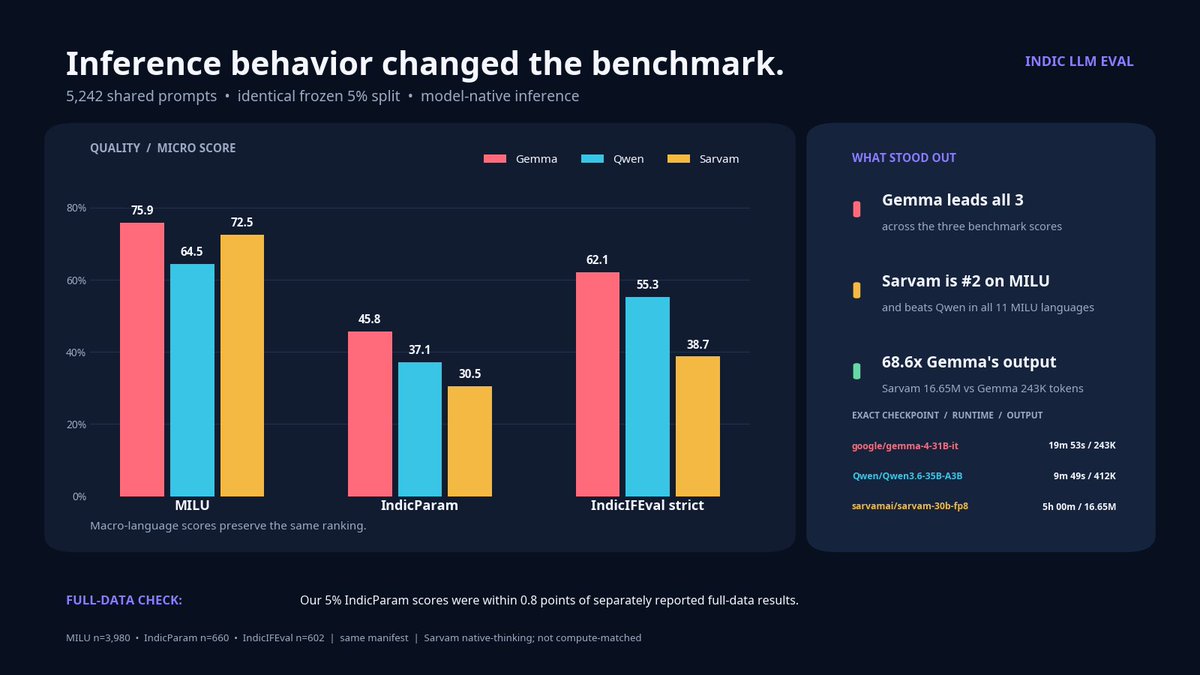
The most important result from this LLM evaluation was not the leaderboard. It was a **68.6× output-token gap** on the exact same 5,242-prompt Indic evaluation.
Inference behavior changed the benchmark.
#IndicAI#LLMEvaluation#OpenSourceAI#AIResearch#MultilingualAI
The scores are useful—but they are not an apples-to-apples architecture or efficiency comparison. Sarvam used FP8 with native thinking; Gemma and Qwen used BF16 with direct answers. This is a comparison of the models in the deployment modes we could run reliably on one 96GB GPU.