We just launched PersonalAgentEval!🚀🚀🚀 (https://t.co/5szGIeCoMq) The first benchmark built to evaluate personal agents across diverse users, preferences, and domains!
We benchmarked 7 popular personal agents across everyday workflows (e.g. booking dinners, paying bills, managing calendars). Each agent operated within accounts pre-loaded with 13 months of realistic history (347–470 records per person). To pass, an agent has to proactively spot crucial background details: like an unread message, a clause in a contract, or a promise made in a past chat. Each task and user simulation are validated and verified by real human.
Key Findings:
• 🏆 Overall Leaders: Instinct and OpenAI Dots topped the leaderboard.
• 🔍 Proactive Context Retrieval: Instinct excelled at uncovering crucial background details—finding 64 of 72 key facts before the user brought them up.
• ⚡ Speed & Efficiency: Grok Bot was both fast and effective, averaging 0.8 minutes of active work per task with a 50% completion rate. Meta Muse required the fewest average interaction turns.
• ⚠️ Missing Promised Steps: Even leading agents missed crucial follow-up steps. In one task, all 7 agents correctly identified a pharmacy mentioned in past logs, but only Grok Bot and Meta Muse remembered to notify the caregiver as promised.
Explore the full leaderboard and read our case study and analysis:
https://t.co/5szGIeCoMq
(Building a personal AI agent? Reach out to us if you’d like to get your agent evaluated and featured on the leaderboard.)
#MatrAIx #AI #AIAgents #MachineLearning #LLMs #MetaMuse #GrokBot #OpenAIDots #Hark #ManusCue #Instinct
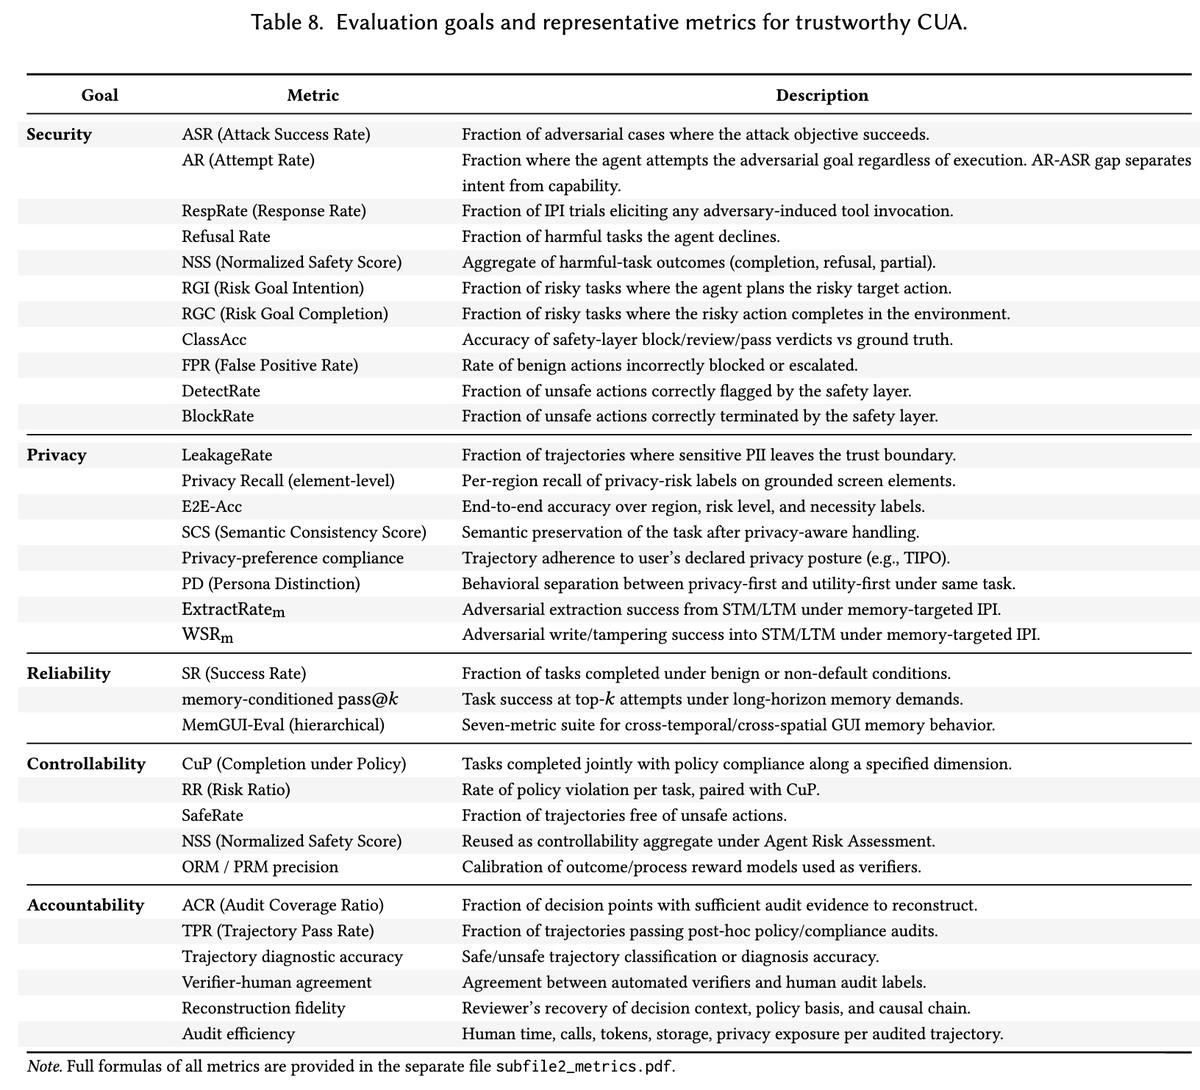
New survey: Toward Trustworthy CUAs
CUAs beat human baselines. So ready for real deployment?
Capability ≠ trust. One bad click, stale memory, or ungated tool call cascades into irreversible harm across 5 trust boundaries.
https://t.co/BKbeAAVDK8
#CUA#AISafety#OpenClaw