Your pipeline says SUCCESS.
Your data says otherwise.
"It ran" and "it worked" aren't the same in AWS — most teams only learn the difference when a customer complains.
A short thread on the gap 🧵👇
#DataEngineering#AWS#DevOps#DataPipelines
You can have zero bad data and still get paged at 2 am.
Most AWS pipelines fail silently, not loudly.
A short thread on where visibility breaks down 🧵👇
#DataEngineering#AWS#DevOps#DataPipelines
Pipelines break because of bad orchestration, not bad data:
🔵API rate limits
🔵EMR memory spikes
🔵Non-idempotent reruns
Fix: Decouple extraction from transformation via S3 staging + retries with backoff.
What's your biggest data headache? 👇
#DataEngineering#AWS#DevOps
Bad data isn't the only pipeline risk. Runaway EMR costs are too.
Glue orchestrates. S3 stores. EMR crunches — without breaking the bank:
🔹 S3 Lifecycle rules
🔹 EMR Transient clusters
🔹 SNS alerts on fail
Step Functions, Glue, or MWAA for this? 👇
#AWS#DataPipelines#DevOps
Fail small" isn't just for deploys.
Data pipelines share CI/CD's risks:
❌ Schema drift
❌ Silent failures
❌ Idle EC2/EMR costs
DevOps cuts data corruption ~80%.
Catch bad data before your warehouse does? 👇
#DataEngineering#DevOps#AWS
Even if resilience checks pass, never shift 100% traffic at once.
Canary 5% ➔ watch error rate/latency ➔ auto-promote or rollback.
Failed 5% = barely noticed. Failed 100% = 2 AM incident.
Fail small. What % do you canary?
#DevOps#AWS#CICD#IaC
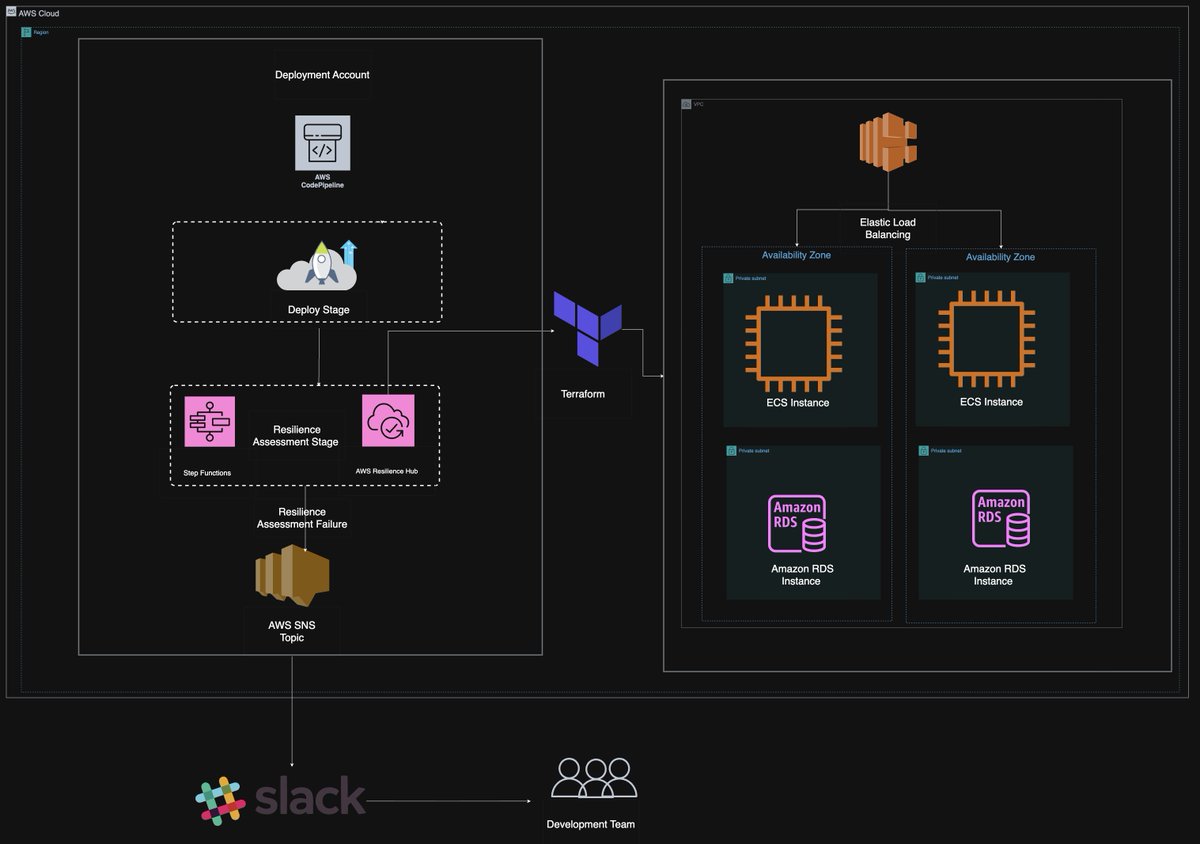
Same logic applies further down: after deployment, an automated resilience check (Step Functions + Resilience Hub) runs before shifting prod traffic. If it fails, SNS alerts the team on Slack in seconds. Fail fast at every stage—not just at build. 🚀
#DevOps#AWS#IaC#CICD
Most pipelines run 40 min before failing.
Flip the order:
• Lint + unit tests first (30s)
• Integration tests after
You catch 80% of failures in <2 min.
What's your avg build time? 👇
#DevOps#CICD#AWS
Your pipeline didn't fail from bad luck.
Same usual suspects every time:
• Flaky APIs
• Rate limits
• Expired tokens
Fix: isolate calls with retries & backoff. Zero code touched.
What's yours been? 👇
#DevOps#CICD#AWS
Nobody talks about pipelines until something breaks.
And when it breaks, it's always at the worst possible time.
Next posts: how to fix that.
No jargon. No fluff. 👇
#DevOps#CICD#Pipeline#AWS
That's the full ECS stack. 🛌
5 configs. Zero 3 AM incidents.
If your team is still babysitting servers, let's fix that.
DM me "ECS" and I'll review your stack. 📩
#AWS#ECS#CloudOps#DevOps#FinOps
Fix it with 3 numbers:
📈 Scale out: CPU > 70% → add tasks
📉 Scale in: CPU < 30% → remove tasks
⏱ Cooldown: 60s
Set it once. Save every month.
#AWS#ECS#Fargate#DevOps#FinOps
You fixed the network. 🔒
You secured the traffic. 🛡️
You locked down the secrets. 🔑
You fixed the health checks.
Now, stop paying for idle containers.
Auto Scaling: the last piece of a production-ready ECS stack.
Config #5 👇
#AWS#ECS#Fargate#DevOps#CloudOps
Most teams set a fixed number of tasks and call it a day. But running 2 tasks 24/7 means paying for capacity you don't use. Fargate charges per second. Every idle second is real money out of your pocket.
#AWS#ECS#Fargate#DevOps#FinOps
Fargate doesn't lie to you.
Your health check does.
Fix the logic → fix the uptime. One broken endpoint is enough to silently kill your service while your team sleeps.
Save this thread. You’ll need it at 3 AM.
#AWS#ECS#Fargate#DevOps#CloudComputing
Most teams use GET / as their health check.
Big mistake.
Your app can be broken and still return a 200 from /.
Fargate sees a 200 → thinks it's healthy → never restarts.
Meanwhile, your users get errors. Silently.
✅ Use /health. Always.
#AWS#ECS#Fargate#DevOps
Your ECS container is restarting every 30 seconds at
3 AM🔴
Nobody is paging you.
Fargate is just quietly restarting it over and over.
The culprit 99% of the time? A bad health check.
Thread 🧵👇
#AWS#ECS#DevOps#CloudSecurity#Cloud
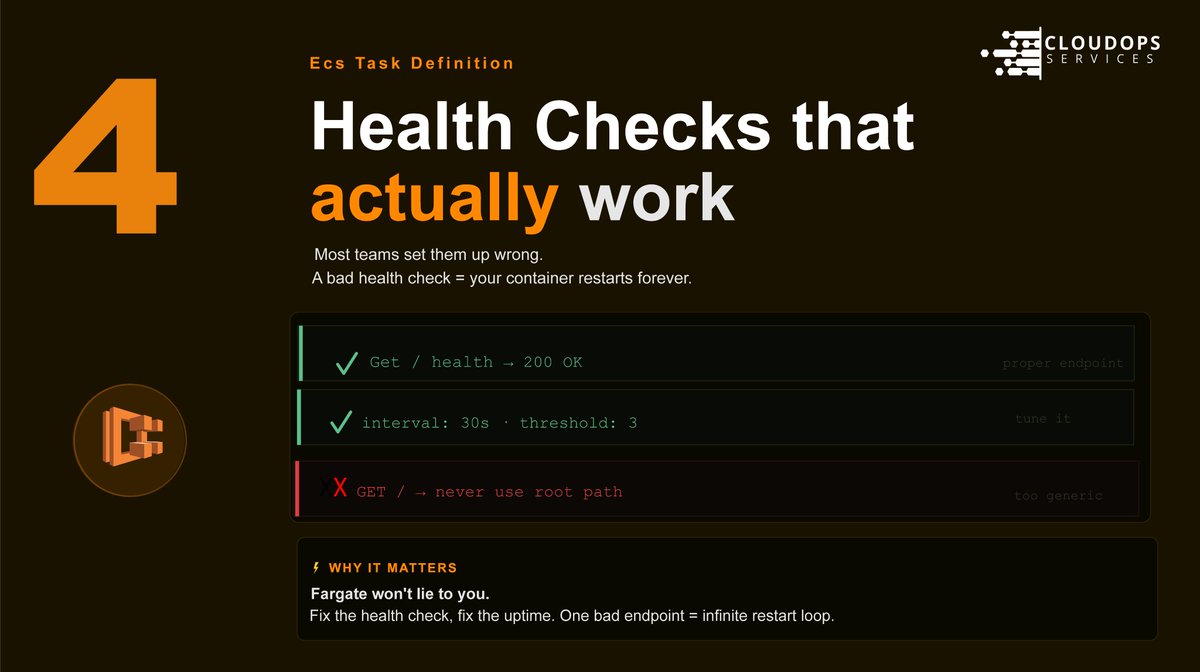
ECS containers restarting at 3 AM? 🔴 99% of the time, it’s a bad Health Check. Don’t sweat it!
✅ GET /health → 200 OK ✅ Interval: 30s | Threshold: 3 ❌ NEVER use a heavy GET /
Fargate won't lie to you. Fix the check, get some sleep. ☁️
#AWS#ECS#DevOps
Your container is running. But ECS has no idea if it's actually working.
No health check = broken tasks receiving live traffic. Tomorrow I'll show you how to fix it in 5 lines. 👀
#AWS#ECS#CloudSecurity#DevOps#CyberSecurity
Most teams don't realize their DB passwords are exposed — until it's too late.
AWS Secrets Manager injects secrets at runtime. No hardcoding. No exposure. No risk. We help teams fix this.
DM us today.
Config #3 👆
#AWS#ECS#CloudSecurity#DevOps