You can run fully Uncensored DeepSeek-V4.1-Flash-1017.
- Refusal behavior removed
at the Proper weight-level abliteration no system prompt hacks or template trick, no LoRA, no SFT.
- 763B FP8, native vision, video it Multimodal
- 1M context
- tool calling, reasoning tiers still intact.
- https://t.co/zHNemkaBc5
@Wbackdown Yes, it holds past 200k all the way to the full 262k.
With MTP: ~79 t/s at 131k → ~31 t/s at 262k.
Without MTP the drop is steeper (~9.5 t/s at max).
Streaming keeps it from OOMing past ~65k, but bandwidth + attention cost still show up at the extreme end.
Full 262,144-token context on a 16GB RX 9070 XT — Qwen 27B IQ4_XS hits 80+ t/s decode with adaptive KV streaming ported to ROCm. Trimming non-ASCII vocabulary frees VRAM, and the streaming avoids OOM past 65k tokens. Practical local inference breakthrough.
TensorFold just turned 2x DGX Spark into a DeepSeek V4.1 Flash inferno. 57 tok/s text, 92 tok/s code — 2.1-2.3x faster than vLLM on the same hardware. Cold prefill at 2,000+ tok/s, 1M context needle found. Open source inferencing just hit a new ceiling.
Jumping from 32GB to 64GB DDR5 lets Qwen3.8-Flash-Next run UD-IQ4_XS on a single 4090. 40GiB experts in RAM, zero disk reads. Strata 0.1.45, 262K context, 87-98 t/s decode. That's the difference a RAM upgrade makes.
Replace Claude Code's lossy compaction with a Jev decision log so long agent sessions never repeat tool calls after context overflow.
1. Install fast-jev-compaction as a Claude Code plugin → every tool call and result is captured as a Jev decision → continuous session memory.
2. Start a fresh session → point it at your project or game → use universal-modder skills and the fal MCP to recon files and assets.
3. When context fills, trigger compaction → the plugin restores exact prior decisions instead of a summary → no re-scans or duplicate edits.
4. Keep the Jev log as a reusable build history → replay verified steps in future sessions → speed up iterative modding or refactors.
Save this workflow for your next build.
Five breakout AI repos climbing the charts this week and the specific bottlenecks each one unblocks:
1. anthropics/claude-code
→ Official CLI adding a retry watchdog that stops unattended runs at distant usage-limit resets instead of hanging, plus OpenTelemetry tracing for observability
2. tamaratran/fast-jev-compaction
→ ~254 stars/day TypeScript plugin that swaps Claude Code's compaction summary for Jev scoring, cutting context bloat by evaluating every tool call in one fast request
3. rehan-remade/universal-modder
→ ~471 stars/day Python toolkit pointing Claude Code at any PC game for recon, reverse engineering, and asset generation via fal MCP
4. All-Hands-AI/OpenHands
→ v1.27.0 ships OpenCode and Pi as built-in ACP agents with full e2e verification on DeepSeek, replacing managed agent platforms
5. browser-use/jev-ultrafast
→ ~756 stars/day Python web agent claiming fastest and cheapest browser automation, an alternative to hosted scraping services
Bookmark this stack for your next build.
The quieter DeepSeek launch this weekend might matter more than the model.
Alongside V4.1-Flash-1017, DeepSeek opened its Search and Fetch APIs to everyone. They run on the company's own search engine, which DeepSeek says already serves hundreds of millions of requests a day, and each endpoint costs $0.75 per 1,000 calls.
The detail worth noticing: if you use the DeepSeek API inside DeepSeek Harness, Claude Code or Codex, the search and fetch calls those tools make are free for now. Billing starts on October 31 at 16:00 UTC.
Web search is usually the add-on agents rent from someone else. A model lab bundling its own search at this price is a direct shot at that market, and it leaves about two weeks to test it for free.
Qwen-Audio-Jev drops the autoregressive overhead for audio decision tasks. A dedicated Jev head directly outputs probability distributions for selection, judgment, and scoring. Three primitives: CHOICE, NOUL, SCORE.
inclusionAI just dropped Ming-Image-0.1-Design-Layer — a model that decomposes flat design images into separate RGBA layers. Feed it an image plus a layer plan, and it outputs the requested number of layers at 1024px. MIT licensed, 106 likes already.
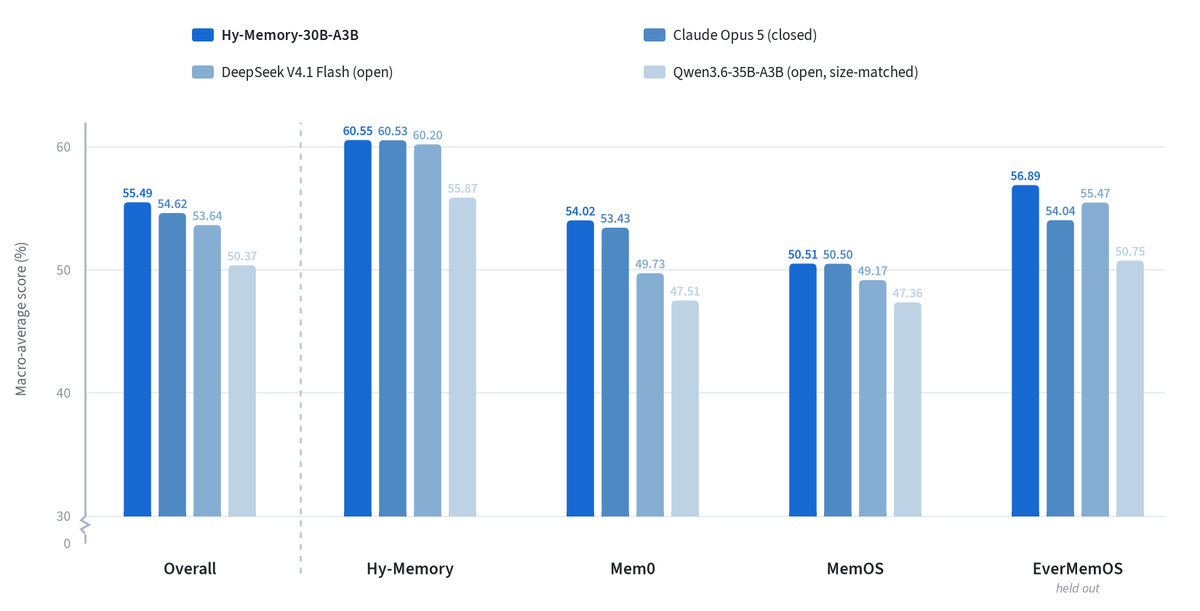
Tencent just dropped Hy-Memory-30B-A3B — a tiny 3B active model that WRITES persistent memory. Trained with On-Policy Distillation then RL, it replaces general LLMs inside Mem0 and MemOS. Memory agents just got their own specialist.
BlenderWorld just landed from QwenLM — a new repo for blending synthetic worlds. Only 116 stars, but this is how you train agents that actually generalize.
PR #1225 for ds4 just added DeepSeek V4.1 Flash 1017 support. 40% of routed expert tensors changed, 30% in engrams, 50% in vision tower. Architecture identical — slots into existing kernels. No regressions. Quantized files load without changes.
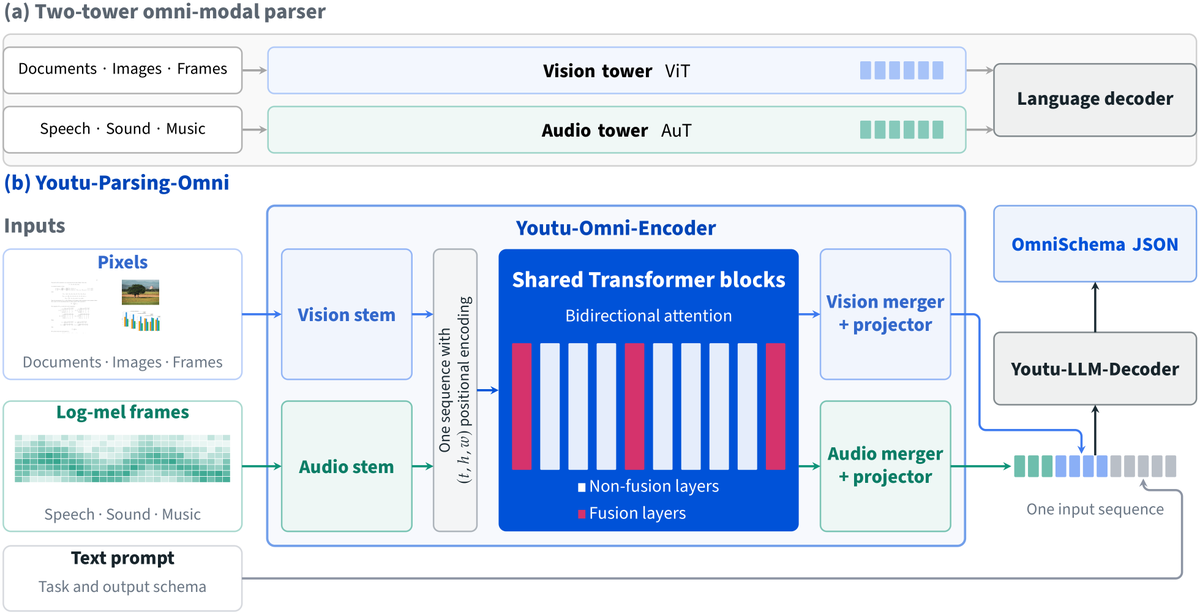
Tencent just dropped Youtu-Parsing-Omni — a compact 5B model that parses documents, images, charts, audio, and video into a single structured JSON. One model, all formats. The universal parser is here.