I have to say that I've become quite good at cooking spaghetti all'assassina (a typical dish from Bari). I now divide my time between optimizing Colibri and cooking, and I really enjoy it.
P.S. A new release is coming!👀👀👀
@justvugg Colibri just hit 50k stars on GitHub! 🍾
I think there are many more milestones to come, so stay tuned!!
Huge thanks to @JustVugg for his tireless work on the project.
colibrì just hit 50,000 stars on GitHub
I started this to run immense models on tiny hardware. I never expected 50,000 of you to show up.
Every star, issue, PR and bug report got us here. So the bird made you a little video.
Thank you!
https://t.co/qs7jTvVk7H
When I created Colibrì, I did so with a clear vision: every computer,even one without a GPU,should be able to access local AI.
The project grows every single day, thanks to a community that supports and it daily.
Thanks everyone!
https://t.co/qs7jTvVk7H
Which hardware would you like us to focus on next for Colibrì?
NVIDIA DGX Spark or Apple Silicon Macs?
We’d like to launch a fundraiser on buymecoffee to buy one of these machines for development, testing and optimization. Your feedback will help us choose!
Many of those recent reimplementions and rewrites were done in Rust. However, to understand the implicit tradeoffs of this choice, an ablation study should be performed to see if/how faster and better the agent would do the same using the C language.
If you like my work on Colibri and want to support the project, buy me a coffee! Your support helps me keep optimizing the engine and dedicating more time to development.
https://t.co/8sF61Q9Wzx
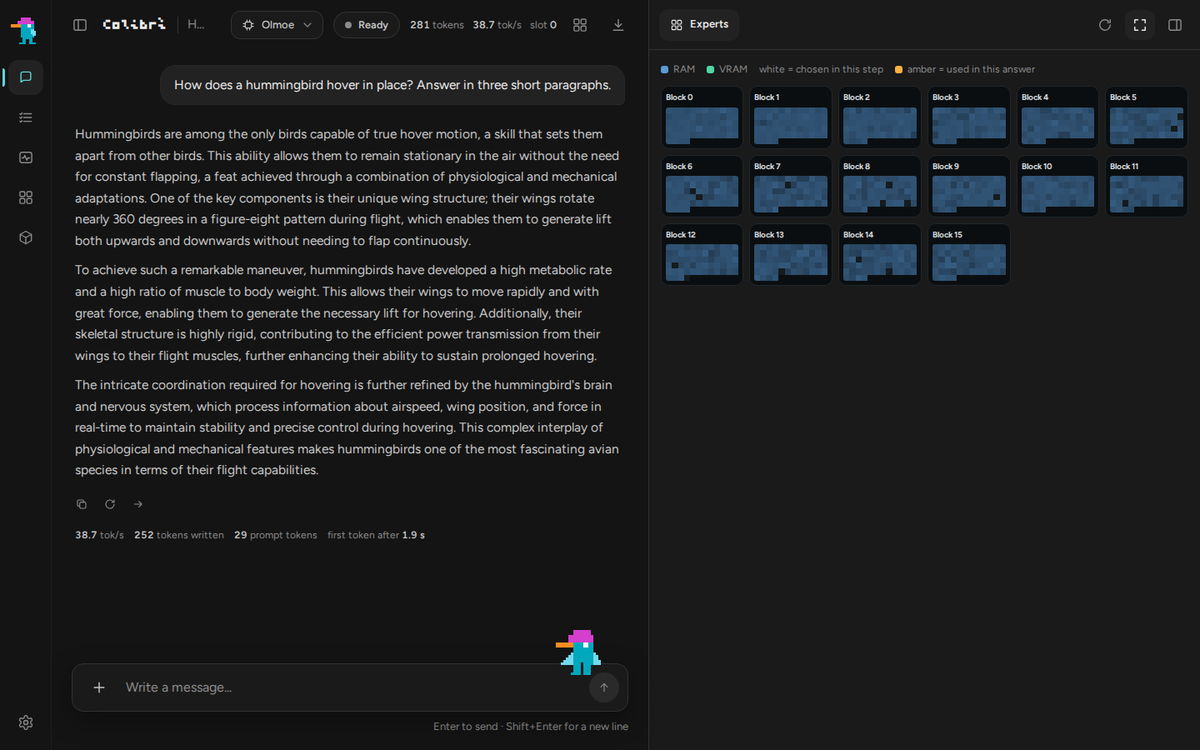
A new chat UI: coli ui
Reasoning in its own block, pictures, web search, a live map of the experts as they fire, a monitor, your models, and coding agents already pointed at colibri. Seven languages.
Long contexts: Qwen3.8-Flash-Next at 256k tokens runs at the speed of 64k. Decode 9.6 -> 45.7 tok/s, prompt 15.6 -> 149.
Agents: a short request between two turns no longer makes the model read the whole conversation. A @NousResearch Hermes turn: 86 s -> 4.9 s. On every engine.
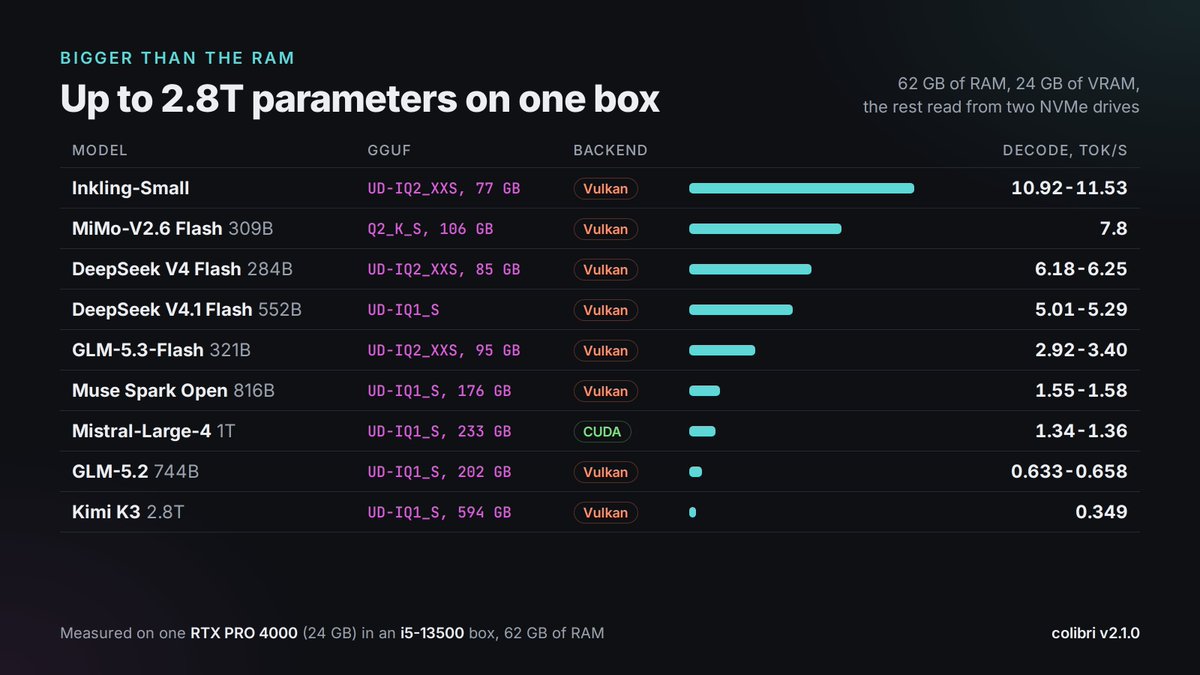
Bigger than the RAM, on that same box (62 GB of RAM, experts read from two NVMe drives):
Mistral-Large-4 1T: 1.34-1.36 tok/s
Muse Spark Open 816B: 1.55-1.58
GLM-5.2 744B: 0.63-0.66
Kimi K3 2.8T: 0.35
DeepSeek V4.1 Flash: 5.0-5.3
MiMo-V2.6 Flash: 7.8
One RTX PRO 4000 (24 GB) in an i5-13500 box, decode:
Qwen3.6-35B-A3B: 104.8 tok/s on CUDA, 92.9 on Vulkan
LFM3-VL-2B: 235 tok/s on CUDA
OLMoE: 354 tok/s on CUDA
Qwen3.8-Flash-Next (125B, a 68 GB file on a 24 GB card): 51.4 tok/s
Prompts up to 12,317 tok/s.
New models:
- Mistral-Large-4 (1T): text, pictures, reasoning, tools
- Muse Spark Open (816B)
- Flint (40B, 2.5B active)
- LFM3-VL-2B, with pictures
- the published DeepSeek V4.1 Flash and Kimi K3 GGUFs