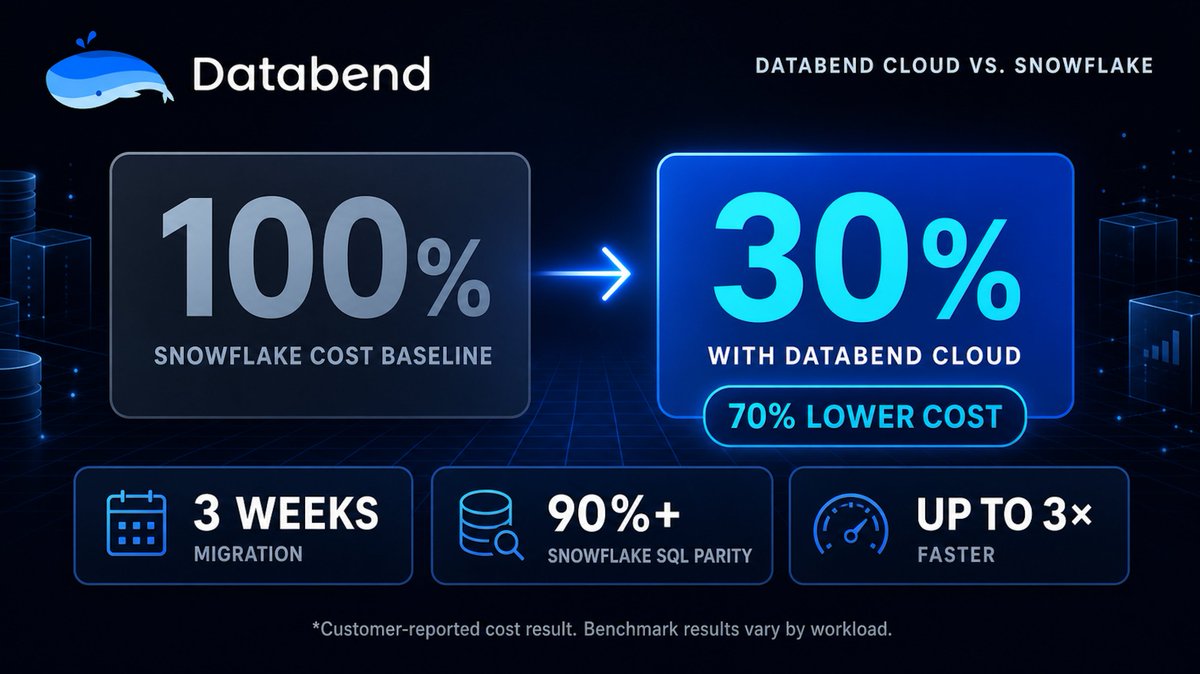
Millions of context tokens. Thousands of tool calls. TB-scale Trace writes per hour.
See how a leading foundation model company built an end-to-end Agent Trace pipeline on Databend Cloud—turning raw execution data into eval-ready datasets.
Read the customer story 👇
https://t.co/KvvNXiXGx4
New in Databend Cloud Fundamentals: Episode 04. 🎉
Learn how User, Internal, and External Stages work—then create, query, and manage Stages, Databases, and Tables with SQL.
Watch 👉 https://t.co/tCuTNreDkC
#Lakehouse#DataEngineering
New in Databend Cloud Fundamentals: Episodes 02 & 03.
Set up Databend Cloud, then build an automated incremental JSON pipeline with Stages, Streams, Tasks, and Task Flows.
Watch the two-part Getting Started lesson:
02: https://t.co/irTrJG9wkO
03: https://t.co/z4GWzkUsxT
Agent traces keep changing. Your queries still need to find the slowest calls.
Databend's September nightlies add TopN pruning for typed virtual columns and reduce object-storage requests for inverted indexes.
See the GitHub updates 👉 https://t.co/4u8C2S7zGJ
New to Databend Cloud 🤔 ?
Databend Cloud Fundamentals is now on YouTube, with short lessons on data ingestion, SQL, and lakehouse operations.
Start with Episode 1: A Lakehouse for Modern Apps & AI Watch and subscribe: https://t.co/QkvN7nF3lK
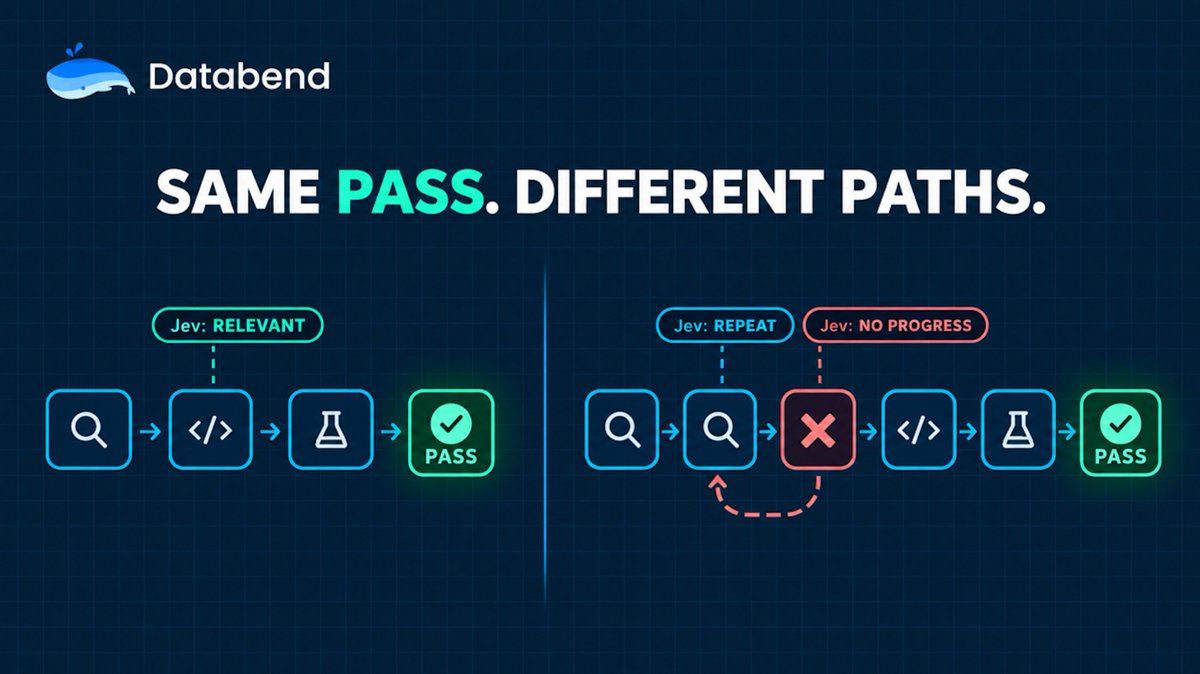
Same PASS. Very different execution paths.
Jev evaluates each span for relevance and progress, then writes the results to Databend Cloud for SQL analysis. In our runs, evaluating 1M spans would cost about $80.
Read the engineering breakdown: https://t.co/w3XJUmDo3Y
Keyword rules miss the meaning in customer feedback 🔍.
We connected Jev to Databend's Python UDF server so SQL can filter, classify, and rank records using model probabilities 📊.
Databend runs the query; Jev makes the bounded decision ✅.
Explore: https://t.co/sZ7R35pLLM
Cloud Agent is in Preview 🚀 — your AI assistant for Databend Cloud.
Ask in natural language 💬.
Analyze data and workloads 📊.
Take action with your approval ✅.
One example: “Where can I reduce warehouse costs?”
https://t.co/DE5EGEP7Hz
🔥We’re launching the Agent Trace Solution.
Capture complete agent runs, preserve evolving JSON, and turn new spans into query-ready and eval-ready data—on one S3-backed lakehouse.
Built for production scale 🔍 https://t.co/nZKv2VVOvQ
Async refresh shouldn’t mean stale answers.
Databend materialized views use Change Tracking + checkpoints, then choose Fresh, Hybrid read fix, or Live Fallback at query time.
Refresh lag changes query cost—not correctness.
Deep dive 👉 https://t.co/K4cP6Vpxkr
One lakehouse. Five production scenarios.
Agent traces, AI apps, industrial telemetry, public-sector data, and financial archives—built on Databend Cloud with the same pattern: preserve raw data, process changes incrementally, isolate compute.
Read 👉 https://t.co/b0Dzj6dD66
On a controlled 100M-row test:
62.9% → 13.6% of blocks scanned.
63.5M → 13.6M rows read.
The difference: a workload-driven Databend Cluster Key.
Learn how to choose columns, key order & granularity—and verify the result 👉 https://t.co/pH2QqVrb4x
Recent Snowflake threads repeat the warning: clustering helps pruning, but can burn credits when keys miss the workload.
Cluster keys aren’t indexes. Databend pairs automatic clustering with block metrics + SQL RECLUSTER controls.
Deep dive → https://t.co/2MMFXtdse7
DeepSeek Harness puts Agent Trace in focus: long contexts, tool calls, and retries create a data problem.
Production proof: a leading AI company uses Databend Cloud for TB-scale ingestion, turning spans into eval-ready data—with less OSS overhead.
Reed 👉 https://t.co/KvvNXiXGx4
Modern apps & AI workloads need more than fast SQL.
Databend Cloud brings together:
→ Cloud-native lakehouse
→ Real-time ELT
→ Multimodal analytics in one SQL engine
→ Governance, isolation & cost control
Start with free credits 👇
https://t.co/VeYWIiVvZM
Agent Trace pipelines fail at the boundaries: schema drift, small writes, and early offset commits.
bend-ingest-kafka batches events, commits after COPY succeeds, then Databend Stream + MERGE processes new data incrementally.
Engineering deep dive 👉 https://t.co/sAuUFKRICX
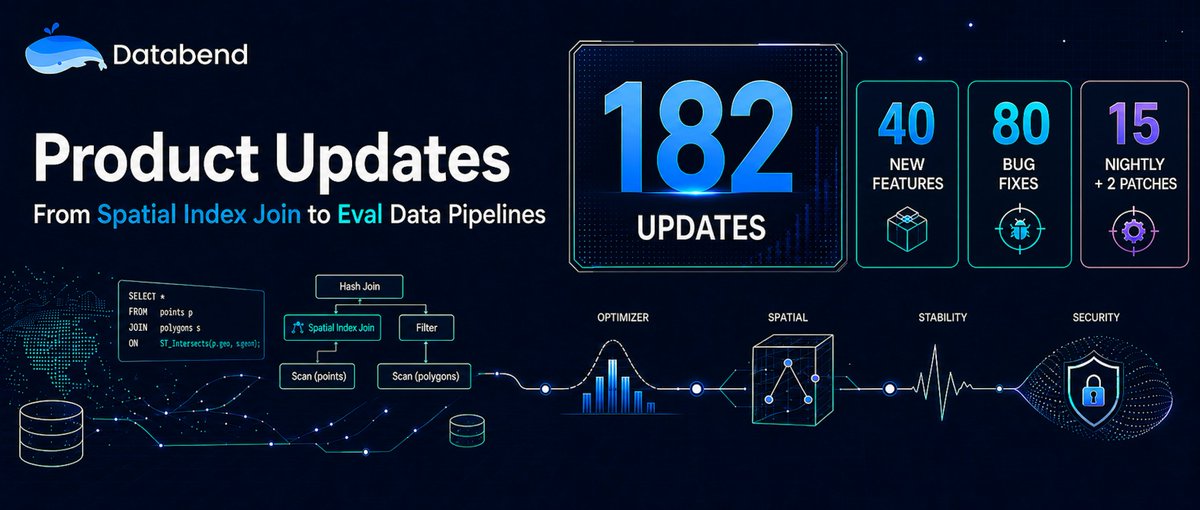
June���July at Databend: 182 updates across 15 nightlies + 2 patches.
Smarter optimizer stats. R-Tree Spatial Index Join. Paimon Catalog. More reliable Stream + Task pipelines for model Eval and Agent Trace workloads.
Read the engineering update 👉 https://t.co/CKHOWPsybq
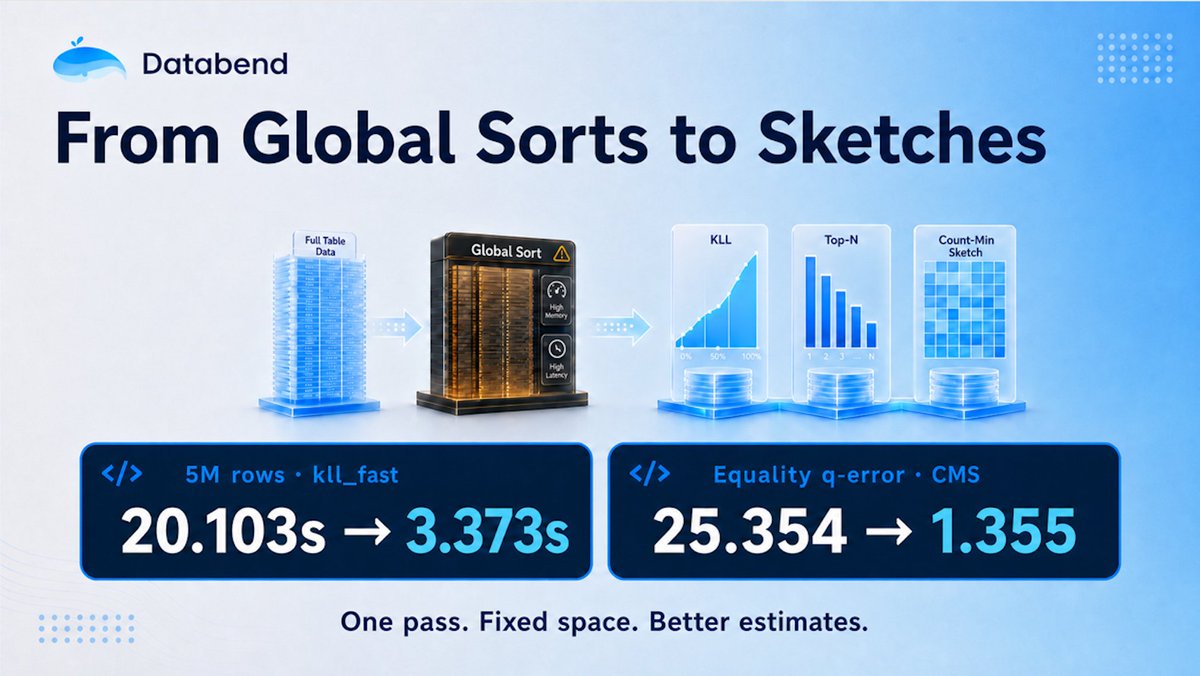
Global sorts make optimizer stats accurate and expensive.
Databend combines KLL for one-pass quantiles, Top-N for exact hot values, and CMS for a wider hot set.
In our benchmark, CMS cut equality q-error from 25.354 to 1.355. 🚀
Deep dive: https://t.co/gfwe32zbYV