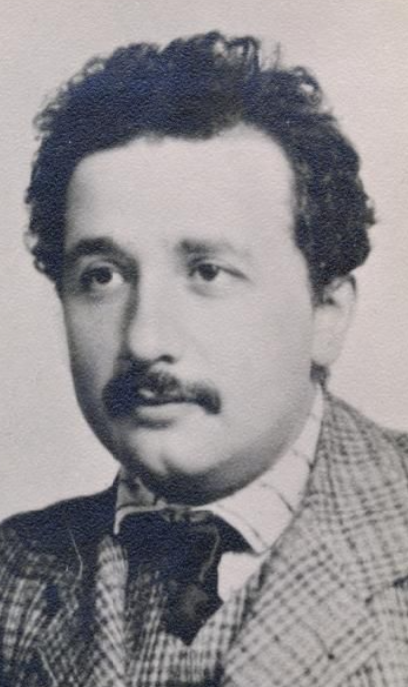
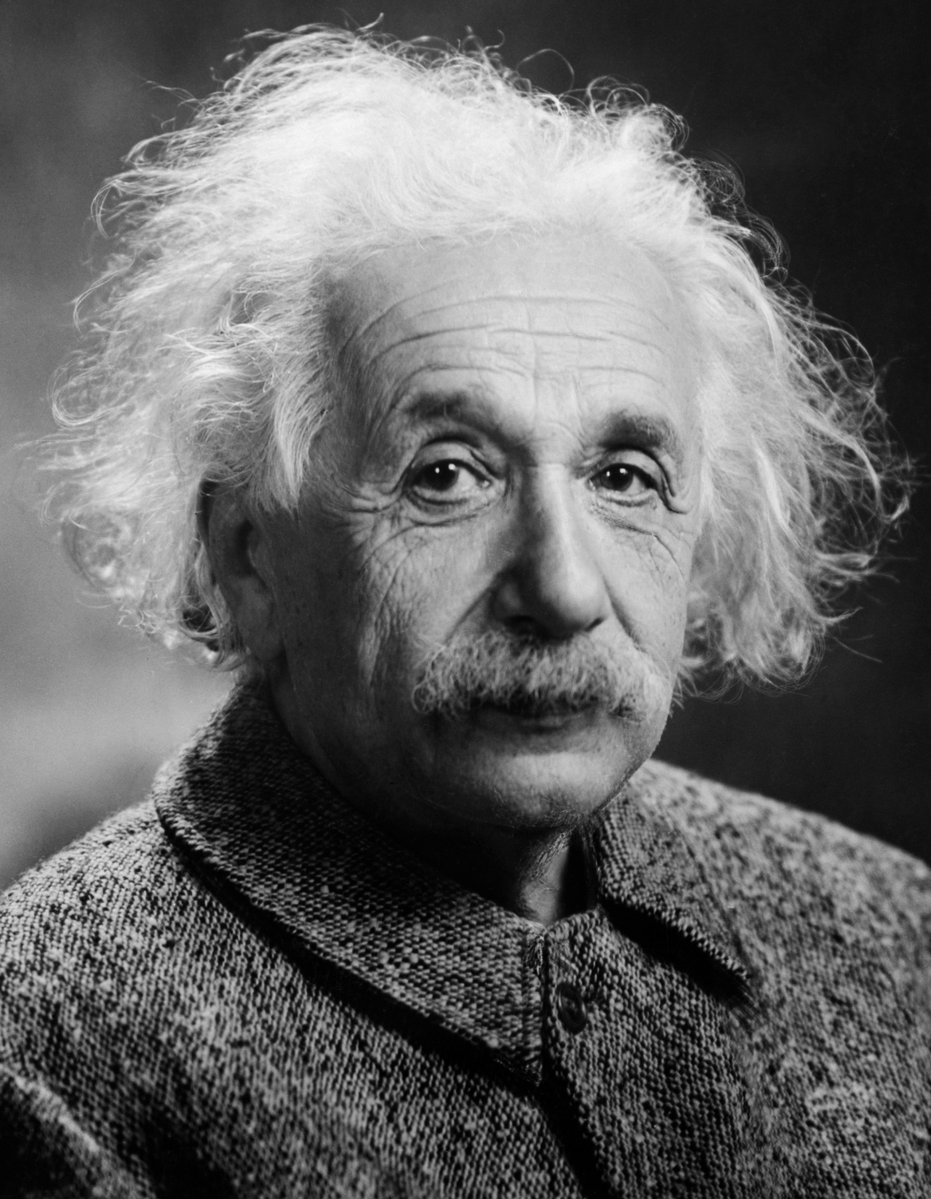Every time I see Einstein shown as in the left-hand photo, it makes me want to scream. Look at this white-haired old sage! Just who you'd expect to unravel the secrets of the cosmos, right?
At right: The actual Einstein of 1905, age 26.
@TheZvi Pointing it at Anthropic's "Prompting Claude Fable 5.2" and having it re-write the CLAUDE.md pretty heavily, as it was written for Opus 5.5, was helpful. Haven't started an ambitious project w/it yet, but I had it take over one I was already working on & I'm liking it more.
@SilverVVulpes@TheZvi I'm toying with a decent amount of the "why go to Fable 5.2 when Opus 5.5 does everything I need" comments being about usage price. Also you can put Fable on medium for better perf at the same price.
@TheZvi Huh? Fable's better at my main project. It's also much better at writing things that don't seem designed to wirehead me. No matter how I ask for an app to be built or hone in specifically on messaging/language, Opus 5.5 seems to write user facing text as though it's only for me.
The path to quantum runs through high-performance computing.
We’re excited to expand our collaboration with @PsiQuantum, bringing AMD compute and software together with photonic quantum technology to advance the next frontier of scientific discovery.
Learn more: https://t.co/LZgkYx4cXY
Claude Fable 5.2 sets a new record on the Epoch Capabilities Index (ECI) at 174. The previous high was GPT-6 Astra’s 169. Fable 5.2’s score is above what the pre-Astra trend for reasoning models would have predicted.
This is notable given recent discussion of AI contributions to AI R&D, and we hope to release more work in this area soon.
This is based on testing we did prior to launch using only our own benchmarks. The ECI is continually updated as more benchmark results become available, and may change in the future.
I know this is a predictable opinion from me but I don't agree with the strong emotional reaction against the anti-data-center movements that I've seen this week.
As I see it, algorithmic progress means that whatever you would be able to do with more and bigger data centers in 2 years, you will be able to do with the data centers we have today in 4 years - probably sooner. So nothing remotely apocalyptically bad will happen from even extreme levels of success by anti-data-center people.
Meanwhile we need all the time we can get to better harden the world against both already-visible cybersecurity issues and any bio and other risks soon to come. Science applications are bottlenecked by many things other than AI, so slowing AI down by one year will slow those down by much less than one year.
Given this, a slowdown in compute hyper-scaling seems quite net good? Notice this is without any controversial "doomer arguments", RSI etc. Even if net-bad, it's certainly not worse than like 10+ other political things.
Evidence is growing that we’re turning the corner on productivity.
US productivity grew at a 3.6% annual rate this past quarter.
That’s more than double the 1.5% average from 2007-2019.
The new numbers put me further ahead for my bet with Bob Gordon about productivity growth in the 2020s. 💪
Here’s how far the US is now ahead of the CBO estimate at the start of the decade (before they knew about the pandemic or LLMs) courtesy of @jasonfurman’s
Econvitals.
Laying into AI companies is more effective than you might think.
Gag clauses torn up.
~$75bn moved to the OpenAI Foundation.
OpenAI flipped on SB315.
Brockman quit his SuperPAC.
Anthropic backpedalled on its federal bill.
Reporters, lawyers, ex-staff, and shitposters on X got it done – with huge help from staff speaking up internally.
This month Anthropic, OpenAI and GDM gave us a counterproductive AI bill, dubious firings and fresh clauses gagging staff.
If you work at one of these companies: it's time to post in #general (metaphorically or maybe literally).
If you don't: consider becoming a sophisticated and strategic pain in the ass for these companies when they do bad things.
It’s a neglected career and probably high impact, especially for people who really get what's going on. I explain some options:
00:00 We need a stronger effort to push AI companies to do better
01:14 Anthropic: who gets to pull the brake?
07:14 OpenAI fires three safety researchers
12:44 Google DeepMind’s lifelong gag clause
5:39 Credit where it’s due
16:34 How to make AI companies behave better
17:31 Insiders: if you want to stay
18:40 Insiders: if you’re willing to leave
19:37 So… should you leave?
20:39 Outsiders: what’s already worked
22:51 Outsiders: digging up and explaining
25:12 Outsiders: reaching the public and politicians
00:27:52 Keep the pressure on
(On the 80,000 Hours Podcast, links below.)
The problem for me is that loads of my formative childhood memories actually were totally random insignificant things and I don't remember anything major my parents did for me. So all day I'm like "Maybe this play session is the thing they'll remember when they're 40"
We at AIFP are spooked by this information. IF (big IF) Anthropic really is imminently about to meet the RSP threshold of 2x acceleration over baseline, then it seems timelines to full RSI and superintelligence may be very short indeed. For example if we naively optimize the AIFM parameters to achieve 2x acceleration over baseline progress in Jan 2027, we get superintelligence sooner than depicted in AI 2027. We are thinking harder and longer about this now and will hopefully have a lengthier update on our thinking to share in the next week.
I actually think this speaks to a larger problem in this city about poor etiquette from guests in general.
- showing up to parties uninvited
- signing up for partifuls with no intention of showing up
- flaking for events without telling the host that you aren't able to make it (they bought drinks and reserved space for you, its the least you can do)
- showing up empty handed (!!) even if the party has tons of alcohol, you should still show up with a six-pack.
If you complain about SF parties but you aren't a good guest, you are part of the problem
ANTHROPIC: "we may imminently meet our Responsible Scaling Policy’s definition of 'dramatically accelerated progress attributable to AI.'"
"we do not anticipate being able to safely use Claude to fully autonomously design and build successive generations of frontier models"
New language added on page 29 of Anthropic’s S-1/A this morning says that internal estimates indicate they may imminently meet the RSI danger threshold of 'dramatically accelerated progress attributable to AI' - as much progress in one year as two years of the 2018–2024 baseline!
As a psychiatrist, I'm the person tasked with "give them our best efforts to heal them". So far these efforts are medications which marginally work, at the cost of mild side effects for most people and extreme side effects for a few. I don't see anything noble about ensuring that some fraction of people are doomed to be suicidally unhappy unless we give them meds that ruin their sex drive and make them slightly tired all the time, in which case they might make it to the tenth or twentieth percentile of happiness or something, and I don't understand why we should perpetuate this system of immiserate-then-medicate rather than having them be healthy to begin with.
Herasight's technology isn't interesting enough yet to cause crazy sci-fi moral problems like 'what if nobody could ever be unhappy' - the screening is weak, you can only select out of as much variation as exists in some small number of embryos, and you can only genetically select for one thing at once (so most parents will spend most of their optimization power on other things, so at best this will cut off a tiny bit of the extreme long tail of depression). But you're right that it's a slippery slope, and I do think that once we get more interesting technology, we should at least consider breaking the Torment Nexus, and that this will do less damage to the "human experience" than people think. See https://t.co/QOzvaFODew .
I've also written a little bit about 'helping people vs. excluding them from existence' at https://t.co/DbNQXxtiYp
We asked GPT-6 Astra to edit Qwen3.5-0.8B weights to improve math.
It directly changed only 0.016% of weights, fixing 0.8B's reasoning loops & improving math up to 6x and even instruction following 3x, without gradients or training.
We call this Weight-Space Programming: frontier LLMs can now natively read/write neural network weights! 🧵
Blog: https://t.co/bOWCcFhCVq