🚀 Introducing DeepSeek-V4.1-Flash: smarter, faster, more efficient.
🔹 Introducing the smallest model in our new architecture family, with native visual understanding.
🔹 Designed for greater capability, faster inference, higher throughput, and scaling to larger models.
1/6
DeepSeek-V4-Flash-Vision-Exp is now live on the DeepSeek API Platform! 🚀
🔹 This experimental multimodal model matches DeepSeek-V4-Flash on text capabilities—including agents, reasoning, and world knowledge.
🔹 On multimodal agent benchmarks, V4-Flash-Vision-Exp makes a major leap over V4-Flash, bringing multimodal agent performance close to Opus-4.8.
Try it with model='deepseek-v4-flash-vision-exp'. DeepSeek Harness 0.1.1 was released today with out-of-the-box support for the new model.
1/n
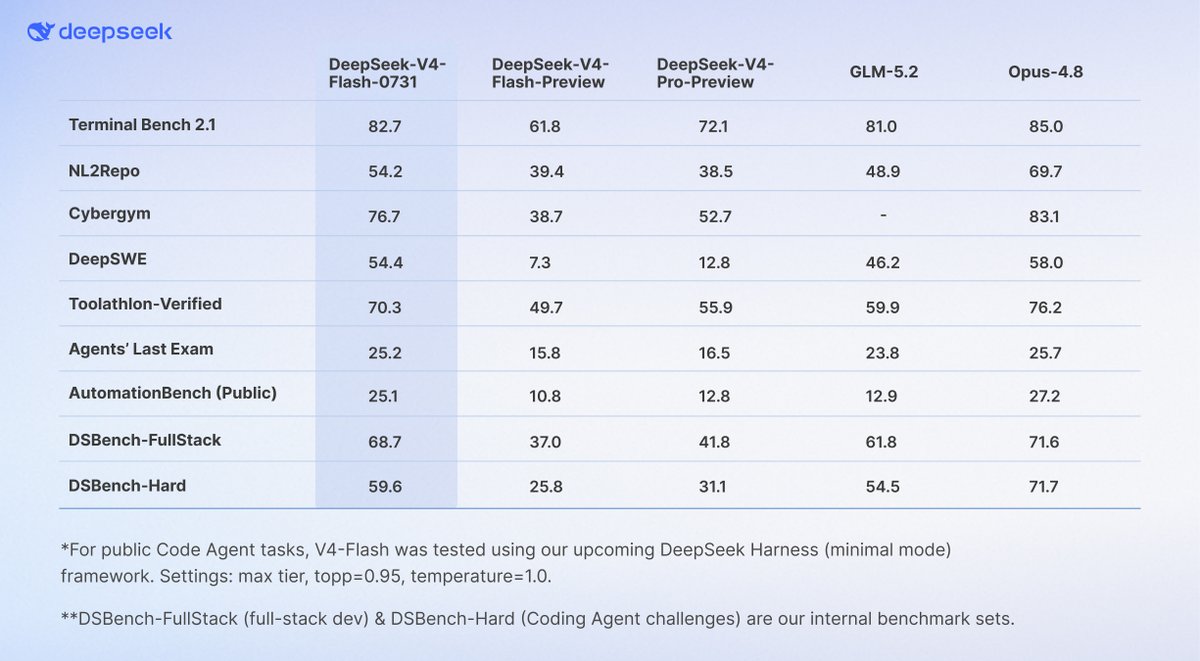
🚀 DeepSeek-V4-Flash Official API is now LIVE in public beta!
🔷 We’ve massively upgraded its Agent capabilities—benchmark scores are now far surpassing the V4-Pro-Preview. Check out the massive performance leap below! 👇
🔷 The official V4-Flash now natively supports the Responses API format and is fully adapted for Codex!
Check out the configuration details in our official API docs: https://t.co/smCwQZMeiq
🔥DeepSeek Input Cache Price Drop!
Effective immediately, the price for input cache hits across the ENTIRE DeepSeek API series is reduced to just 1/10th of the original price! Build more efficiently for less.
📌Reminder: The DeepSeek-V4-Pro 75% OFF promotion is still active until May 5th, 2026, 15:59 (UTC Time).
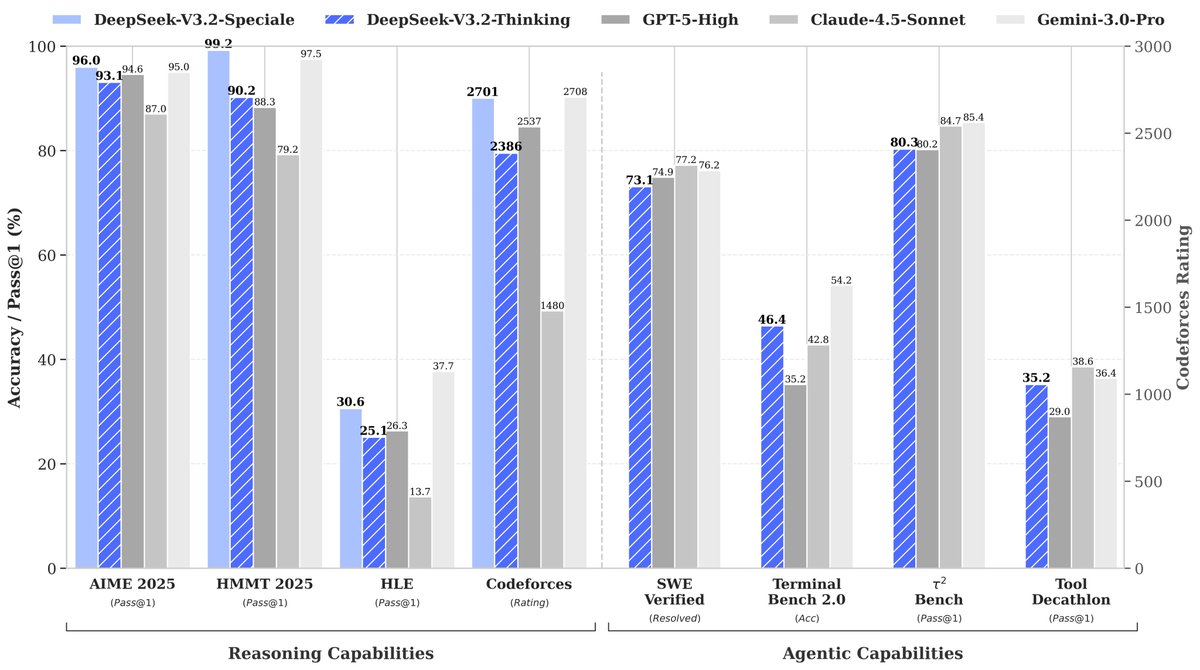
🚀 Launching DeepSeek-V3.2 & DeepSeek-V3.2-Speciale — Reasoning-first models built for agents!
🔹 DeepSeek-V3.2: Official successor to V3.2-Exp. Now live on App, Web & API.
🔹 DeepSeek-V3.2-Speciale: Pushing the boundaries of reasoning capabilities. API-only for now.
📄 Tech report: https://t.co/7EyydyNuG0
1/n
🚀 Introducing DeepSeek-V3.2-Exp — our latest experimental model!
✨ Built on V3.1-Terminus, it debuts DeepSeek Sparse Attention(DSA) for faster, more efficient training & inference on long context.
👉 Now live on App, Web, and API.
💰 API prices cut by 50%+!
1/n
Introducing DeepSeek-V3.1: our first step toward the agent era! 🚀
🧠 Hybrid inference: Think & Non-Think — one model, two modes
⚡️ Faster thinking: DeepSeek-V3.1-Think reaches answers in less time vs. DeepSeek-R1-0528
🛠️ Stronger agent skills: Post-training boosts tool use and multi-step agent tasks
Try it now — toggle Think/Non-Think via the "DeepThink" button: https://t.co/n8tODcbEz2
1/5
🚀 DeepSeek-V3-0324 is out now!
🔹 Major boost in reasoning performance
🔹 Stronger front-end development skills
🔹 Smarter tool-use capabilities
✅ For non-complex reasoning tasks, we recommend using V3 — just turn off “DeepThink”
🔌 API usage remains unchanged
📜 Models are now released under the MIT License, just like DeepSeek-R1!
🔗 Open-source weights: https://t.co/DmaMLhfngk
🚀 Day 6 of #OpenSourceWeek: One More Thing – DeepSeek-V3/R1 Inference System Overview
Optimized throughput and latency via:
🔧 Cross-node EP-powered batch scaling
🔄 Computation-communication overlap
⚖️ Load balancing
Statistics of DeepSeek's Online Service:
⚡ 73.7k/14.8k input/output tokens per second per H800 node
🚀 Cost profit margin 545%
💡 We hope this week's insights offer value to the community and contribute to our shared AGI goals.
📖 Deep Dive: https://t.co/x1rt3mCxF5
🚀 Day 5 of #OpenSourceWeek: 3FS, Thruster for All DeepSeek Data Access
Fire-Flyer File System (3FS) - a parallel file system that utilizes the full bandwidth of modern SSDs and RDMA networks.
⚡ 6.6 TiB/s aggregate read throughput in a 180-node cluster
⚡ 3.66 TiB/min throughput on GraySort benchmark in a 25-node cluster
⚡ 40+ GiB/s peak throughput per client node for KVCache lookup
🧬 Disaggregated architecture with strong consistency semantics
✅ Training data preprocessing, dataset loading, checkpoint saving/reloading, embedding vector search & KVCache lookups for inference in V3/R1
📥 3FS → https://t.co/JRZ2eYk1aK
⛲ Smallpond - data processing framework on 3FS → https://t.co/BoUA6YNjZK
🚀 Day 3 of #OpenSourceWeek: DeepGEMM
Introducing DeepGEMM - an FP8 GEMM library that supports both dense and MoE GEMMs, powering V3/R1 training and inference.
⚡ Up to 1350+ FP8 TFLOPS on Hopper GPUs
✅ No heavy dependency, as clean as a tutorial
✅ Fully Just-In-Time compiled
✅ Core logic at ~300 lines - yet outperforms expert-tuned kernels across most matrix sizes
✅ Supports dense layout and two MoE layouts
🔗 GitHub: https://t.co/cxJ55w61pT
🚀 Day 2 of #OpenSourceWeek: DeepEP
Excited to introduce DeepEP - the first open-source EP communication library for MoE model training and inference.
✅ Efficient and optimized all-to-all communication
✅ Both intranode and internode support with NVLink and RDMA
✅ High-throughput kernels for training and inference prefilling
✅ Low-latency kernels for inference decoding
✅ Native FP8 dispatch support
✅ Flexible GPU resource control for computation-communication overlapping
🔗 GitHub: https://t.co/Q6eRxZ9kgW
🚀 Day 1 of #OpenSourceWeek: FlashMLA
Honored to share FlashMLA - our efficient MLA decoding kernel for Hopper GPUs, optimized for variable-length sequences and now in production.
✅ BF16 support
✅ Paged KV cache (block size 64)
⚡ 3000 GB/s memory-bound & 580 TFLOPS compute-bound on H800
🔗 Explore on GitHub: https://t.co/4JvJTn5HX2
🚀 Day 0: Warming up for #OpenSourceWeek!
We're a tiny team @deepseek_ai exploring AGI. Starting next week, we'll be open-sourcing 5 repos, sharing our small but sincere progress with full transparency.
These humble building blocks in our online service have been documented, deployed and battle-tested in production.
As part of the open-source community, we believe that every line shared becomes collective momentum that accelerates the journey.
Daily unlocks are coming soon. No ivory towers - just pure garage-energy and community-driven innovation.
🎉 Excited to see everyone’s enthusiasm for deploying DeepSeek-R1! Here are our recommended settings for the best experience:
• No system prompt
• Temperature: 0.6
• Official prompts for search & file upload: https://t.co/I5CqmSzkTQ
• Guidelines to mitigate model bypass thinking: https://t.co/sAXK5U6OEr
The official DeepSeek deployment runs the same model as the open-source version—enjoy the full DeepSeek-R1 experience! 🚀