🚨NEW FOOTAGE: They used a blue light boat to stop the cameras
Two men on a small boat off Eastney.
RNLI on the beach with the arrivals.
Official boat moves in to push them back so they can’t film it.
You pay for the landing.
You pay for the coaches.
You pay for the boat that hides it.
SpaceXAI just released Grok 4.7
And it’s already showing a huge jump in multi-hour office work
Grok 4.7 outperforms GPT-6 Astra and is already nearly matching Fable 5.1
We trained 4.7 on longer-running problems compared to Grok 4.6. It holds context better and checks its own work more carefully.
Give it a try and let us know your feedback!
We put Grok 4.7 from @SpaceXAI to work on a $2 million insurance claim where one deductible error alone changes the calculation by $143,000.
In this Box Agent preview, @grok reconciles the claim against the policy and supporting records. It catches an $82,000 duplicate invoice and a missing $64,000 supplier credit. It also explains why the Business Income waiting period doesn’t apply to Extra Expense.
The result is a cited claims review for the adjuster, with final coverage and payment decisions left to the insurer.
Explore Box AI Studio to build custom agents for your own document-heavy workflows.
Grok 4.7 made this in blender.
I didn't tell it what to make but only that it should be something it can accomplish in 10 minutes or so.
Honestly not bad at all. Not bad at all.
Did they train Grok on blender?
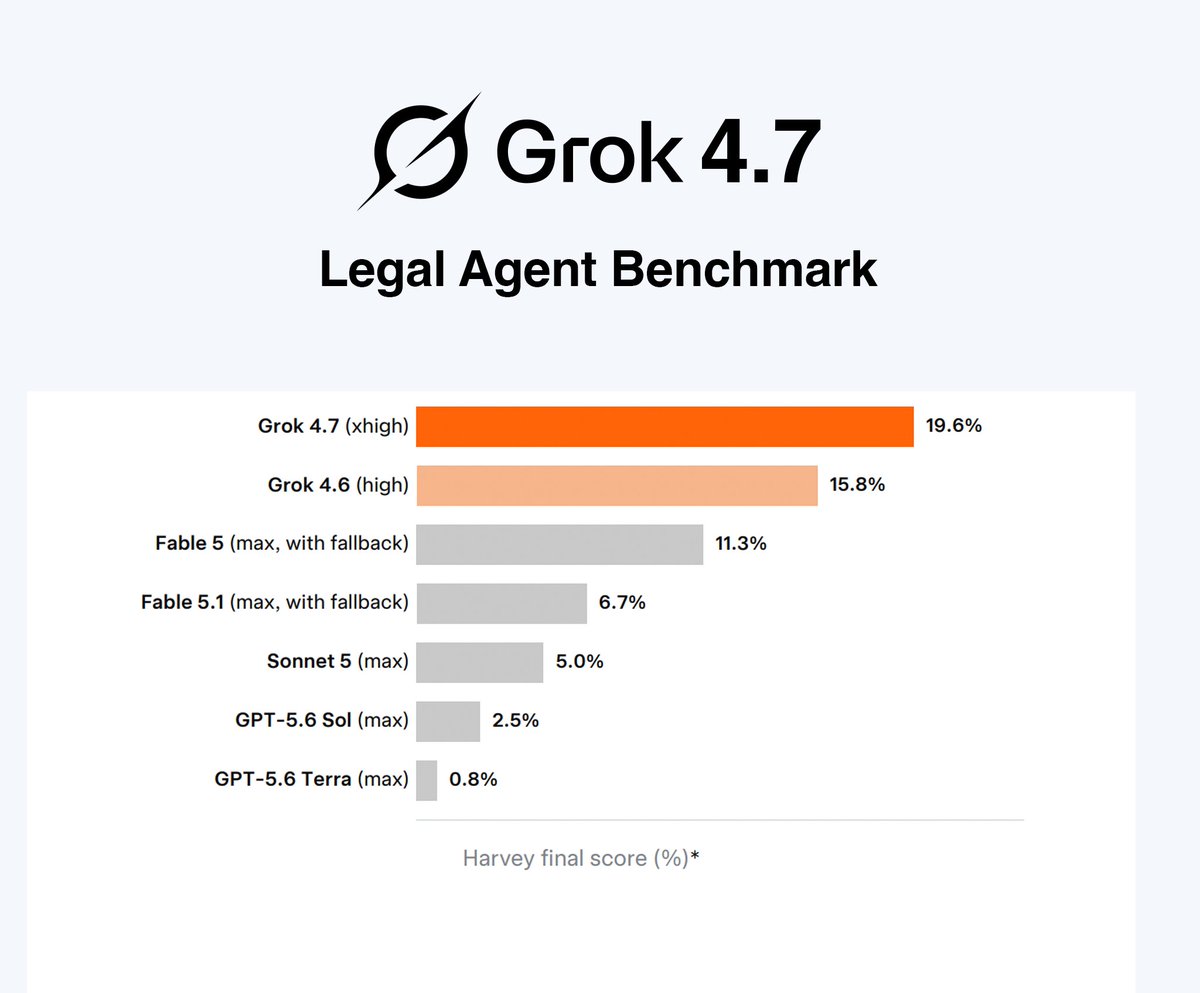
BREAKING: Grok 4.7 dominates the Legal Agent Benchmark.
It scored 19.6% on realistic, long-term legal tasks, beating every other model tested. That is nearly 3× Fable 5.1.
Another major win for Grok 4.7 and SpaceXAI.
“I’ve used FSD for like 90%+ of my miles since Saturday morning. Literally feels like magic. Has handled issues on the road better than I would have at times.
Just remarkable technology”
A demo drive might change your life
https://t.co/YkC5K8ofeR
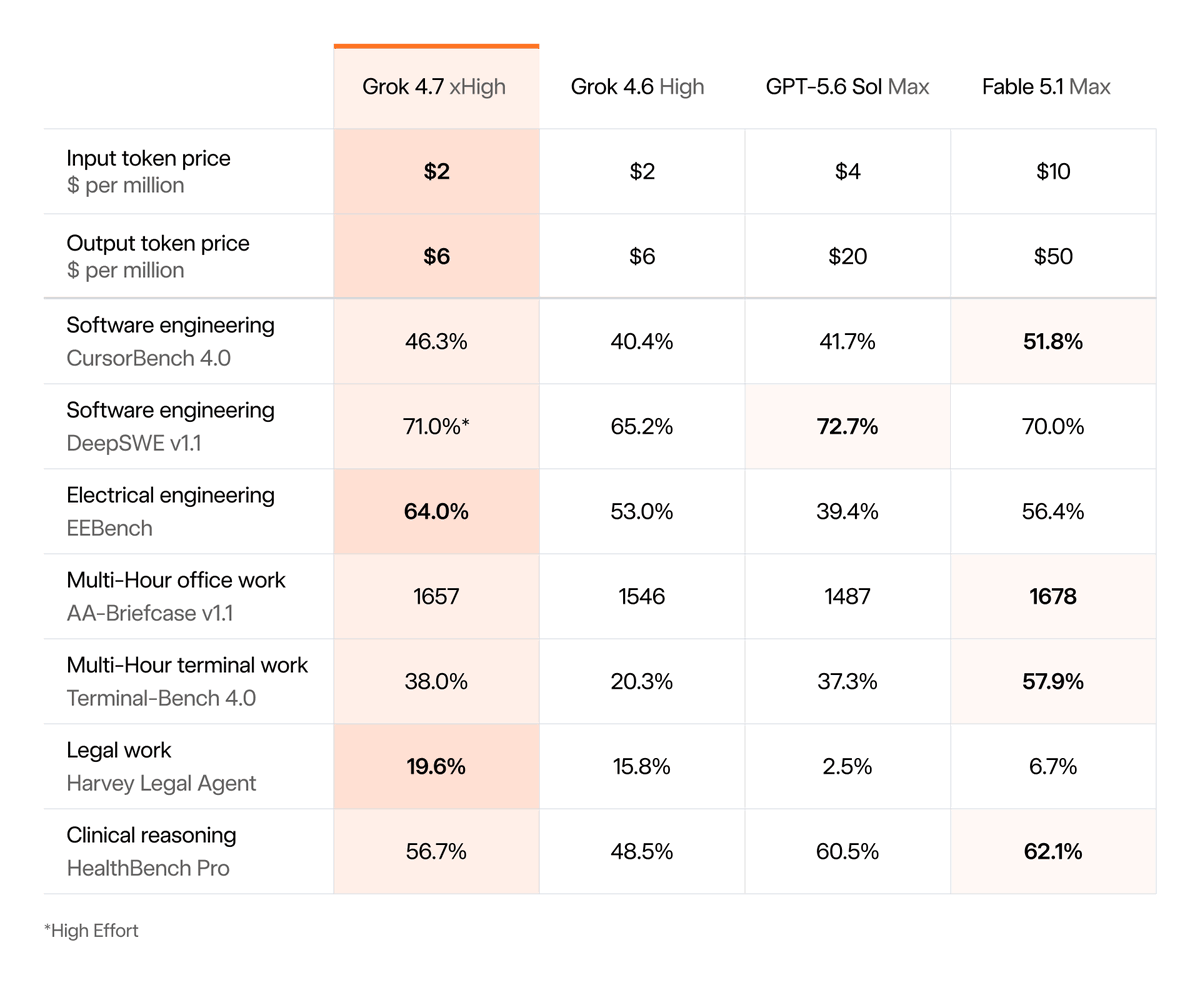
and here’s the grok 4.7 model card. a few jumps vs 4.6 that stood out:
- Terminal-Bench: 20.3% → 38.0%
- SWE-Marathon: 31.9% → 46.0%
- HealthBench Pro: 48.5% → 56.7%
- Legal Agent: 15.8% → 19.6%
- EEBench: 60.0% → 66.0%
for the same price as 4.6!
https://t.co/C0iyfYirQf
Grok 4.7 xHigh is now at the top with just ONE point away from Claude Fable 5.1 Max on Artificial Analysis’ AA-Briefcase benchmark
Claude Fable 5.1 Max — 59%
Grok 4.7 xHigh — 58%
Just a 1-point difference at the very top
And Grok is ahead of GPT-6 Astra, GPT-5.6, Gemini, Kimi, GLM and nearly every other frontier model on the benchmark
Grok 4.7 just released and it's an EXCELLENT model
It was trained FOR Grok Bot
Meaning this is a fully agentic model trained to do your knowledge work better than you can
In this video I show you how to use Grok 4.7 and a Grok Bot workflow that will 10x your productivity: