This is how we bring AI inference to microcontrollers, without the complexity of switching frameworks. The new @Executorch Cortex-M backend uses @Arm CMSIS-NN to accelerate @PyTorch models on Arm Cortex-M CPUs. Take a look at the report here: https://t.co/hWq5MVRgFo
Hardware-Aware AI: Building Agentic Systems from Cloud to Edge with PyTorch, ExecuTorch
AI agents are moving beyond chat interfaces and onto physical devices. In her upcoming session on Hardware-Aware AI at PyTorch Conference North America 2026, Kavya Sri Chennoju from @Arm will demonstrate how PyTorch, ExecuTorch, and Arm Device Connect work together to deploy AI agents safely onto edge hardware such as robot arms and wearables.
Join the open source AI community in San Jose, October 20-21: https://t.co/jBApW8nESi
#PyTorchCon
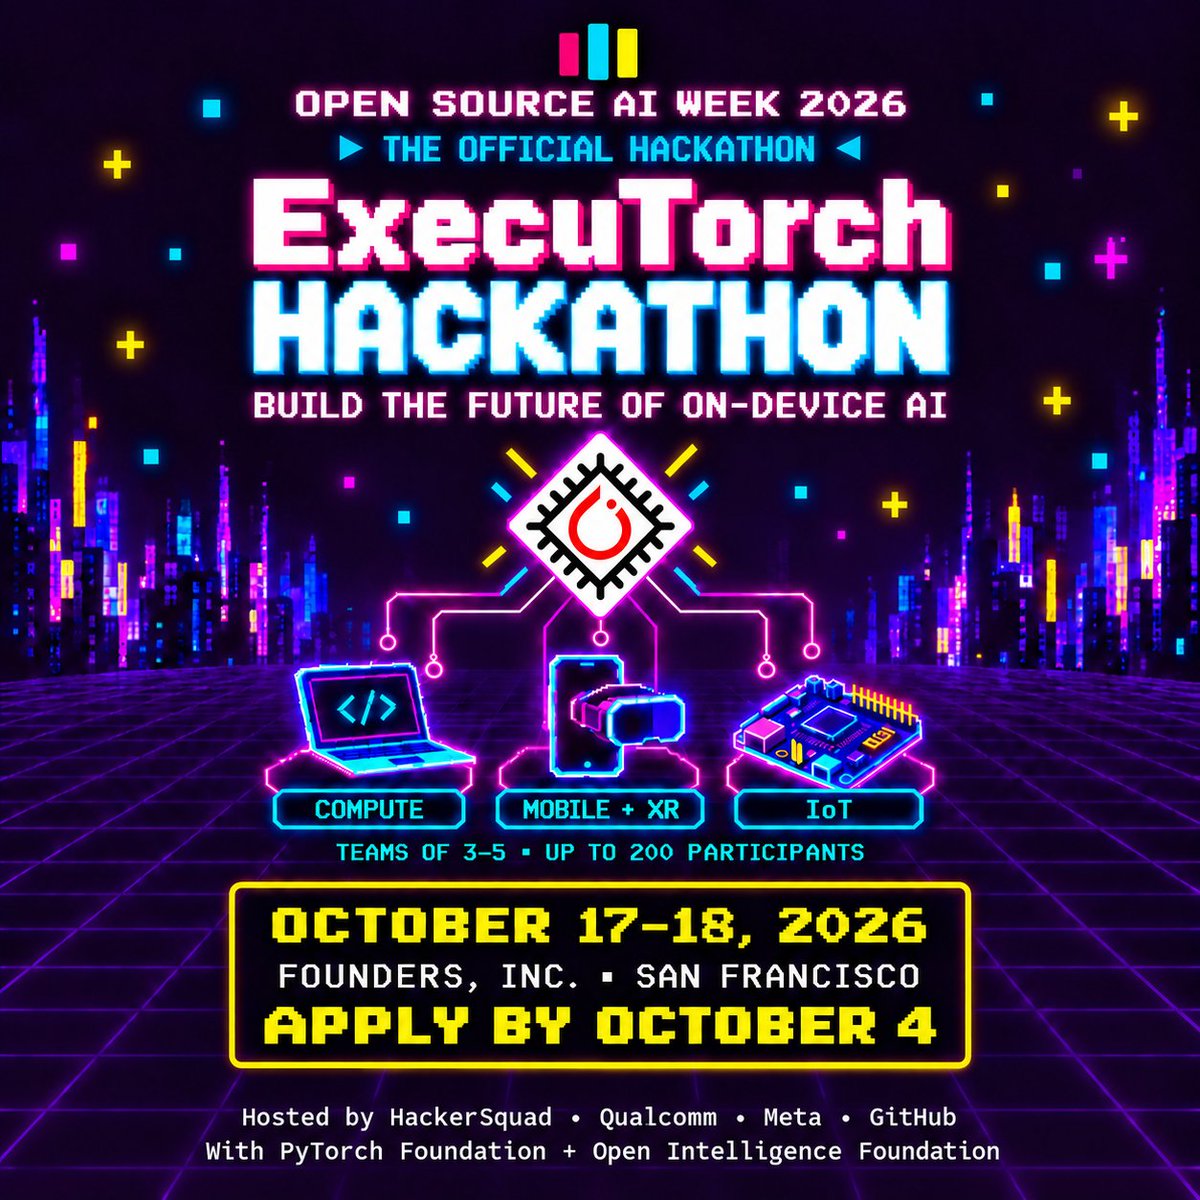
Bring your ideas. We’ll bring the hardware.
Two days to build with open models, on-device inference, and real devices at the ExecuTorch Hackathon—part of Open Source AI Week.
📅 October 17–18 · Founders, Inc., SF
⏳ Project proposals due October 4
Form a team of 3–5, build with @Executorch, and help shape the future of open-source, on-device AI.
🏆 Prizes include Meta AI glasses and Arduino UNO Q boards.
Apply → https://t.co/lWOCGOqZ7C
With @hackersquadio@Meta@Qualcomm@github@fdotinc
#OpenSourceAIWeek #OpenIntelligence
Build AI on the edge with ExecuTorch at a two-day @Meta + @Arm hackathon at San Francisco State University.
Students, developers, and AI enthusiasts can get hands-on experience building AI applications with ExecuTorch on Arm-powered devices, with technical talks, demos, workshops, and mentorship.
Participants will also have the chance to collaborate with fellow builders, showcase their projects to judges from Arm and Meta, and compete for prizes and recognition.
🔗 Learn more and register: https://t.co/pOQ3B5vMWm
We did it! ExecuTorch team won the Best Industry Paper Award @MLSysConf 2026. Come meet us at the conference next week.
Discord: https://t.co/Yi81hwDFUc
Paper: https://t.co/lRsuFMqar9
Project: https://t.co/VEjOFj8e25
Schedule: https://t.co/1spj9aMmiH
Big congrats to the ExecuTorch team. Their paper just won the Best Industry Paper Award at @MLSysConf 2026. 🏆
ExecuTorch is PyTorch's framework for running models on-device, in production today across phones, wearables, desktops, and embedded systems. Backends include Apple, Arm, Qualcomm, MediaTek, Samsung, NXP, Cadence, Intel, NVIDIA, and others.
Catch the team Tuesday morning in the Best Paper Session ( AM PT) and at the poster session Thursday evening.
Paper: https://t.co/QlnMdybCOw
Discord: https://t.co/KsiEOO5ujC
X: https://t.co/lkYgcC8y6n
Project: https://t.co/v6wCXYtJkz
Schedule: https://t.co/vgNGvcoLHO
Launching SimCam – a tool that finally lets you test camera features directly in the iOS simulator! 🚀
🎦 Stream video from your Mac's built-in or external camera, inject an image or video, or generate a QR code.
🎙️Run Voxtral Realtime locally with ExecuTorch!
💻Thanks to the ExecuTorch team, you can now deploy and run Voxtral Realtime efficiently and fully offline on your MacBook.
ExecuTorch as an external Zephyr module!
You can now use #ExecuTorch in #Zephyr. Together with #Arm, we enabled Zephyr integration and run models on CPU and Arm Ethos-U NPUs with ExecuTorch. Checkout the documentation here: https://t.co/RM1SZCpLWT
The #MLX delegate has landed in ExecuTorch(https://t.co/ErOa01l4BI) and is available on main in OSS. It delivers SOTA GPU performance on #macOS for GenAI models, with 3-6x greater throughput than what was previously possible with #ExecuTorch.
SqueezeSAM on-device, accelerated 🚀
With ExecuTorch and Arm SME2, SqueezeSAM image segmentation achieves up to 3.9× faster inference, reducing FP16 latency from over one second to ~300 ms on a single CPU core.
This makes responsive, interactive on-device AI practical on mobile CPUs, no GPU required, while preserving headroom for richer user experiences.
A strong example of how hardware-aware optimization and operator-level profiling can materially change what’s possible for on-device ML.
🔗 Read the blog: https://t.co/EyO9F5x5xc
👥 Gian Marco Iodice, Damien Dooley, Tyler Mullenbach, Jason Zhu
hashtag#PyTorch hashtag#ExecuTorch hashtag#OnDeviceAI hashtag#OpenSourceAI hashtag#MachineLearning
@FrancoPaludi1@PyTorch@grok Yes, Franco. They can be exported and lower to the xnnpack delegate. The steps to repro the results are here: https://t.co/mwv8Ok8LsV
If you get stuck on it somehow, join our discord at https://t.co/JthY8sVLJU and we can figure out what's going on together.
TorchAO Quantized Gemma-3 Models Now Available on HuggingFace 🚀
TorchAO quantized Gemma-3 models (4b, 12b and 27b) are now available in multiple quantized formats (FP8, INT4, AWQ-INT4, HQQ-INT8-INT4, QAT-INT4) on HuggingFace Hub! Our models:
* Run efficiently on A100/H100 GPUs (with vLLM) & mobile devices (with ExecuTorch)
* Deliver faster inference, big memory savings, and minimal accuracy loss compared to BF16 model
* Include reproducible quantization recipes for your own models, including algorithms like AWQ, HQQ and QAT
🖇️ Check out the collection: https://t.co/hAEeQuqSIL
#LLM #PyTorch #TorchAO #ExecuTorch #VLLM #Quantization #Gemma3 #HuggingFace #EdgeAI