I am beyond words. what an amazing weekend so far.
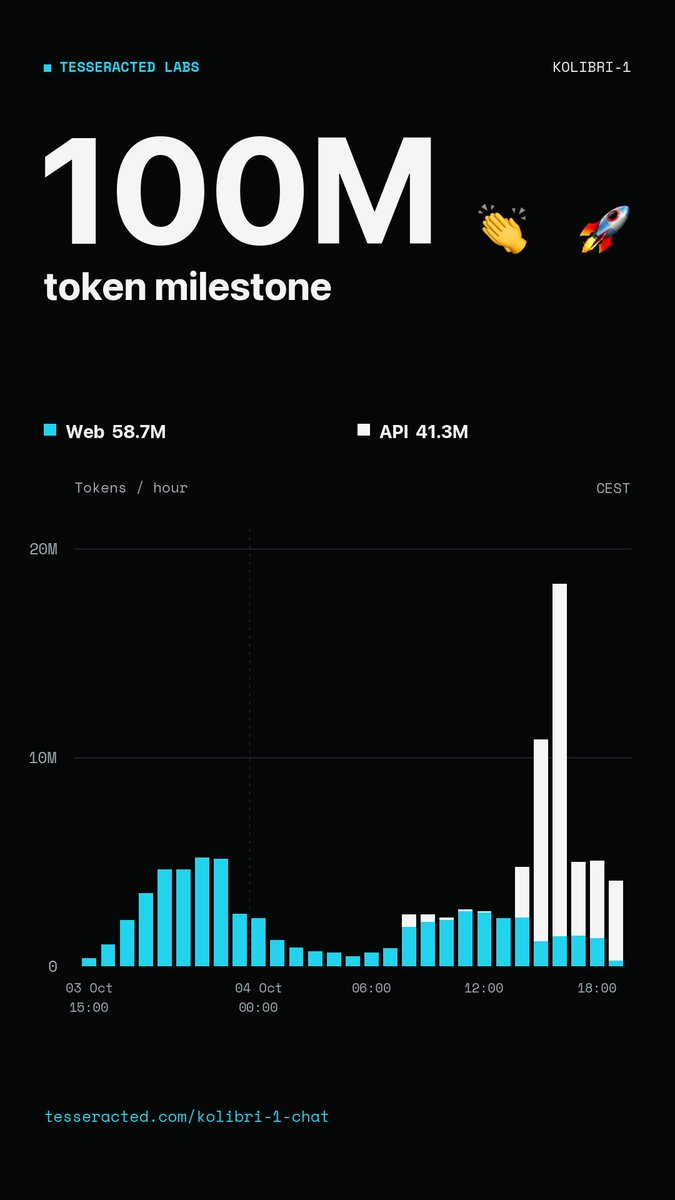
Just crossed 100Million tokens on the free hosting of @Aleph__Alpha Kolibiri-1 model.
What a great model architecture that it runs with a bliss - Kudos to @IlhanScheer and the @Aleph__Alpha team 👏🎊
Still lot to offer, so please continue leveraging the Chat UI and the APIs.
Highlights the power of community and open ecosystems.
We started the year with the conviction that Europe needs its own sovereign AI. Built in Germany from scratch and on infrastructure in Europe specifically for our customers.
This weekend, we released Kolibri.
Meet the team behind it 🧵
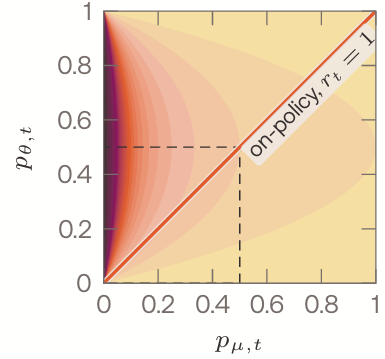
The exact infinity norm of the logit gradients is just p_theta (1 - p_theta) / p_mu, which is cheap to compute and we clip per token. CISPO is similar, but the closed form is just mathematically satisfying.
Details in Sec. 3.2.1.2 of our tech report: https://t.co/dRR073WDOm
My favorite reinforcement learning plot from our Kolibri report: Inference v.s. training log probs, background is the logit gradient norm of importance-sampled Reinforce. Numerically unstable for small inference log-probs, but you can do exact token-level gradient clipping in RL.
Small bird, fast wings, Kolibri is here.
78B parameters. 3.46B active. Up to 1M tokens of context. Built in Europe.
Now the weights are yours. Run it on your own hardware, under Apache 2.0.
Small bird, fast wings, Kolibri is here.
78B parameters. 3.46B active. Up to 1M tokens of context. Built in Europe.
Now the weights are yours. Run it on your own hardware, under Apache 2.0.