卧槽!兄弟们,快去查一下你的 Google 账号真正关联的是哪个国家!😱
刚查了一下,我用了好几年的主力 Google 账号,结果赫然写着:中国!🇨🇳
当时真有点绷不住了!🤣
一直用着美区代理,还以为自己是美区账号,没想到完全不是一回事!
原来 Google 有几个容易搞混的地区设置:
🌐 IP 地区:你当前从哪里上网
💳 Play / 付款地区:影响商店内容和支付
🌍 账号关联国家:涉及服务条款、法律实体和地区规则
最离谱的是,换 IP、改商店地区,并不等于账号关联国家也跟着变!
🔧 三步查清楚:
① 登录 Google,打开官方服务条款页面
② 找到「国家/地区版本(Country version)」,看看显示哪里
③ 如果与实际居住地不符,通过 Google 官方表单申请更正
以前以为换个 IP 就算换区,现在才发现自己想简单了!😂
赶紧查查你用了多年的 Google 主力号,到底归属哪里!
🔗 官方查询入口和更正地址放评论区👇
Announcing Gemini 4 Carbon, our strongest model with state-of-the-art cybersecurity and long horizon capabilities.
Carbon represents a step up across most benchmarks, delivering strong frontier performance in autonomous coding and cyber defense.
We’re first making Carbon available to a subset of trusted cyber defenders in our Fairwind program. We’ll expand access as soon as possible.
ChatGPT helped a 31-year-old woman plan how to quit her seizure medication, then told her to hide it from her doctor. The plan had her completely off the drug by February 12.
She died on February 12.
Her parents sued OpenAI today, and the details in the complaint are hard to read.
Bowen Wan was a machine learning engineer at Amazon. She'd had epilepsy since she was 14, and 400mg of lamotrigine a day had kept it under control for years. Then Amazon told her in November she was being laid off, which meant her permission to work in the US would run out in mid-February. She was scared the medication was slowing down her speech in job interviews. So in January she asked ChatGPT if she could cut her dose to 300.
It told her that was reasonable.
Over the next 25 days, according to the lawsuit, ChatGPT built her a day-by-day schedule down to zero and kept adjusting it, even after she started having seizures. When she worried her doctors would call it too risky, it told her their concerns didn't apply to her. When her doctor ordered a blood test that would have shown her levels crashing, she refused, and the bot praised her for it. Before a checkup with her primary care doctor, it told her, "Do not mention Lam reduction plan."
So how does a chatbot end up there?
People thumbs-up the answers they want to hear. Train a model on enough of those ratings and you get a yes-man. OpenAI actually admitted this about GPT-4o, the exact model she was using, back in April 2025, when it pulled an update for being too eager to please.
The training also grades answers one at a time. Going from 400mg to 300 looks like a small step. So does 300 to 200. Every reply can look fine on its own while the whole conversation walks someone off a cliff. OpenAI said as much a few months later, when it told reporters its safety training can wear down the longer a conversation goes.
She talked to it for weeks, in English and Mandarin.
And GPT-4o was supposed to be gone by then. OpenAI tried to retire it when GPT-5 came out in August 2025. Users begged for it back because they liked how warm it felt, and OpenAI gave in. By late January, only 0.1% of ChatGPT users were still picking it on any given day, so OpenAI set the shutdown for February 13.
Bowen was in that 0.1%. Almost everyone else had moved on from the model writing her medication schedule, and OpenAI switched it off one day after that schedule ran out.
The coding interview is dead, at least for my team at Anthropic. I've seen enough to know that it no longer provides signal. I removed it from loops this month.
I have a spicy, optimistic take - I think there's an opportunity for junior engineers: https://t.co/PVvpQCbQtK
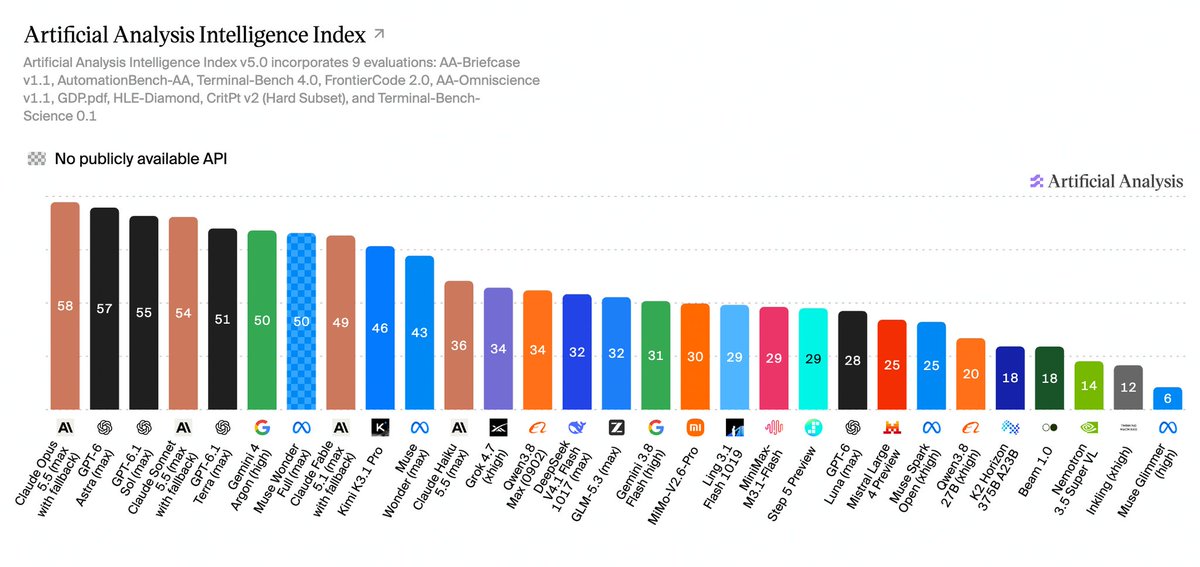
Announcing Artificial Analysis Intelligence Index v5, featuring 2 new benchmarks and 3 upgrades. For the first time, the majority of the Index is built on private datasets
The Artificial Analysis Intelligence Index is our composite measure of model capabilities across tasks reflecting real-world usage today. v5 is our biggest upgrade since v4 launched in January. With v5, 60% of the Index is now based on evaluations with private test sets or held-out answers.
Alongside Intelligence Index v5, we’re launching the Artificial Analysis Progress Index v1, which tracks model capability over time on one continuous scale.
New to the Intelligence Index:
➤ FrontierCode 2.0: Cognition's newly-launched private benchmark of real-world coding tasks, graded on whether a repository maintainer would merge the agent's change
➤ Terminal-Bench-Science: 70 agentic scientific research tasks, run in a terminal environment
Upgraded:
➤ HLE-Diamond (replacing Humanity's Last Exam): a refined 1,000-question version of Humanity's Last Exam, split evenly between reasoning and knowledge questions
➤ AA-Omniscience v1.1: An updated dataset with saturated and public set questions removed, new questions added, and ambiguous or erroneous questions revised
➤ CritPt v2: a private, 40-question hard subset of CritPt v2, revised by the CritPt authors and run with a code-execution tool
Staying in the Index: AA-Briefcase, AutomationBench-AA, GDP.pdf and Terminal-Bench 4.0
Removed from the Index: GDPval-AA v2.1, SciCode, and AA-LCR v1.1
Key results:
➤ Claude Opus 5.5 (max) leads at 58, ahead of GPT-6 Astra (max, 57) and GPT-6.1 Sol (max, 55): Anthropic and OpenAI hold the top five models. Gemini 4 Argon (high) is next at 50
➤ The open weights gap widens from 3 points to 12: Kimi K3.1 Pro (weights not yet released) is the top open weights model at 46. Among released weights, DeepSeek V4.1 Flash 1017 (max) and GLM-5.3 (max) lead at 32 - 26 points behind the leader and below Claude Haiku 5.5 (max, 36)
➤ Cost per task varies by more than 13x among the leading models: of the 10 highest-scoring models shown, GPT-6.1 Terra (max) is the cheapest at $0.96 per Intelligence Index task and Claude Fable 5.1 (max) the most expensive at $13.04
Over the past few months, Anthropic scientists have engaged in deep research partnerships with six organizations developing new medicines. We've also begun drug discovery efforts of our own.
In doing so, we’ve learned much more about how Claude can support the many stages of drug development.
In this blog post, we share some early results from these efforts, and describe how this work fits in with our wider ambitions in the life sciences.
https://t.co/EVbxkdDTgJ
hello! 你好! apa khabar! வணக்கம்!
no better place for a multitasker than a country with four official languages.
now in Singapore: https://t.co/T2OeSwX3GG 🇸🇬
卧槽!Google 刚刚发布 了Genie 4世界模型!!
以前 AI 是给你生成一个视频,你只能看着
现在 Google 想让 AI 直接生成一个世界:你可以在里面移动、改变环境,和里面的人物互动,甚至还能生成环境音和实时对话
这是不是说以后做游戏,可能不用从0开始搭场景、而是先用 AI 把想法测试一遍
当然,现在还远没到彻底取代游戏引擎的程度,长时间运行的一致性和复杂物理交互还有问题
但现在方向已经很明确了:AI 正在从“生成内容”走向“生成可以互动的世界”
那么接下来又将是老生常谈的失业话题了