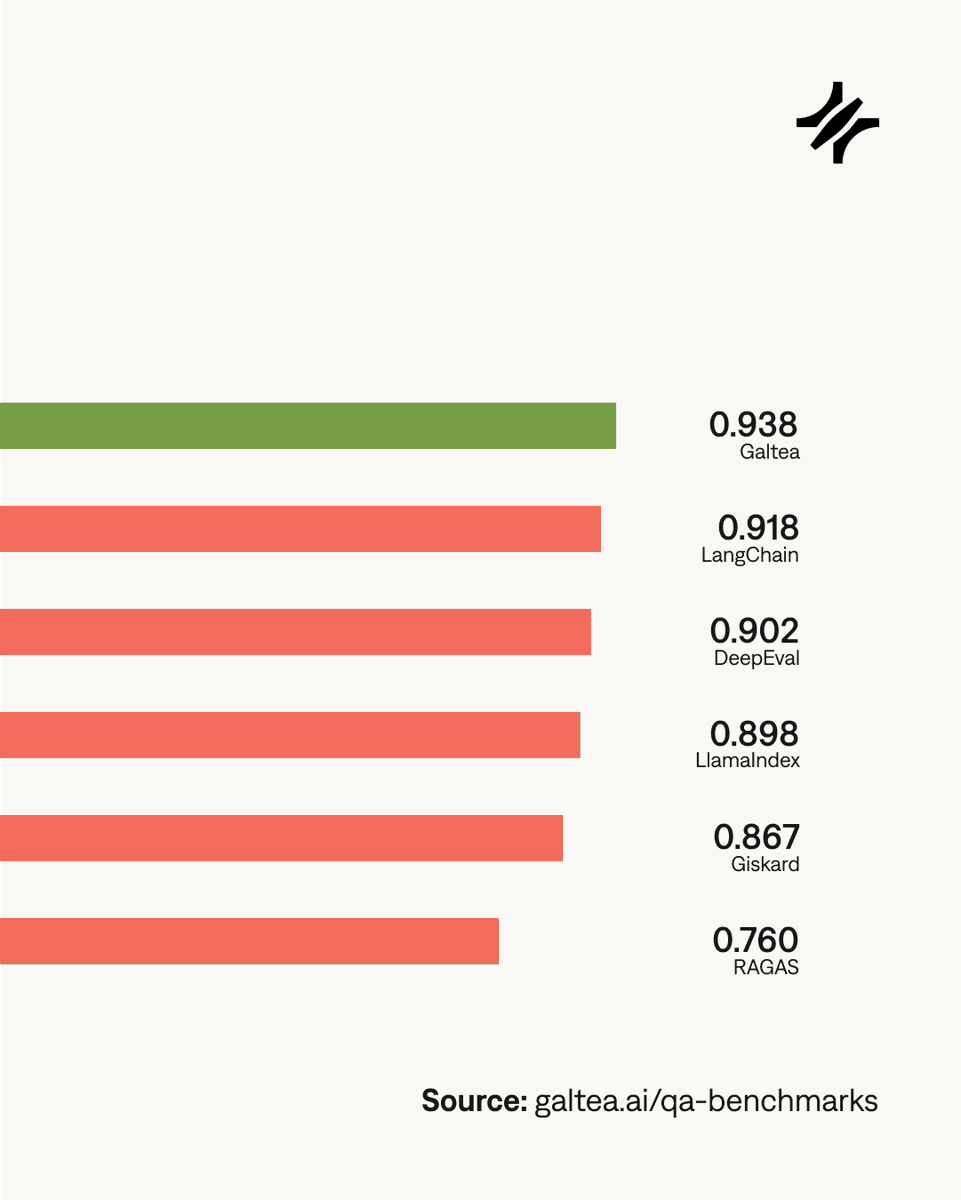
We tested a generic GPT-4.1 LLM judge with a standard faithfulness prompt.
30 examples. 9 hallucinations. Hallucinations caught: 0/9.
If your eval pipeline runs this way, it's producing false confidence exactly where confidence is most dangerous.
https://t.co/uTDXvIo0qi