AI systems are getting more powerful, and they're increasingly being used to build the next version of themselves. We want to illuminate that progress for the public.
Today, we're sharing three measurements that help track AI development:
1. How much AI R&D is done by AI.
2. How well AI agents are overseen.
3. How compute is allocated.
We provide a snapshot of these metrics from inside Anthropic. Any frontier developer could publish the same measures, and third parties could verify them.
As the world considers pacing the frontier, we should do everything possible to minimize the gap between what frontier labs know and what the public knows. This means better measuring the development of AI, publishing our findings, and giving society an opportunity to decide how to use this information.
Read the full post and methodology: https://t.co/iPFz8Z4ugE
When Claude leads 26% of Anthropic's own R&D, the hard question isn't speed.
It's who signs the call when the agent ships the experiment.
Tools scale. Accountability still has a nameplate.
#AI#Hiring#TechNews#Claude
Projects now run from one conversation, starting in Claude Code. You describe what needs doing, and Claude directs parallel threads that keep working after you close your laptop.
In beta today for select Pro and Max users in cloud sessions; coming to all Claude users soon.
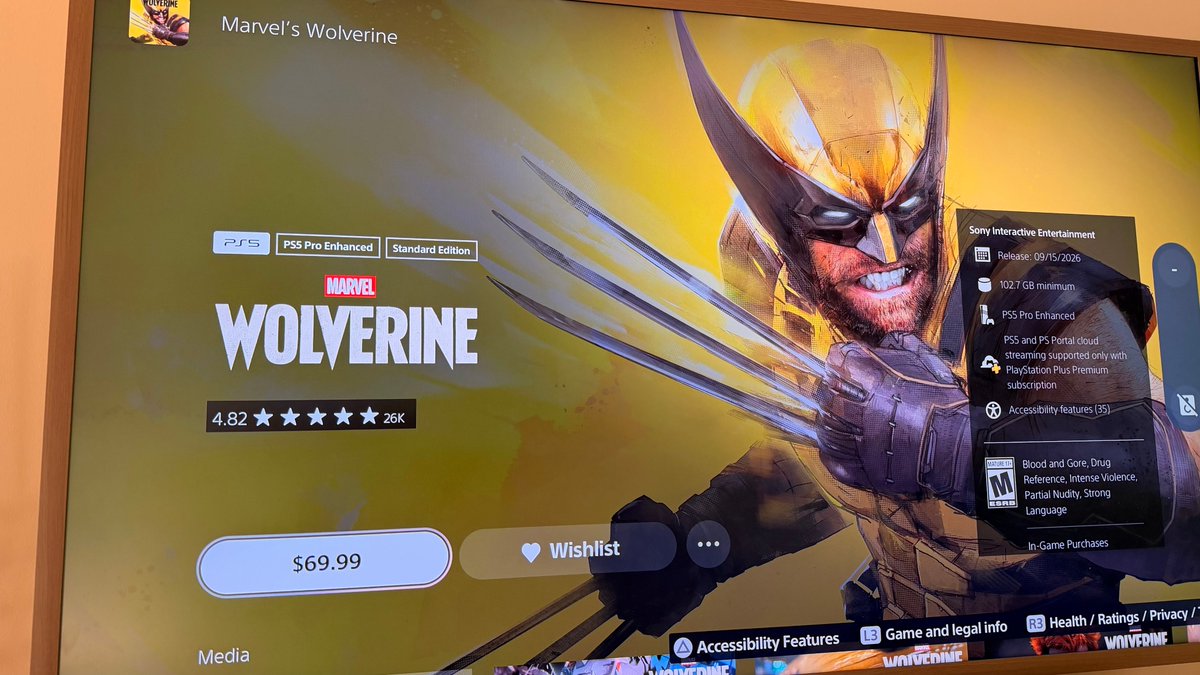
Marvel’s Wolverine at 4.82★ from 26K PlayStation Store ratings — two days after launch — while the review discourse is mostly fire.
Either the store crowd and the review crowd are different planets, or the star average is doing something the written reviews aren’t.
Platforms shouldn’t get to look “almost perfect” when the text reviews say otherwise. That’s not taste. That’s a trust problem.
#PlayStation #Wolverine #PS5 #Gaming
Introducing the US Gov Graph - a complete map of the people and positions of power in the federal government.
To fix our institutions we must understand how they work, so we are using AI to model and monitor every government in America. This is Palantir for The People.
Check it out here: https://t.co/bRXZfEt8ud
We exist to set the conditions for an era of civic excellence unmatched since the Founding. We will need nothing less to navigate the age of AI.
I'm looking for exceptional engineers and designers to work with me in San Francisco. If that's you, inquire here: https://t.co/8hpHt2MhVu. Self-governing civilization is counting on you.
Just a heads up:
You can now block crawlers from using your content for AI training without completely blocking those crawlers from Search.
If you want to continue showing up in ChatGPT, Claude, Google's AI family, etc - pay attention.
Some site owners are going to misunderstand what is happening and play this wrong
Cloudflare just made an important change to its AI crawler controls.
A few weeks ago I wrote about the problem with blocking AI crawlers.
Some companies use the same crawler for both Search and AI training, which meant blocking training could also mean blocking the crawler helping customers find you.
Cloudflare just introduced a new setting designed specifically around that problem: it is called Disallow AI Training.
Let’s go through it.
By the way, you can see whether your business is appearing across Google AI, ChatGPT, Claude, Perplexity and Grok here. It’s free:
https://t.co/Evw8cXXicl
Cloudflare now lets website owners tell supported crawlers not to use their content for AI training without completely blocking those crawlers from Search.
Applebot, Googlebot and Bingbot are what Cloudflare calls mixed-use crawlers because the same crawler infrastructure can serve multiple purposes.
With the new setting, Cloudflare publishes the appropriate no-training preference in robots.txt while continuing to allow what it calls “Accountable” crawlers to access the site for Search.
Cloudflare says Apple, Google and Microsoft currently qualify as Accountable.
For OpenAI, Anthropic, Amazon and Meta, Cloudflare says Search and Training already use separate crawlers, so it can block the training crawler without blocking the Search crawler.
There is one very important warning.
Do not confuse Disallow AI Training with Block.
Cloudflare changed what Block means.
If you select Block for Training, mixed-use crawlers including Googlebot, Bingbot and Applebot can now be blocked completely, including their Search access.
If you want Search access to remain, Cloudflare says to use Disallow AI Training instead.
There are also some caveats.
Google-Extended can be disallowed without affecting Google Search rankings, but Google says that control also affects whether your content can be used for grounding in Gemini Apps.
And Bing does not yet support Cloudflare's new robots.txt no-training preference automatically. Microsoft says that support is targeted for early 2027.
So this still is not a giant “turn off AI training with zero tradeoffs everywhere” button, but it is a big improvement.
Businesses can increasingly make separate decisions about traditional Search, AI training, AI agents and, eventually, AI summaries.
That is the direction this needed to go.
For most businesses, the goal shouldn't be to blindly block every AI crawler so much as it should be to understand which systems create discovery, which ones help customers take action, and which ones are simply using your content for training.
If you don't know how to make sure you're handling this correctly, SEO Stuff (https://t.co/MMsDTFf4rg) can help.
And if you're curious whether your business is appearing across Google AI, ChatGPT, Claude, Perplexity and Grok right now, check here. It’s free:
https://t.co/Evw8cXXicl
When Chat and Cowork land in one product, the UI is the easy part.
The hard part is still who owns judgment when the agent ships the draft, the slides, and the plan.
Tools scale. Apprenticeship still doesn't.
#AI#Hiring#TechNews#Claude