Cursor is an enterprise product disguised as retail. Its revenue never came from subs, people don’t pay API pricing, and enterprises aren’t using grok that’s for sure. It’s a great harness for an enterprise that has to pay API pricing anyway. Just live Devin.
If I was forced to pay API, I would be using Cursor or Devin for coding, not Claude Code or Codex.
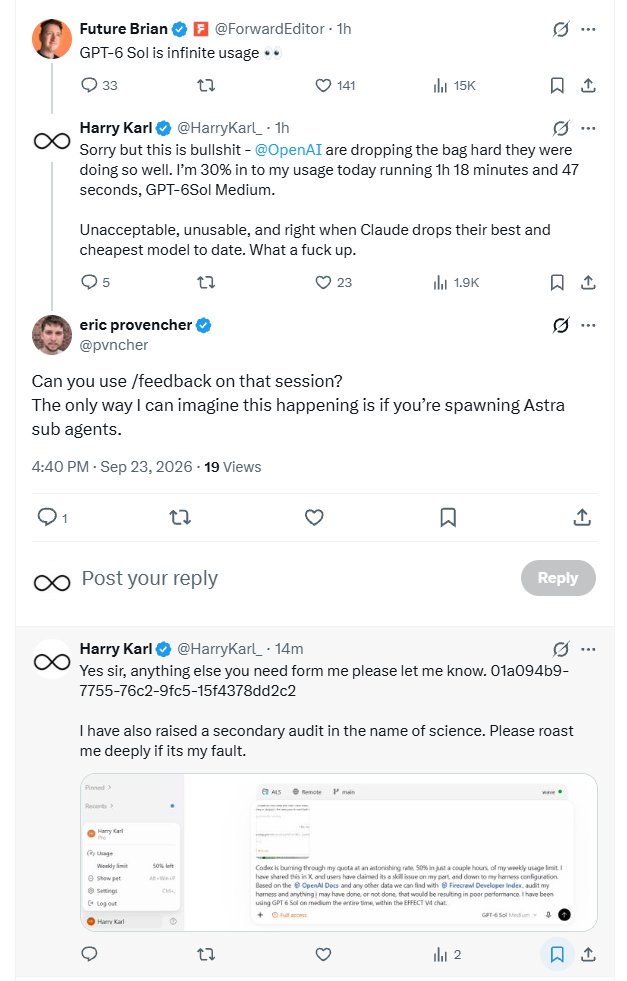
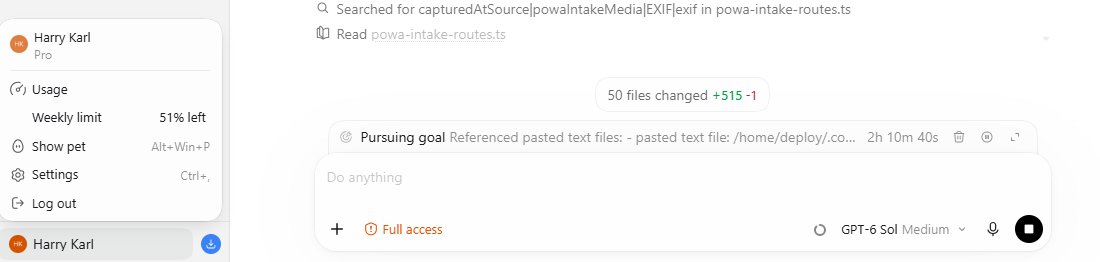
Exploration has occured, and i can confirm @OpenAI@pvncher are innocent. With my goal prompt, 4 terminals were launched with GPT-6-Astra XHigh, to take on the work.
I have deleted the original post to reduce its exposure since this is a popular account, and take back my comments. I will report back on real usage from what i have left.
@pvncher@ForwardEditor@OpenAI Yes sir, anything else you need form me please let me know. 01a094b9-7755-76c2-9fc5-15f4378dd2c2
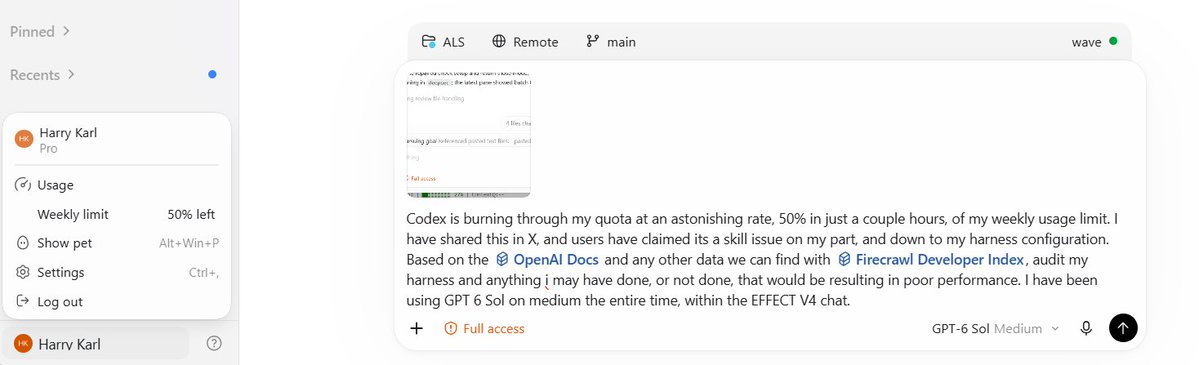
I have also raised a secondary audit in the name of science. Please roast me deeply if its my fault.
@kompilat@ForwardEditor@OpenAI I haven’t made any adjustments to the codex harness - out of the box, therefore, it sucks ass. It’s not my responsibility to load up a default product and be penalised for using it how they designed. 18,000 tests is not complex, it doesn’t require token spend to run scripts pal.
Yeah i hear that every time, theres always a bug. I didnt pay 200 dollars for bugs. I think people are forgetting th elunacy of these costs - never before AI have we ever spent 200 dollars as developers on a personal subscription, never mind multiple. "Subsidised" tokens is a psyop.
@ForwardEditor@thimorrowr@OpenAI Thats fantastic but does your task have zero complexity? Is your Codex harness behaving differently? Either way, this is not what you need from a 'frontier' model or harness.
@thimorrowr@ForwardEditor@OpenAI 20x, see above ^
Even on 5x it would be unacceptible. There is zero use case for any AI model that runs out of use in just a few hours, fo any large amount of money. The token pull seams to be in effect. Resets are ot the answer, they wont last forever.
@mxstbr@rauchg Depends how difficult you can make a specific task. NextJS coding could just be solved - general benchmarks can be made more complex than a specific task.
@higgsfield is the most predatory SaaS I have used in a long time. It’s like logging in to a casino, they slap you in the face with fake promos “just for you”. Should have a gambling license at this point. Free prompts literally take a life time to make you feel you must upgrade for faster generations. Wild.
Pray to the lord above it solves Opus5 slop and someone at Anthropic actually daily ran the model this time.
If they so insist on 50% of our quote falling back to a supporting model, that model better fucking work.