Parsing PDFs is such a pain that most devs would try to avoid it if there's an alternative. @HelloRAG_ai knows the pain and has firsthand experience with the challenges, aiming to provide clean, well-structured, and machine-readable data to enterprises.
🔗 https://t.co/YixyflH6Fz
Key Features @HelloRAG_ai:
✅ High Accuracy: Combining LLMs, vision models and sophisticated algorithms, @HelloRAG_ai identifies and breaks PDFs' objects into sections and parses each based on the content type. 🔍
✅ JSON Outputs: All txt, img and tables within docs will get structurally annotated in JSON and standard HTML with concise summaries, facilitating the downstream retrieval process. 📊
✅ Integration Ready: @HelloRAG_ai offers open-source connectors for popular frameworks like LlamaIndex, enabling easy integration into your LLM workflow. Documentation is also provided to help devs create connectors for other pipelines, ensuring a seamless fit into any tech environment. 🚀
💫 Whether you’re dealing with financial reports, academic papers, or business documents, @HelloRAG_ai can help you handle the diversity and complexity of any docs. Experience the ease of data preprocessing with https://t.co/VA3fy1uAWO today!
#AI #PDFParsing #RAG #LLM #ETLforLLM #DataScience #FinancialStatements #ETLPipelines
📊 Stuck on the first step of building your RAG stacks and overwhelmed by large volumes of unstructured data? 📂
🔎 Try HelloRAG, a dead-simple ETL platform that accurately gets your multi-modal data ready for LLMs at scale in four steps. 🔗 https://t.co/6gGyEKqz1B
✅ All you need to do is:
1️⃣ Create a workspace and upload your files.
2️⃣ Click 'Start' to parse the selected file.
3️⃣ Review, edit, and annotate the extracted data in the editable spreadsheet and text editor.
4️⃣ Export & download the RAG-ready data, with text, images, and html structurally annotated in JSON.
🌐 After using HelloRAG's data preprocessing, you can integrate the LLM-friendly data into downstream pipelines and build real-world LLM applications connected to domain-specific knowledge.
#NoCode #ETL #DataTransformation #AI #MachineLearning #HelloRAG #DataScience #PDFParsing #RAG
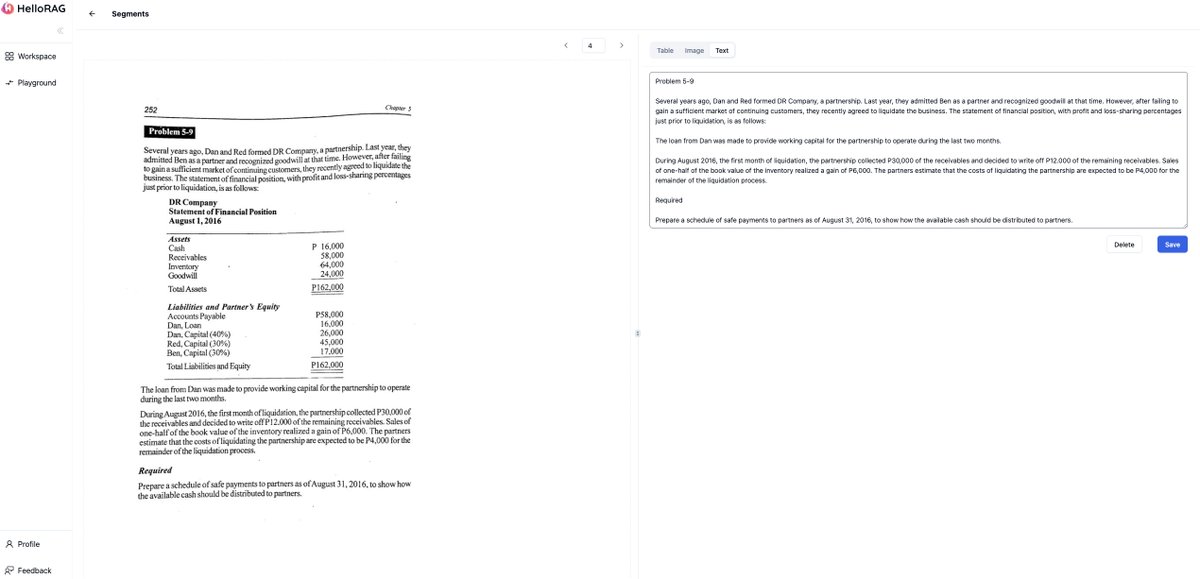
🔥 Check out the following images and see how @HelloRAG_ai accurately extracts data from scanned documents, preserving the logic structure while filtering out noise data like the text in footer margins.
📄 Struggling with parsing scanned files? In cases of low-quality scans or complex layouts with tables, graphs, and other visual elements, it is difficult to distinguish between data fields and identify the logical structure of the content, resulting in inaccurate data extraction.
💼 Financial sectors, for instance, are in high demand for data extraction from financial statements, notorious for their lengthy nature with complex structures like tables and graphs and even existing in hundreds of pages of scanned files. Retrieving key values from these docs can be a time-consuming and non-scalable task for many enterprises. 🤯
✅ For both scanned documents and native PDFs, @HelloRAG_ai takes over the process, transforming unstructured data into clean, well-structured JSON files and standard HTML. This saves your team valuable time for more in-depth analysis tasks. ⏱️
#AI #PDFParsing #RAG #LLM #ETLforLLM #DataScience #FinancialStatements #ETLPipelines
💪 Supercharge your RAG system’s ability to extract the most relevant information from complex datasets with HelloRAG! Our high-quality data prep enables your LLMs to effortlessly access domain-specific knowledge.
🚀 Automation & Simplicity: Featuring a no-code interface, HelloRAG cuts off all setup hassles. Just upload and go!
🚀 Multimodal Support: Upload your complex datasets, whether they’re text, images, or audio, and get well-annotated and structured JSON files.
⏱️ Take advantage of our FREE trial and enhance your LLM projects now! 🔗 https://t.co/YixyflH6Fz
🔎 HelloRAG is the ultimate data preprocessing tool for LLM practitioners who want to spend less time on data ingestion and more on the core functionality of LLM applications.
#AI #HelloRAG #RAG #DataLoading #PDFsProcessing #VectorDatabase #ETLPipeline #ETLforLLMs #DataPreprocessing #PDF #DataScience
🌟 HelloRAG is an enterprise-grade ETL platform that transforms repetitive, labor-intensive data pre-processing tasks into simple, effortless, and streamlined workflows.
✅ Multimodal Processing: HelloRAG ensures an easy transformation of texts, tables, formulas, figures, audios, and videos for downstream retrieval and generation. 🤖
✅ Scalable Human-in-the-Loop: Our preview interface provides full control and transparent insight into every detail of the ingested data for LLMs. 📈
✨ Start your free trial with HelloRAG today! 🔗 https://t.co/YixyflH6Fz
🌐Get high-quality data for your RAG system and breeze through the complexity of data formats when building your LLM applications.
#AI #HelloRAG #RAG #DataLoading #PDFsProcessing #VectorDatabase #ETLPipeline #ETLforLLMs #DataPreprocessing #PDF #DataScience #FinancialReport
📄 Thus, for more reliable responses from LLM's documents reading, specialized documents pre-processing tools are still enssential before analyzing them with GPT-4o.
📊 To answer this, we did a test by feeding the SOTA model a raw financial report PDF with intricate tables spanning across columns and requesting it to identify specific figures in this report. The correct answers have been highlighted in yellow in the first image.
🧠 Given the complex formatting and embedded elements in PDFs, it remains a bottleneck for GPT-4o to directly handle such documents, as shown in the second image.
🔎 The image below shows a remarkable improvement in GPT-4o's response accuracy after using @HelloRAG_ai 's data pre-processing, which adeptly converts table information from complex docs into clean and well-structured formats like standard HTML and JSON.
👀 Can you fully rely on GPT-4o's document understanding with its enhanced vision processing capabilities? Are data pre-processing tools like @HelloRAG_ai still necessary for LLM's multimodal document understanding? 🤯
#AI#HelloRAG#RAG#DataLoading#PDFsProcessing #VectorDatabase #ETLPipeline #ETLforLLMs #DataPreprocessing #PDF #DataScience #FinancialReport
🔍 How do you prepare your data for RAG pipelines?
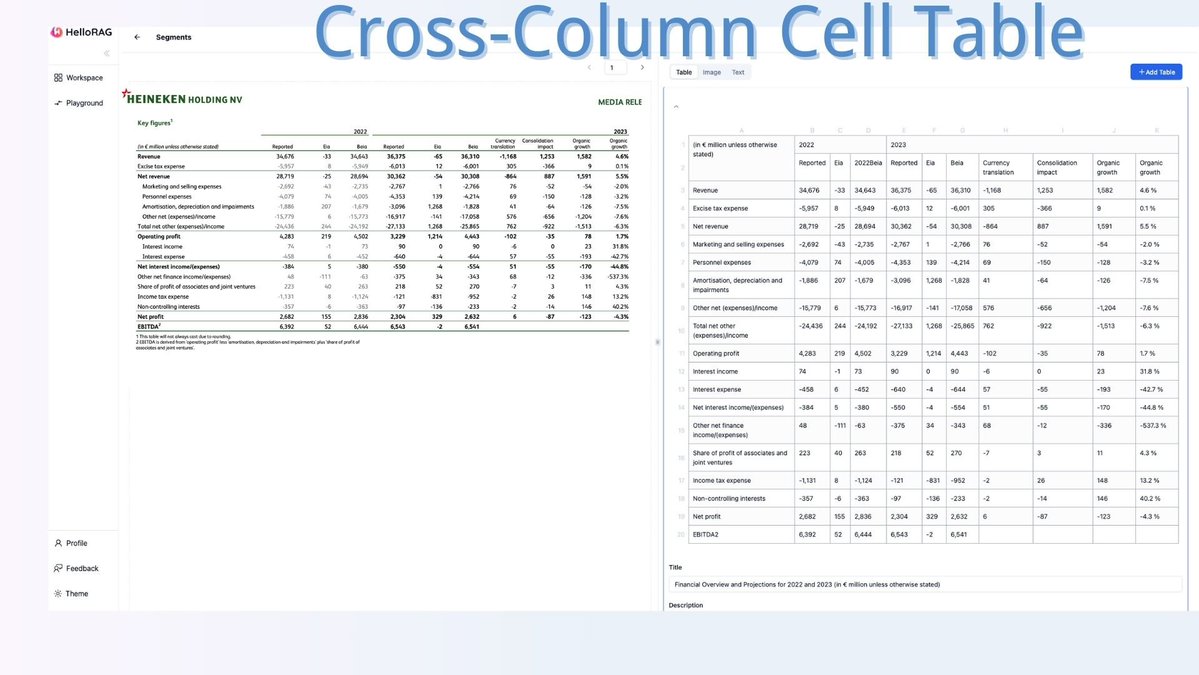
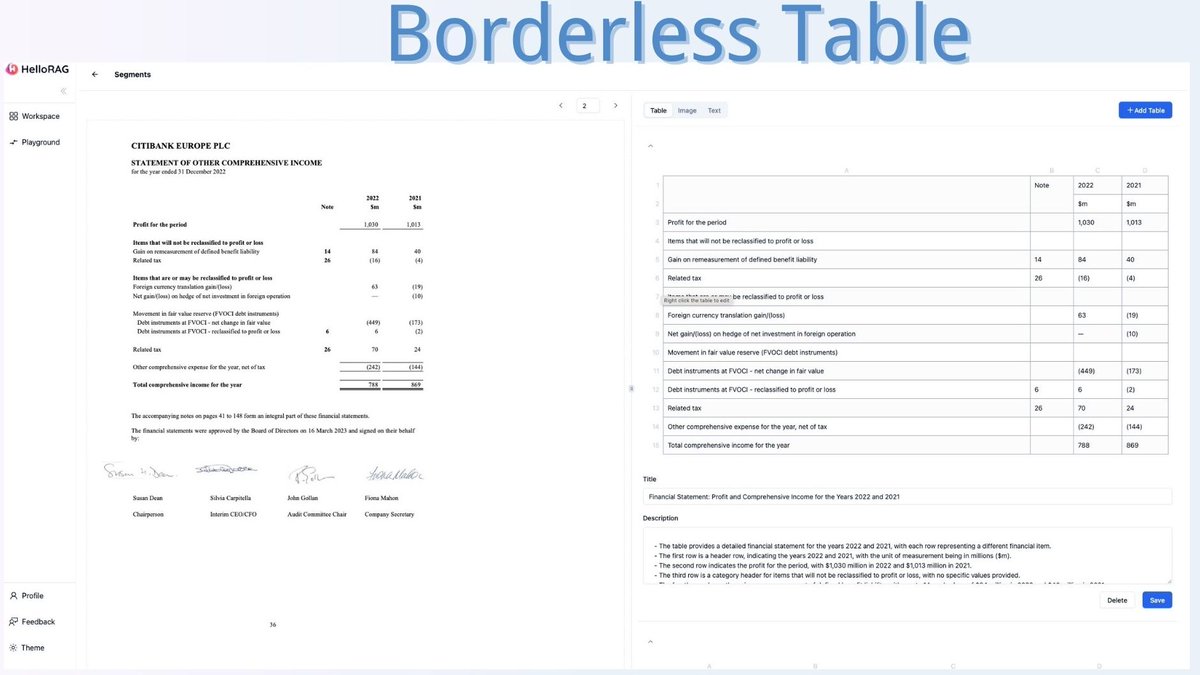
📄 Table extraction is often a significant pain point in data preprocessing, particularly when dealing with financial reports that contain complex table structures like cells spanning multiple columns or borderless designs. Maintaining the structure of such tables is typically difficult, leading to numerous hours wasted on data ingestion.
➡️ @HelloRAG_ai offers a convenient one-stop interface that accurately extracts complex tables from docs. Whether you’re dealing with borderless tables, cross-column cell tables, or tables on multi-column page, @HelloRAG_ai can accurately extract these elements, preserve headers as needed, and store them in JSON files. We also provide concise summaries for each table to ease retrieval later on.
👀 Take a look at the screenshots below to see the results of HelloRAG's complex table extractions and discover how @HelloRAG_ai can streamline your data preprocessing tasks. 🚀
#AI #HelloRAG #RAG #DataLoading #PDFsProcessing #VectorDatabase #ETLPipeline #ETLforLLMs #DataPreprocessing #PDF #DataScience #FinancialReport
🤖 When building a RAG system, the quality of RAG's responses heavily depends on the quality of the retrieved data, underscoring the need for reliable data preprocessing which ensures that the input data is clean, structured, and most importantly, readable for LLMs.
📊 However, with large volumes of data containing various objects like tables and figures from diverse sources such as PDFs, PowerPoint, Word and more, how to represent these unstructured data in a way your RAG system can understand (e.g., JSON) remains a challenge for many developers.
🧰 @HelloRAG_ai provides a no-code and easy-to-use interface that enables you to smoothly scale up your efforts in parsing, extracting, and transforming data, connecting your RAG system with diverse data sources.
🎯 Once your datasets are processed, you can connect the HelloRAG parsed outputs (.zip file) to your LlamaIndex RAG workflow with the provided connector on our GitHub(🔗 https://t.co/IMt23Ehn05). We also offer relevant docs for you to build custom connectors for other RAG pipelines.
✅ Start your free trial today and prepare the high-quality data for your RAG system with @HelloRAG_ai! 🔗https://t.co/YixyflH6Fz
#AI #HelloRAG #RAG #DataLoading #PDFsProcessing #VectorDatabase #ETLPipeline #ETLforLLMs #DataPreprocessing #PDF
🚀 A standout feature of HelloRAG is its ability to detect the layouts of uploaded PDFs, including identifying the correct text order within multi-column pages.
🔗 https://t.co/YixyflH6Fz
✅ For PDFs with multi-column layouts in which text is often misordered by LLMs, HelloRAG can preserve the logical structure of the content while ignoring text within footer margins.
🔎 Check out the excellent performance of HelloRAG below in accurately detecting text from each column. With HelloRAG, you'll get your unstructured data structurally organized in JSON format with annotations, ready for downstream RAG stages.
#AI #HelloRAG #RAG #DataLoading #PDFsProcessing #VectorDatabase #ETLPipeline #ETLforLLMs #DataPreprocessing
@svpino Can't wait for the session! Check out HelloRAG if you don't want to deal with the challenging task of data loading in RAG due to data being sorted in many different file types and data formats.
👋 Say goodbye to tedious data preprocessing tasks with HelloRAG! 🔗 https://t.co/YixyflGyQ1
🔎 Most enterprises PDFs contain various layouts, such as multi-column pages, images, and tables, easily readable by humans but complex for LLMs. How to transform this unstructured data into a format that language models can access and utilize remains a time-consuming task for many devs building RAG systems.
✅ This is where HelloRAG comes in handy, offering a no-code solution that's all set-up for immediate use.
💪 Key features:
1️⃣ Layout Detection: It identifies and breaks documents' layouts into sections such as tables, images, and text and parses each based on the content type.
2️⃣ Advanced Extraction: Combining vision models, LLMs, and proprietary algorithms, HelloRAG accurately extracts and structurally annotates data into JSON and standard HTML formats.
3️⃣ Data Enrichment : It also provides concise summaries for tables and images, enhancing the quality of the output.
4️⃣ Editable Preview: The processed data is displayed in an editable preview interface, allowing for easy review and modifications.
🙌 Start your free trial today and get all your multimodal data LLM-friendly, enabling your LLMs to access a broad range of information!
🔗 https://t.co/YixyflGyQ1
#AI #HelloRAG #RAG #DataLoading #PDFsProcessing #VectorDatabase #ETLPipeline #ETLforLLMs #DataPreprocessing
📢 Exciting news! We just released the free trial version on our website.
🔥 Hit the link below to give it a try! And you will unlock:
✅ Accurate data extraction, up to 10 non-scanned PDFs, each with less than 20 pages;
✅ Secure data handling & storage;
✅ AI-assisted parsing & annotation without vision mode;
✅ Layout based indexing;
🆓 Get started with the free trial today and effortlessly prepare your multi-modal data for RAG stacks like never before.
🔗 https://t.co/YixyflH6Fz
#AI #HelloRAG #RAG #DataLoading #PDFsProcessing #VectorDatabase #ETLPipeline #ETLforLLMs #DataPreprocessing
🚀 Get Started Quickly with HelloRAG:
HelloRAG streamlines the integration of unstructured and semi-structured data from enterprise databases into your custom RAG stacks in just five easy steps:
1️⃣ Create a workspace and upload your PDFs.
2️⃣ Click the "Start" button to parse your PDFs.
3️⃣ Review the parsed content using our editable spreadsheet and text editor.
4️⃣ Export the data and check your email to download the RAG-ready files.
5️⃣ Integrate your data with LlamaIndex or other RAG pipelines.
🔎 For detailed instructions on connecting with LlamaIndex using the HelloRAG Llama Pack, visit our GitHub. 🔗 https://t.co/IMt23Ehn05
📈 Save time on data prep with HelloRAG and focus more on downstream RAG development. 🔗 https://t.co/YixyflH6Fz
#AI #HelloRAG #RAG #ProductHunt #DataLoading #PDFsProcessing #VectorDatabase #ETLPipeline #ETLforLLMs #DataPreprocessing
🎯 How HelloRAG Ensures Data Quality Assurance for RAG:
✅ Combines vision models and LLMs for accurate text, and visual extraction.
✅ Proprietary algorithms extract, and annotate data with high precision.
✅ Supports human-in-the-loop review and editing with its intuitive interface.
✅ Scalable architecture handles high document volumes efficiently.
👏 Try HelloRAG for more efficient data ingestion. Join the waitlist now 🔗 https://t.co/YixyflH6Fz
💬 Or, share your thoughts with us in our Slack group! 🔗 https://t.co/8W2ARHLOjV
#AI #HelloRAG #RAG #ProductHunt #DataLoading #PDFsProcessing #VectorDatabase #ETLPipeline #ETLforLLMs #DataPreprocessing