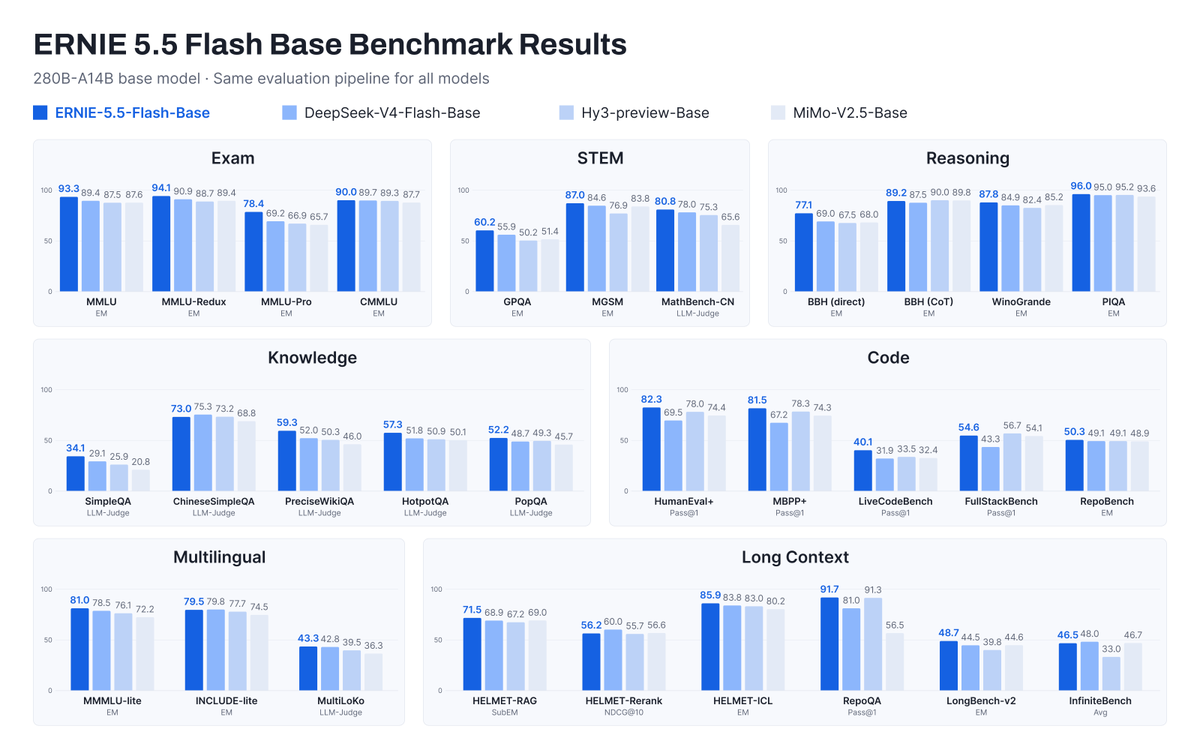
Excited to introduce ERNIE 5.5 Flash Base, my first release since joining @Baidu_Inc !
An open-sourced 280B MoE model with just 14B active parameters, pretrained on 33.5T tokens. It delivers strong performance across reasoning, coding, and long-context benchmarks, with support for up to 1M context.
Huge respect and thanks to the incredible team behind this — outstanding work!
Post-training is already underway, and I can't wait to bring it to you soon.
And this is just the beginning — more exciting technical developments are on the way. Stay tuned!
https://t.co/7DBNYNwf81
FlashMask: Faster, More Flexible Attention for Long-Context Training
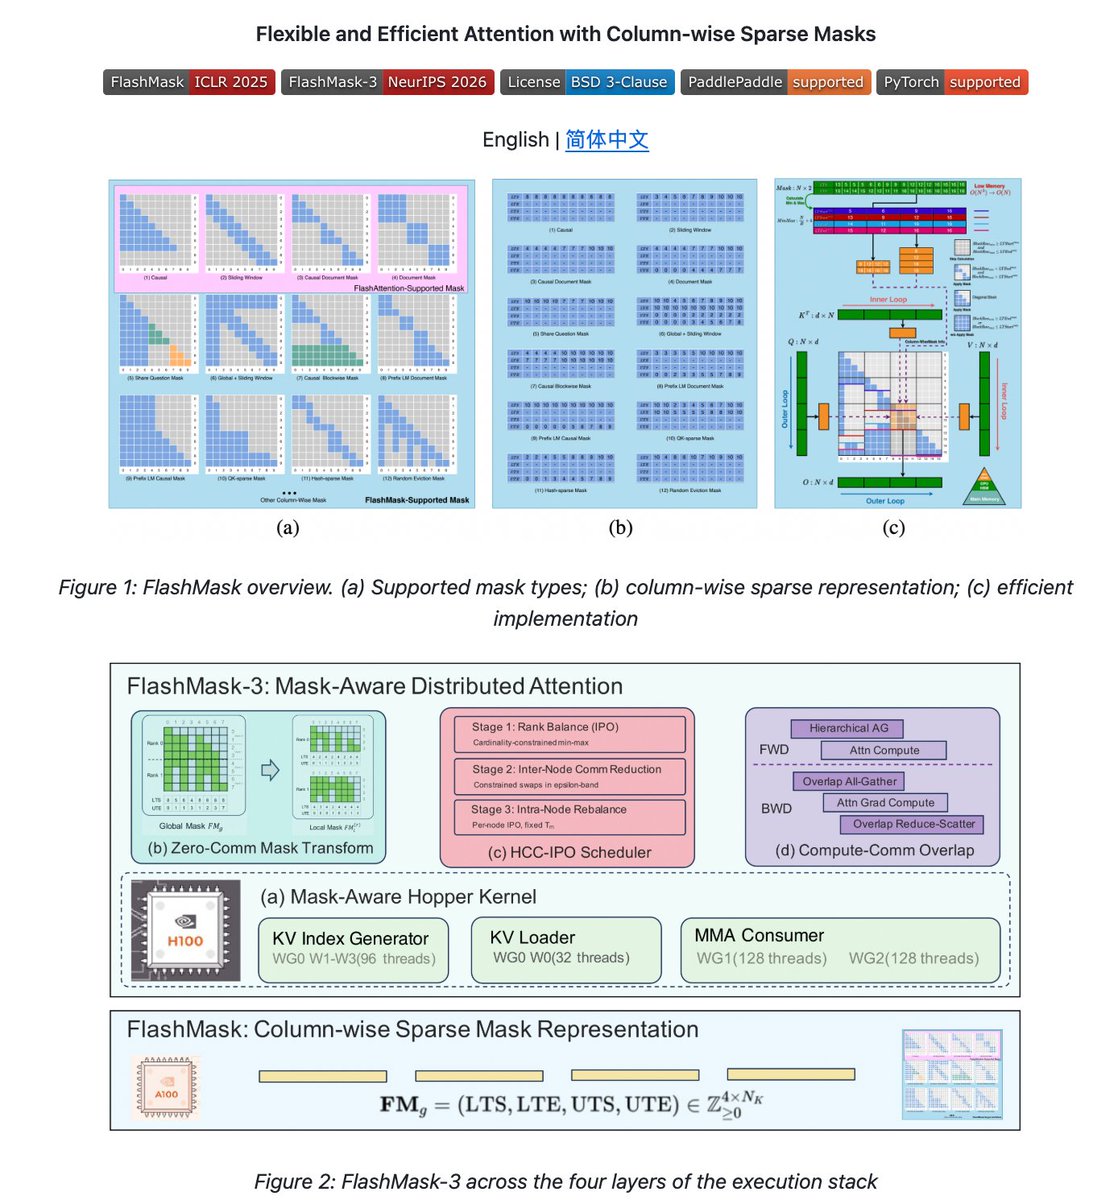
We’re excited to share FlashMask, a high-performance Attention library for LLM training!
🔸 Flexible support for complex attention masks
🔸 Up to 1.55× faster than FlashAttention-4
🔸 Efficient context parallelism with load balancing and computation–communication overlap
🔸 PaddlePaddle & PyTorch support via CuTe DSL
🔸 SM90 & SM100 support
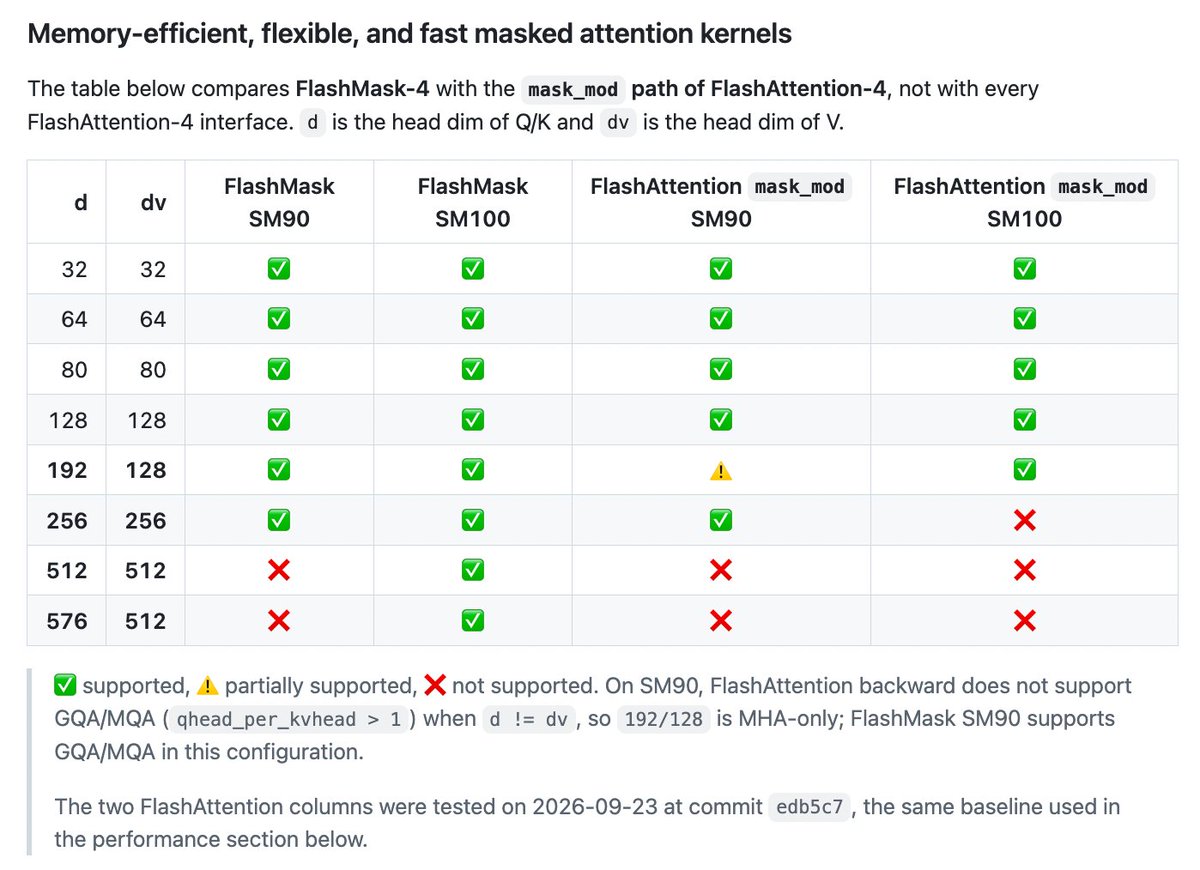
🔸 Large head dimensions: 192/128, 256/256, 512/512, 576/512
FlashMask-3 is accepted at NeurIPS 2026!
🌐 GitHub: https://t.co/IvUYC2KabJ
💻 Paper: https://t.co/rNJyeBKMqZ
🤗 Project: https://t.co/eU4rjb4uXz
Wave Summit 2025 kicks off tomorrow with exciting updates on ERNIE, PaddlePaddle, Baidu Comate, and more. But that’s not all—for the first time ever, the team behind ERNIE will go live right after to share more on our upgraded model. Tune in on X or YouTube to be the first to see what’s new!