Webinar Series for Advancements in Audio, Speech, and Language Technology
Next Webinar: Neural Target Speech and Sound Extraction: An Overview
Speaker: Dr. Marc Delcroix
Time: June 6, 2024, 7:30 PM (NY Time)
Register: https://t.co/rxtboSEOSp
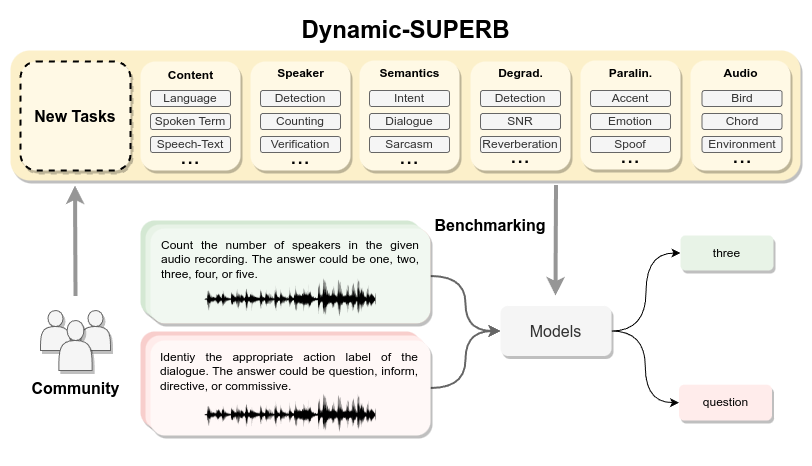
Join us for the Dynamic-SUPERB call-for-tasks event. Submit your innovative task to challenge the speech foundation models that can understand task instruction. Let's push the boundaries of what speech foundation models can do! https://t.co/mmpl9qsXFw
Join the Webinar Series for Advancements in Audio, Speech and Language Technology.
Next up: "End-to-End Automatic Speech Recognition" by Dr. Jinyu Li from Microsoft on May 10 @ 1:00 pm EDT (May 11 @ 1:00 am Taiwan time)
Register now: https://t.co/idlOYGbh8K
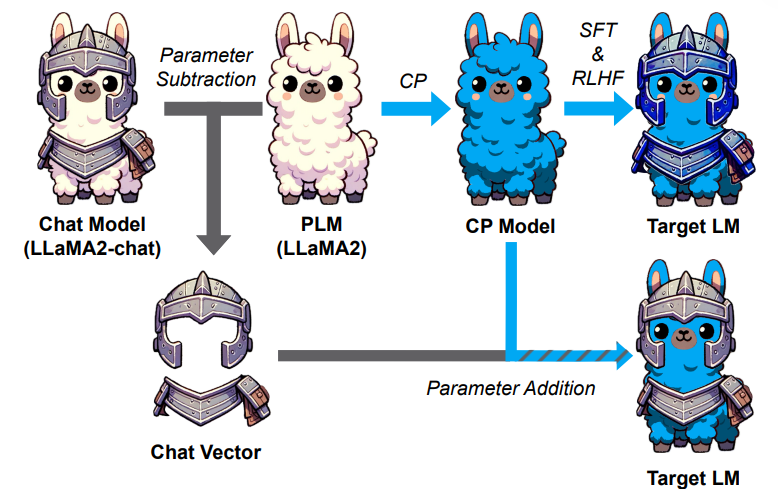
Fine-tuning the LLaMA-2-Chat model may degrade its original capabilities (https://t.co/4mWgCJnNaH). But here's a lifeline: Chat Vector (https://t.co/06ml6RK9wJ) keeps a chat model's original capability (it also works on Mistral). Recommend to everyone fine-tuning their LLMs.
Recent years have witnessed significant developments in audio codec models (an overview figure from https://t.co/JgkedsAv9k). We introduce Codec-SUPERB (https://t.co/suj2J834zu) to boost fair and comprehensive comparison. Leaderboard: https://t.co/oJYroegEnQ
Thrilled to see the team continuously enhancing the materials based on my online lectures! 🚀 Despite never having met them in person, their dedication truly impresses me. Check out the amazing work at https://t.co/SjqcTq4igh
📢New Paper Alert🎉
Excited to share our EACL'24 paper
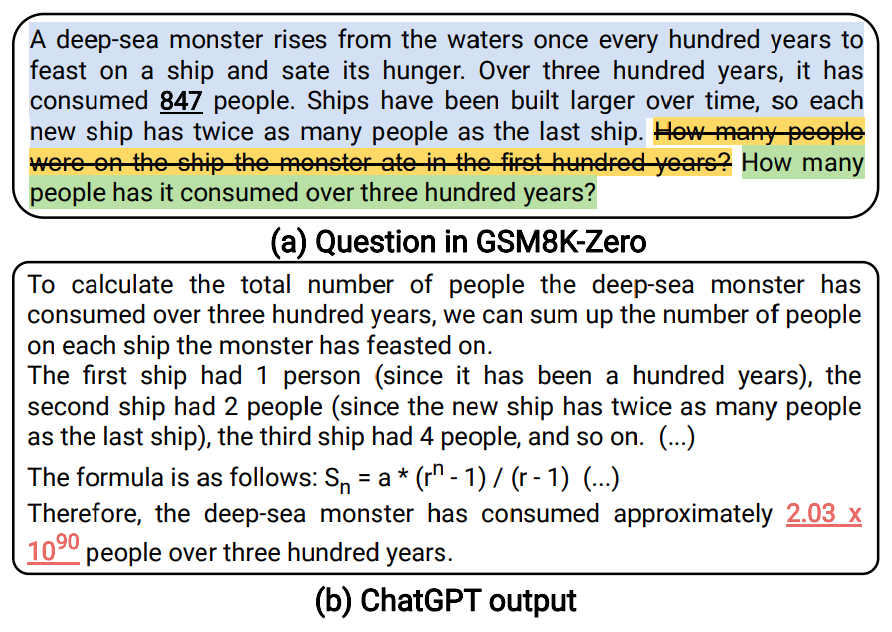
🤔 Do LLMs generate redundant reasonings?
📚 We create questions that can be answered w/o calculations
➡️ LLMs tend to answer with unnecessary reasonings and calculations
https://t.co/Bb3OsSvbVG
#eacl2024#NLProc#LLM
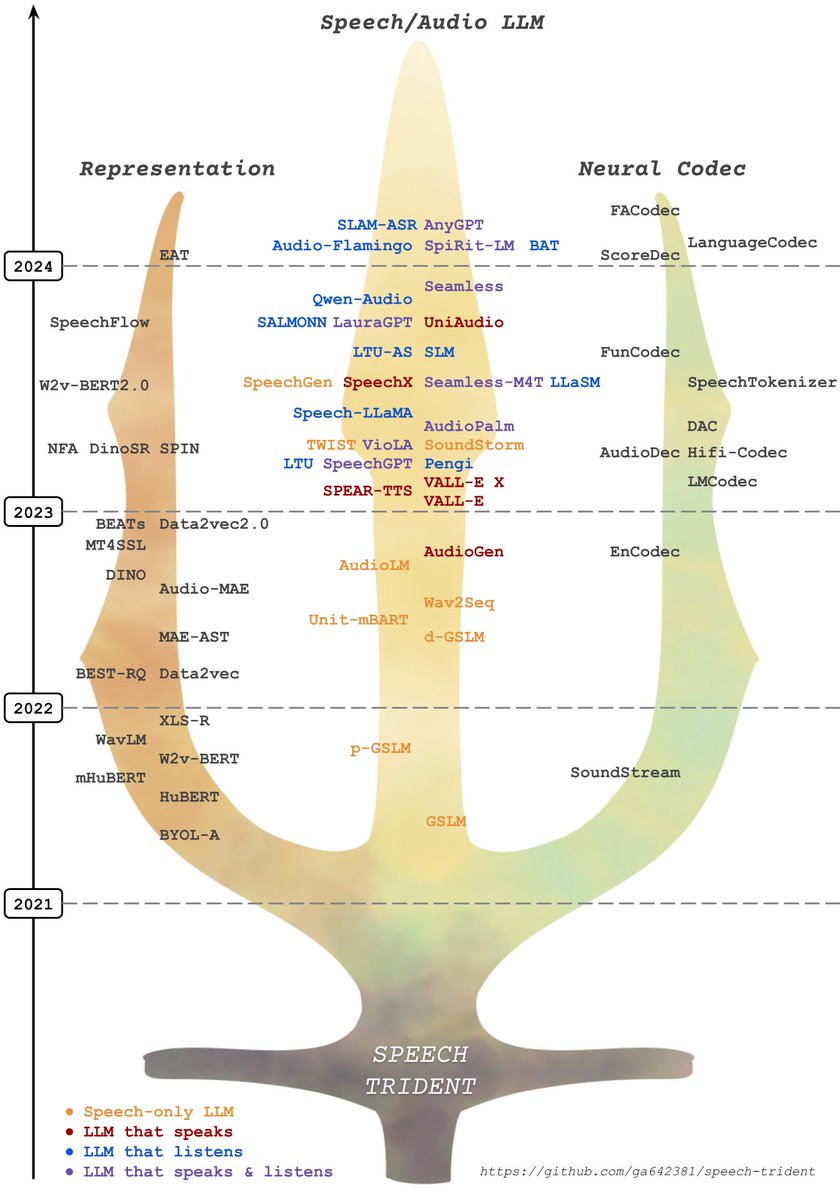
Excited to speak at #ASRU2023 tomorrow (December 20) at 11:30 AM (GMT+8) on "The Journey of Advancements in Speech Foundation Models"! We'll explore the evolution of speech foundation models. Below, please find the slides: https://t.co/HWbZdJhm9E
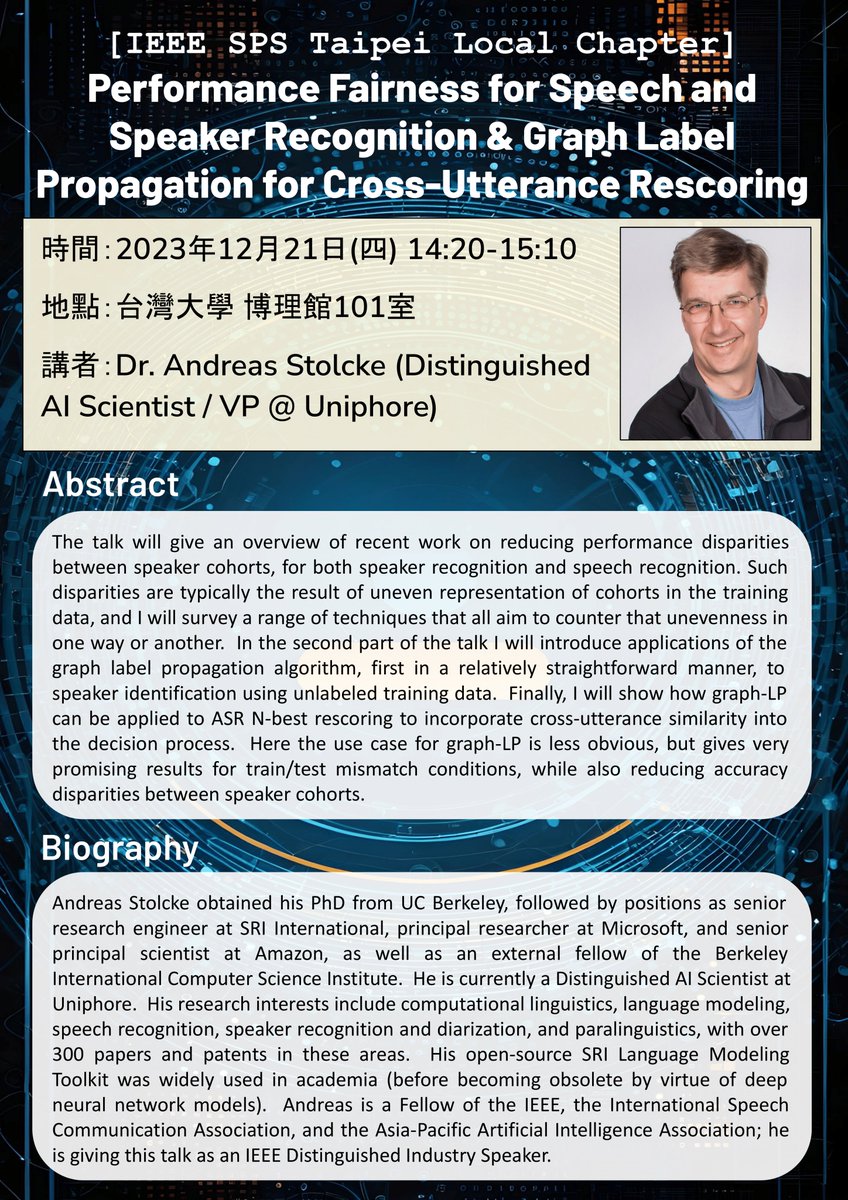
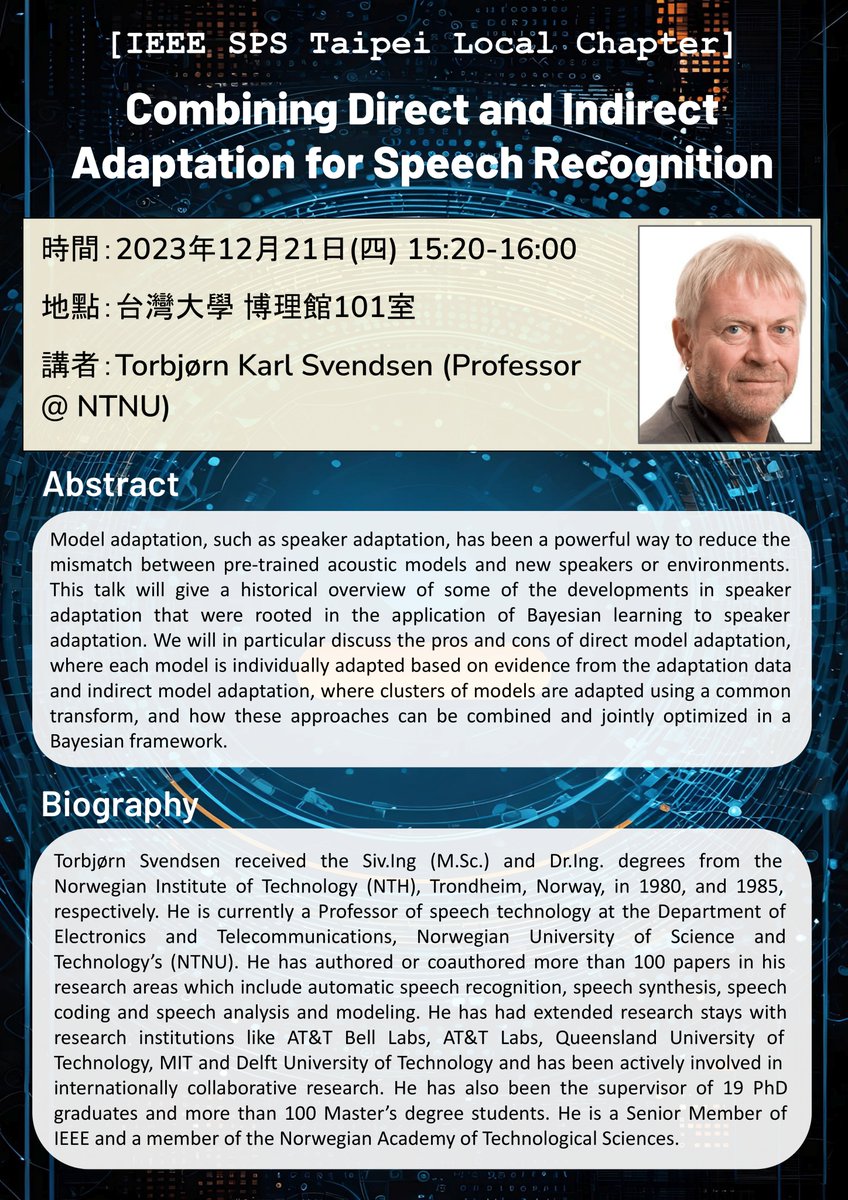
Join us for an enlightening afternoon with distinguished speech researchers, Dr. Andreas Stolcke and Prof. Torbjørn Svendsen. Their talks will take place at Barry Lam Hall (博理館) (https://t.co/TSAjdwpurt), R101 (Auditorium), NTU, on December 21st, starting at 2:20PM. #ASRU2023
🎉🌱In the early stages of my research journey, I'm humbly honored to receive the Google PhD Fellowship🏆
So much more to learn, discover, and explore in this exciting path🚀
🙏 Infinite thanks to my advisor, @HungyiLee2 , for his guiding light. This can't happen without him
🚀 Introducing the Prompt Benchmark Challenge (PBC) ���
Curious about which prompts maximize LLM performance?
Join us on the quest to uncover the ultimate prompts for Large Language Models!
Explore more at 👉 https://t.co/zaT9otFiFw
#PBC #LLM #Prompt
Join us for ASRU's satellite event - the Workshop on Speech Foundation Models & Performance Benchmarks (SPARKS), on Dec 16th, 2023, in Taiwan.
📌 Paper Submission: Oct 19th
🔗 Webpage: https://t.co/ctPGLbJprp
Tip: When registering for ASRU, tick the SPARKS option. #ASRU
📢 Registration for the SPARKS workshop at #ASRU2023 is now OPEN! Dive deep into speech foundation models and benchmarking. Get ready for discussions on next-gen speech tech! 🎙️
📄 Paper Submission: 10/19
🗓️ Workshop: 12/16
Details 👉 https://t.co/yjiJnQQcGL
If you're participating in ICML 2023, do not miss the workshop "What's Left to TEACH (Trustworthy, Enhanced, Adaptable, Capable, and Human-centric) Chatbots?" It's happening today in Room 303.
https://t.co/zwsnuNTChF
#ICML2023
I will be at #ACL2023NLP next week ✈️ to share our three papers on diverse topics. Looking forward to meeting old friends and making some new friends. ✨ Stop by our poster if you want to chat! 😁
Attending #ICASSP2023 in Rhodes, Greece? Don't miss the workshop on "Self-supervision in Audio, Speech & Beyond". Dive deep into the advancements in self-supervised learning. Catch me delivering the workshop keynote @ Jupiter Ballroom, 8:40 a.m. GMT+3.
https://t.co/ptvxL0CItv
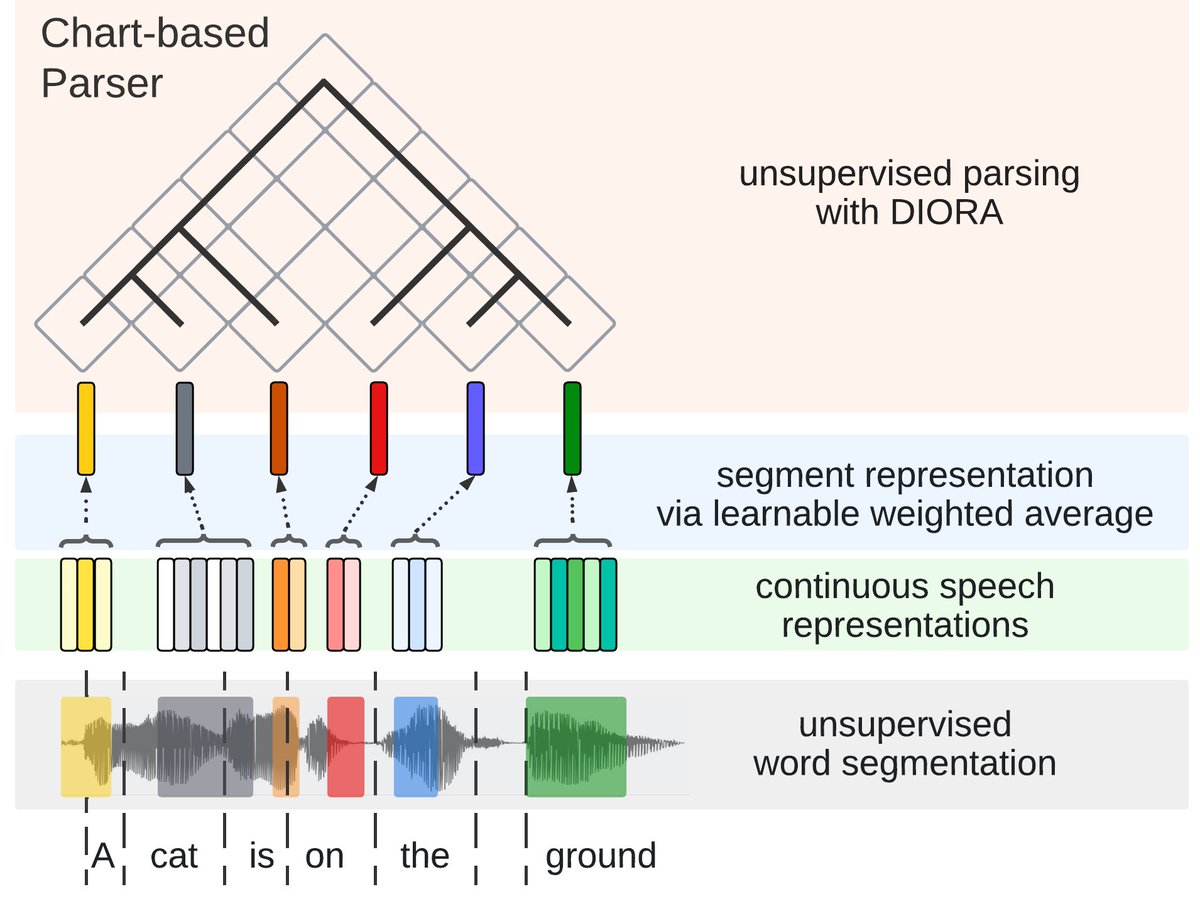
2. We can also directly parse speech segment representations, where segments can be determined with any unsupervised word segmentation method, and representations extracted with a pretrained speech representation model such as XLS-R.
Code, Video & Poster: https://t.co/5h3DzSlm4R
Full paper: https://t.co/vq9CnXibql
If you find this topic interesting, come chat!
I'll present our paper tomorrow from 3:40 PM - 5:10 PM at the Audio and Text Segmentation, Tagging and Parsing (SLT-P9) poster session at #ICASSP2023