1. We will keep accelerating. Our AI efforts are only 3 years old, vs 6 and 10 years old for Anthropic and OpenAI. If our second derivative remains strong, SpaceX will reach pole position in about 6 months.
2. Once you far exceed the caliber of intelligence needed for a class of tasks, additional intelligence is pointless. You don’t need (and it would be cruel to put) Newton-level intelligence in your toaster!
3. Hardware is hard. Bringing massive compute online rapidly is incredibly difficult. SpaceX has demonstrated exceptional ability in this regard and will only get better.
MiMo-V3 is getting a new architecture. The core of it, HySparse2, is out today.
Less prefill, a smaller KV cache, better long-context retrieval—and we got all three at once.
Compared with MiMo-V2.6's Hybrid SWA architecture:
• 5.02× lower prefill FLOPs at 1M tokens
• 4.5× smaller KV cache at 1M tokens
• Better MRCRv2 and RULER-v2 scores, plus lower AgentPPL and LongPPL
Why build a new architecture?
Agentic inference is a very different workload. Each round, a short action can return a long observation that needs to be prefilled, while the context keeps growing. That puts prefill cost, KV-cache size, and retrieval accuracy on the critical path at the same time.
HySparse2 tackles all three with two levels of KV sharing:
• KV Bridging: Following YOCO, full-attention layers in the cross-decoder build their K/V from self-decoder hidden states.
• KV Reuse: Within each hybrid block, sparse layers reuse the preceding full-attention layer's KV cache and selection indices.
Two more changes: token-level selection replaces block-level selection, and a forced window of recent tokens replaces the separate SWA branch, so local and global tokens share one KV cache. Since all cross-decoder KV caches now come from the self-decoder, prefill can stop once the self-decoder finishes.
Paper: https://t.co/REeEdd5pL7
Meet the new Kimi Browser Extension, formerly Kimi WebBridge.
From your browser sidebar, you can chat with Kimi to navigate websites, fill out forms, and get things done.
For repetitive tasks, record your steps once and save them as a skill. Kimi can take it from there next time.
Available now on https://t.co/3u29cgYcJQ and the Chrome Web Store.
https://t.co/Gr70utUVak
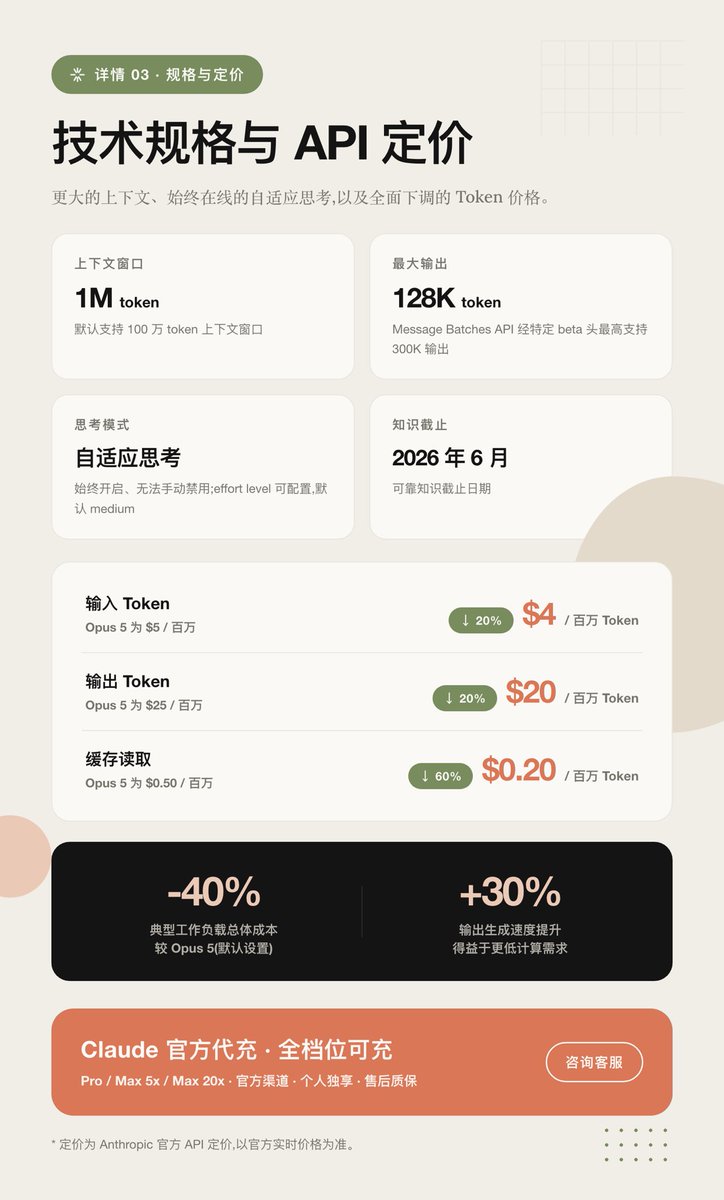
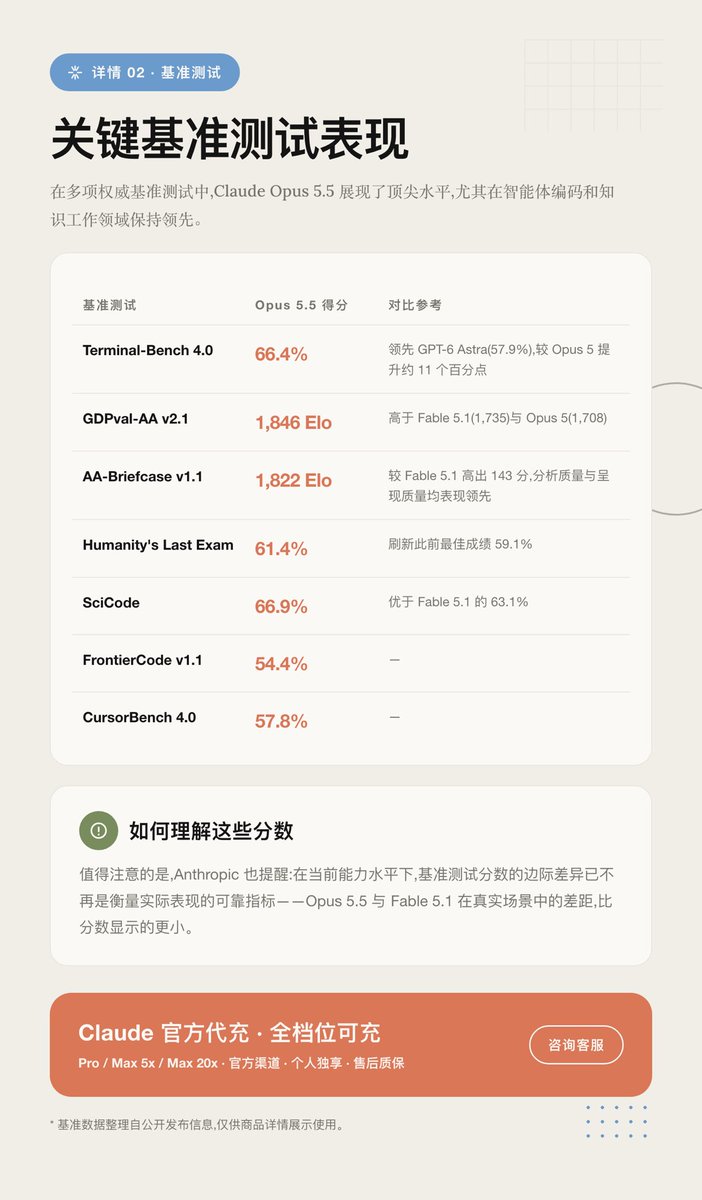
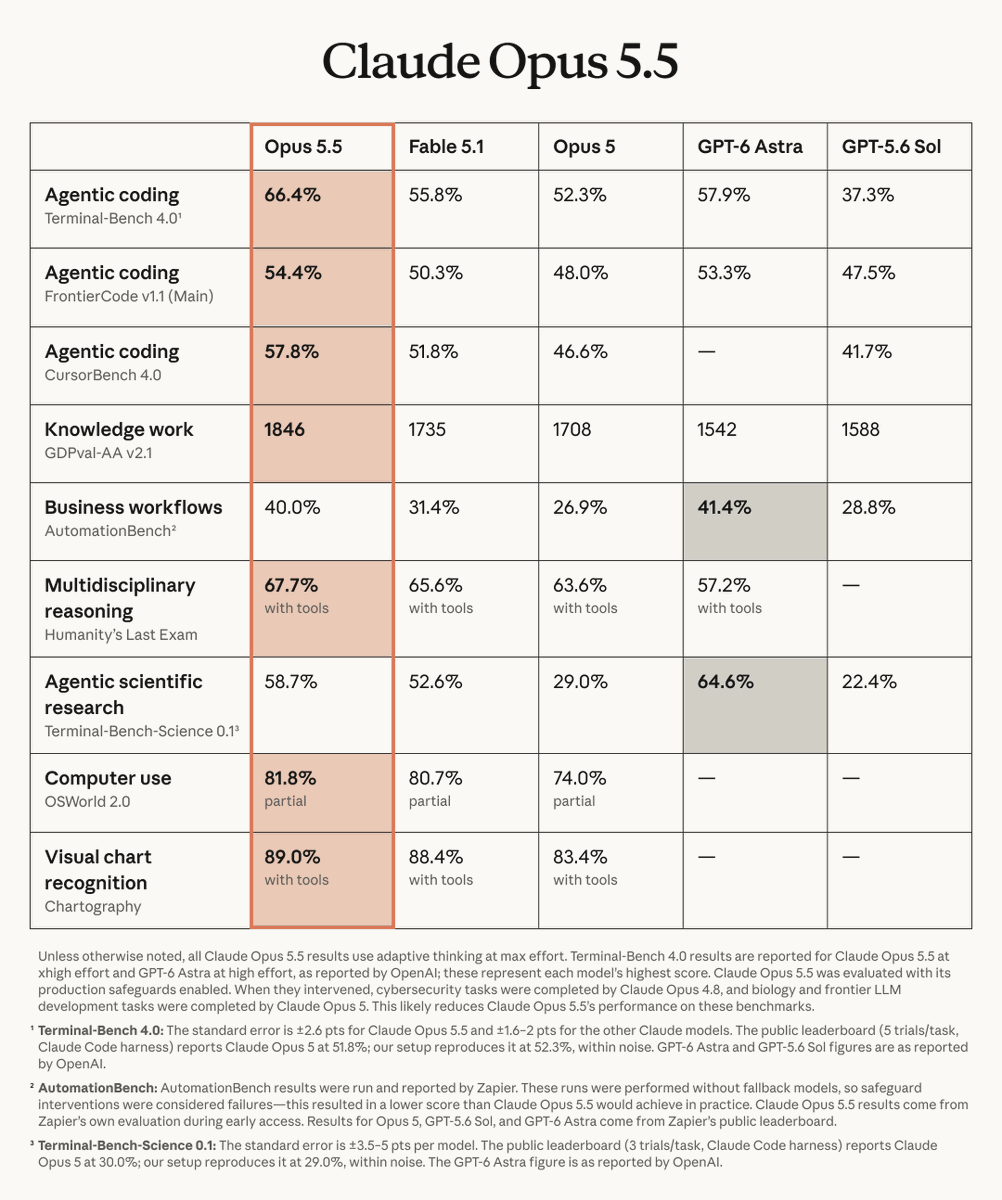
如果你每天都在用 Claude 做重度工作(长上下文编程、复杂 agent 任务、大规模代码迁移/重构、深度知识工作),Pro 经常被限流打断节奏,而 Max 20x 能让你几乎无中断地跑 Opus 5.5 这类顶级模型,把“等额度”的时间全部变成产出,ROI 通常远高于月费本身。