Every tool available to an LLM is provided as part of the system prompt.
Each tool definition contains:
1. Tool name
2. What it does
3. Input arg JSON schema
4. Description of each arg
5. Output format JSON schema
This repeats for every tool and can explode for 10s and 20s of tools. In an agentic AI system, tools can explode to even 100s (alone mcp-atlassian exposes ~70 tools across JIRA and Confluence)
More the tools available, better options for model to work with, which brings better reasoning but **at the cost of invaluable context window**
Found out a smart solution in Claude Agent SDK.
It exposes a tool called ToolSearch https://t.co/rGILA2oUQw. Yes, a Tool of Tools.
Instead of feeding all the tools upfront, just feed the basic ones which are frequently used along with the ToolSearch and let the model reason the available tools and load them dynamically.
I just hate this. That too they should remain testers for 15 days, I also noticed that multiple ids on same device counts as 1 or not all counted.
I would bother beta testing anyones app for security reasons. How do I expect someone else to help me with that 😔
Apple atleast reviews it thoroughly themselves and never asks for beta users.
With Claude as my second mind, I still specify what needs doing, the business logic, and extra validations. basically the plan[.]md
But I’ve started giving up thinking on how to implement it.
Claude implements, I review, and keep saying “this isn’t looking good, do something else” until I’m satisfied.
I’m not sure if this is a bad way.
@Naina_2728 I do the same for 3AM thoughts only about problems to be solved, their solutions, writing blogs.....
More of scratch pad for my brain.
68 items so far, hardly 3-4 done.
I tend to forget thoughts. Hence started writing as raw as possible. Agree. It's a 10/10 habit.
Tracking my expenses has been the pain. Here's how I solved it with 0 cost and all local. https://t.co/evaCQ8SHDw
It's been wonderfully helpful.
Please give it a read.
People are blaming Institute.
Before I start, I don’t know what was the conversation by institute but
No institute won’t let anyone leave normally who cheated. If taken casually, students will make it a norm.
Merchant's costs will soon be collected from the users.
No one can stop a local merchant saying
1. Either pay Rs. 1000 bill + Rs. 2
2. Or pay in cash
It's pretty similar to what Zomato does. I pay the additional tax on the "platform fees" collected by them.
I think MDR on UPI was probably inevitable at some point, especially given how widespread UPI adoption has become. It could also lead to more competition, instead of just three apps accounting for more than 95% of the market.
That being said, there are some use cases, like investing and broking, where the proposed MDR structure doesn’t really make sense.
The problem with broking is that there is no guarantee that money transferred to a broker will actually result in a transaction.
As brokers, we can’t force a customer to trade after transferring money. And if we can’t pass the UPI charge on to the customer, there is essentially no limit to the cost a customer can impose on a broker without generating any revenue.
Just as an example, 10,000 customers could each make 50 UPI transfers of ₹2 lakh in a month without executing a single trade. At the proposed MDR, this could potentially cost the broker around ₹2 crore, without generating any business.
What makes this even more challenging is quarterly settlement (QS). This is a SEBI regulation that requires brokers to send unused funds back to clients every month or quarter.
Most customers then transfer these funds back to their broking accounts, with more than half of these transfers happening through UPI. So regulation essentially forces this movement of money every month or quarter, and the broker could end up bearing the cost when the money comes back, without any incremental benefit or revenue.
By the way, we currently don’t charge brokerage on equity delivery trades because the economics allow us to offer them for free. But if every UPI transfer starts carrying an additional cost, irrespective of whether the customer actually trades, I don’t see how we can absorb this indefinitely.
I think having an MDR is okay. It still doesn’t solve the problem of customers transferring money without transacting, but something like 0.02% with a cap of ₹5 or ₹10 per transaction seems much more reasonable for broking, instead of a cap as high as ₹300.
Why doesn’t Confluence support embedding Excalidraw or Lucid diagrams?
It’s very annoying to draw diagrams elsewhere and update the screenshot in Confluence. Very irritating when your solution is evolving fast.
Even Claude sucks when it comes to draw and update diagrams in-place.
For those wondering why ?
1. Ganpati festivals in Maharashtra
2. IRCTC opens bookings 2 months in advance. 8th September 2026 is Diwali. So most bookings likely to be people wanting to go home for Diwali
@arpit_bhayani Would Claude be able to review Claude's PRs without bias?
There should human on minimum one step of the development. That's non-negotiable.
Humans are unbeatable until we have breakthrough which solves the context problem and have infinite memory like us.
A full proof agent which reads the requirements and generates a PSD by itself navigating 10-20s of services, stitching flows is yet to be achieved.
The models are capable but I just worry much about exhausting the good context thread and yet achieving nothing.
"Here's reference, model and document these APIs and contract like Stripe would have done"
This is one of the go to prompts when I'm designing the APIs specs.
Stripe does best in terms of their documentations and API modelling.
Log masking is a bigger challenge than it seems.
I was just exploring if there's anything super fast that can mask sensitive data in logs, if logged at all.
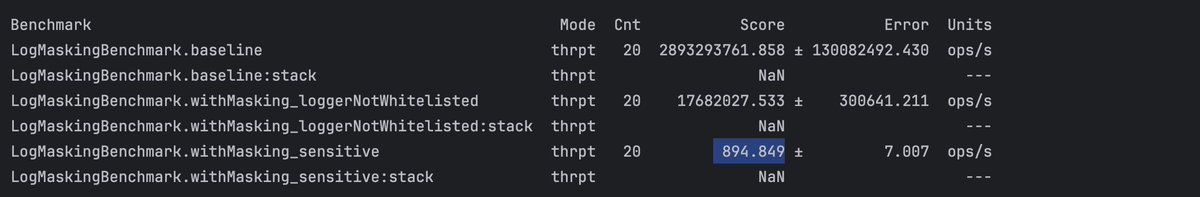
The first thing was obviously the regex way. I created a regex with all the key-value pairs I wanted to mask, and tested it against log lines of 12KB each. Its the worst log size it can go in my case. I wrote a Log4j RewritePolicy for it.
The results were shocking. While the baseline was ~2.8B ops/s, regex masking dropped to just ~850 ops/s. A massive, massive drop.
Obviously, I had to figure out something more optimized.
One thing worked in my favor that the LogEvent sent to RewritePolicy is always JSON.
So the next approach was to parse the entire log body into a JSON object, then recursively search for keys to mask and set their values.
This was a big jump from regex. masking with the JSON approach hit ~15K ops/s. Still far below baseline, but a massive improvement.
Now, for a single pod producing 500 logs/s, this isn't a big deal on its own. But here's the thing:
1. The pod, which is supposed to be doing only business logic, ends up spending CPU on masking too. How do you ensure the bulk of your CPU still goes to your core application? One option: move masking out of the pod entirely.
2. Let the pod just write to a file, and let the node level log shipper handle masking instead. But once logs are persisted to disk, the entire purpose of masking to protect sensitive data is already defeated.
The JSON approach should work fine for most services out there, but it's still a massive drop from baseline.
Does anyone know of another solution to this problem?
Hey everyone! I triaged a @nodejs vulnerability, wrote the fix, and pushed it through the security process.
I now think it shouldn't have been a CVE. And the fix broke a big part of the ecosystem.
🧵