i love building stuff:) 19y/o founder, reach out if u need help w anything coding/ai/gtm related (or want to test my local granola alternative i'm building rn)
in my network im called the chief of benchmarks bc im so deep in ai benchmarks. list of benches in the comments
if anyone has anyone has good additions or a proper computer use benchmark lmk
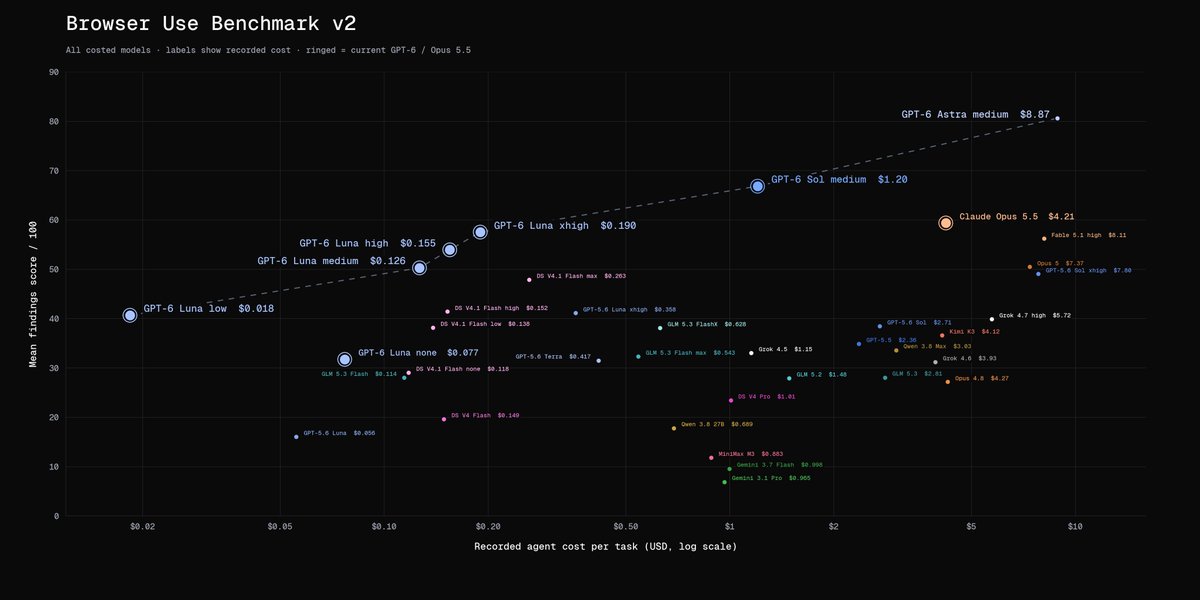
Browser Use Bench v2 Pareto frontier got completely redrawn today
> Claude Opus 5.5: 59.4
> GPT‑6 Sol medium: 66.9 (3.5x cheaper)
> GPT‑6 Luna xhigh: 57.6 (22x cheaper than Opus)
OpenAI is in its own league 🔥
All models available to try on our cloud.
[x-axis is log scale]
starting to realize i perhaps have been deceived by @maria_rcks shitposting. fuck. well anyways now im more hopeful it isnt getting nerfed that quickly and i can calmly go to sleep lol
nononono not yet pls dont i wanna sleep but this is scaring me. bc if the nerf is starting already this is BAD.
we finally need a good way to track models getting nerfed.
or is there already?
my theory is that they run the unquantized version at launch and then gradually bump it down
Anyone else think Opus 5.5 already got nerfed? First it was insanely good,
Now I’m spending half my time correcting stuff it understood perfectly at launch. No idea what they changed, but something feels off.
Either they cut the compute or the original Opus 5.5 was a free trial. Fun while it lasted.
See you all again when Fable 5.5 drops and is amazing for a short while then gets nerfed.
@philipmward@rohit3a a bit dated but sonnet 5 already back then was worse in every metric. but on itself it had the fable 5 orchestration capabilities which was nice.
not THAT bad of a model theoretically but in the context of the time it was released in pretty ass imo
@Da7_Tech man ur bench seems great. might be a stupid idea but why dont u just straight up ask if ppl want to donate to the bench or sponsor it at least??
ur model scoring good on a bench like this is good promo for a lab and after all u have 11k followers as well
im excited to see what haiku and sonnet 5.5 are going to be like. i hope anthropic gets around fixing the token effiency issue and its not sonnet 5 all over again. that would be awful
fable became what opus was
opus became what sonnet was
now we're getting sonnet and haiku back
A quick recap of what we saw today, and an answer to the question of whether there was a winner: both OpenAI and Anthropic gave us plenty to be excited about.
Let’s start with Anthropic. They addressed feedback about how Opus communicates, and they’re giving subscribers a reset they can save for later. To me, that’s a welcome sign that they’re listening.
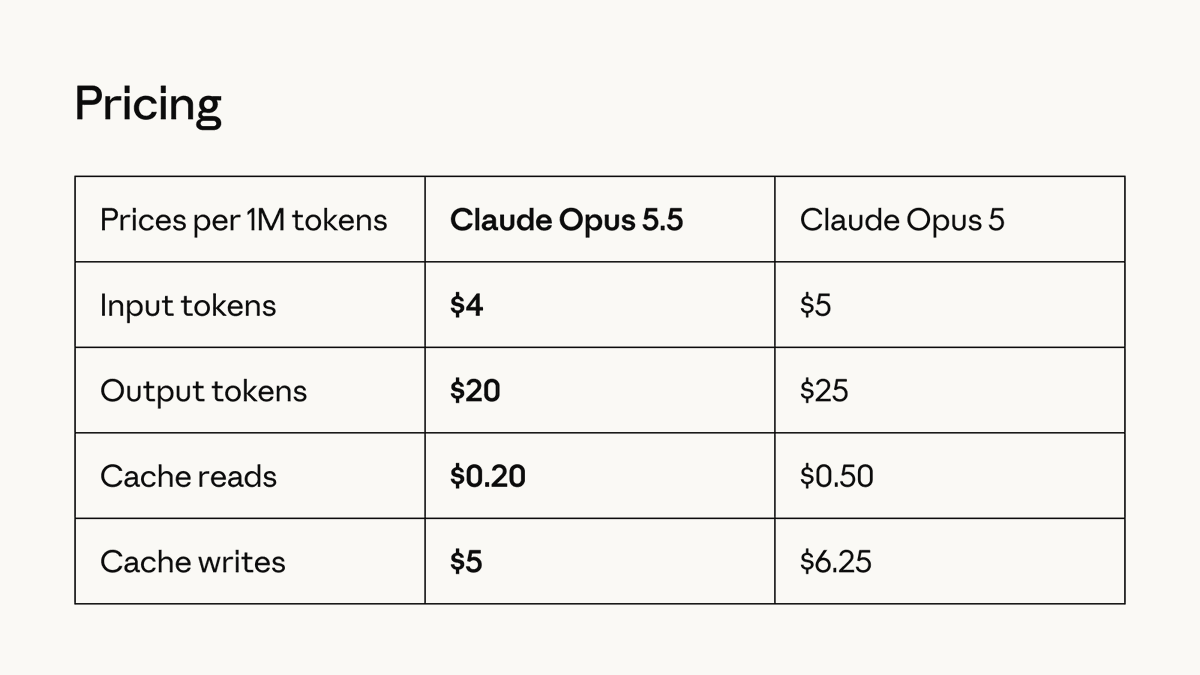
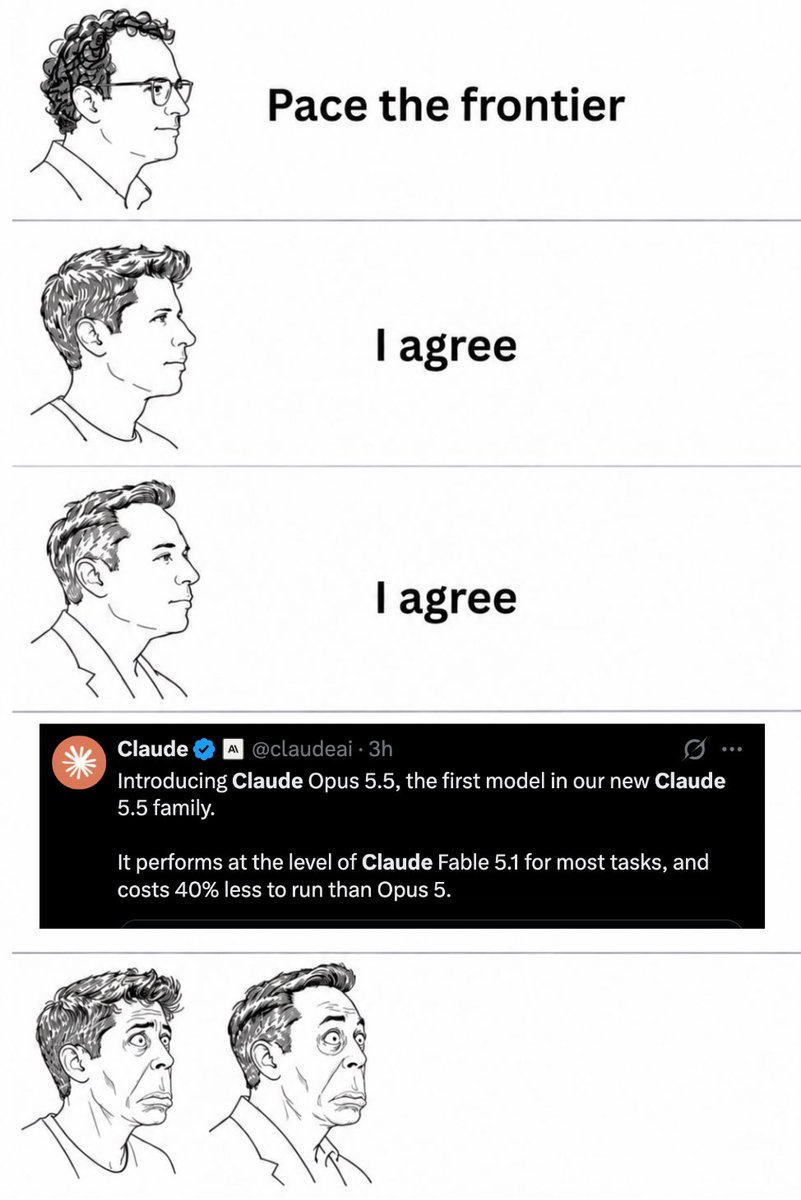
The benchmark results were a real surprise in the best possible way. Opus 5.5 scores above Fable 5.1 on every benchmark in Anthropic’s headline comparison table. Anthropic says it delivers Fable 5.1-level performance on most work and costs around 40% less than Opus 5 on typical workloads at default settings. A huge statement. I really did not see that coming. Kudos, Anthropic.
Sonnet 5.5 and Haiku 5.5 are set to follow in the coming weeks. I’m excited to see how far those efficiency gains carry over, and what a future flagship Fable 5.5 could deliver.
OpenAI delivered impressively too, with efficiency taking center stage. On DeepSWE 1.1, GPT-6 Luna at max effort scores 66.6%, comparable to Fable 5 at medium effort, at 96% lower cost per task in OpenAI’s comparison. That’s crazy. Luna’s API pricing is $0.10 per million input tokens and $0.50 per million output tokens.
Intelligence too cheap to meter? We’re certainly getting a striking demonstration of how much cheaper capable models can become.
GPT-6 Sol approaches Astra’s factual reliability on OpenAI’s internal evaluation and even outperforms low-effort Astra on AutomationBench at xhigh effort. That doesn’t establish Astra-level performance across the board, but it’s still impressive. Kudos, OpenAI. All of this makes me excited for the models still to come. Source
Beyond today’s releases, I’m also watching the rumors about an OpenAI counterpart to Grok Bot, although I haven’t verified a launch announcement.
so tl;dr Id say there is no clear winner today. Both OpenAI and Anthropic have delivered truly outstanding releases today, each with its own unique focus. This is what makes competition fun!
ah man i love opus 5.5 soo fkn much. im considering using it for my hermes just bc its just SOOO NICE TO TALK TO!
havent had such a good time talking to a model since opus 4.6.
glm 5.3 flash my beloved is nice to talk to but often too stupid