you don't need to be a developer to build with AI.
tools like Lovable and Bolt can turn simple prompts into working apps.
describe what you want.
AI generates the interface, writes the code, and helps you test it.
your idea can become a prototype in hours.
you don't need to be a developer to build with AI.
tools like Lovable and Bolt can turn simple prompts into working apps.
describe what you want.
AI generates the interface, writes the code, and helps you test it.
your idea can become a prototype in hours.
Retrieval returns the five most relevant chunks. Two of them disagree. Now what?
This is the failure mode nobody writes an eval for, and it’s everywhere in enterprise data. Relevance ranking has no opinion about truth — so the model picks whichever source it read first, or quietly blends both into an answer that exists in neither document.
Four patterns, four different fixes:
Same fact, different dates. The 2024 policy and the 2026 revision both match. Prefer the newer and say which version the answer came from. If you can’t tell which is newer, that’s a metadata bug, not a model bug.
Different scopes. A global policy and a country-specific exception. The narrower source wins, and the answer should name the scope it applied.
Draft vs approved. A shared draft ranks just as well as the signed version. Filter by status at index time — asking the model to notice “DRAFT” in a header works until it doesn’t.
Genuinely contradictory. Two approved, current, in-scope sources that disagree. Don’t average them and don’t pick. Surface both, show the citations, and escalate. The honest answer is that your documentation has a conflict, and the AI just found it.
The common thread: recency, scope and status have to be metadata you can filter on. If they only exist as words inside the text, you’ve made truth a ranking problem.
why use many token when few token do trick
this is a real GitHub repo and it has 112,000 stars
it's called caveman
it makes your coding agent talk like a caveman
short, no fluff, straight to the point
the result: 65% fewer tokens
same work, way lower bill
works as a skill and a proxy for coding agents
most people building AI agents have no idea if they actually work
iFixAi checks it in under 2 minutes
it runs 60 tests on your agent and gives it a grade from A to F
it looks for made-up facts, prompt injection, hidden goals, ignored instructions and silent failures
works as a plugin inside Claude Code and Codex, just ask it to audit your setup
the open source engine is free
24,000+ stars on GitHub
test your agent before your users do
your AI coding agent forgets everything the moment you close it
someone fixed that
ai-memory gives Claude Code, Codex, Cursor, Gemini CLI and 20+ other agents one shared long-term memory
quit Claude Code mid-task, open Codex in the same folder, and it picks up exactly where you left off
what you tried, what failed, what's still open
works across machines and whole teams
the memory is plain markdown files you can open in Obsidian
works with zero API keys
free and open source, 5,500+ stars on GitHub
Why write agent code you can draw?
Langflow lets you build AI agents and workflows by connecting blocks on screen.
Each block is real Python, so you can open it and edit the code.
A playground lets you test your flow step by step.
When it's done, deploy it as an API or as a tool other agents can call.
It works with the major AI models and vector databases.
2 commands start it on your machine at port 7860.
Don't want to set up Python? The desktop app for Windows and macOS bundles everything.
155.6k stars on GitHub
Copy the prompts behind 500+ AI images
Someone collected them on GitHub, each with the full GPT Image 2 prompt.
The repo is awesome-gpt-image-2.
The examples span 12 categories, including posters, realistic photos and app screens.
Pick one you like, copy its structure, swap in your own details.
13 template categories cover e-commerce, architecture, storytelling and more.
There's also a skill that lets your agent pick the style for you.
Heads-up: the examples come from community sources, so check rights before commercial use.
8.7k stars on GitHub
5 free skills that fix what annoys you about Claude Code
1. i-have-adhd → your agent puts the answer first and caps lists at 5 items (56.2k ⭐)
2. humanizer → paste AI text, get it back without 26 telltale AI patterns (55.3k ⭐)
3. archify → describe your system, get a clickable diagram in 1 HTML file (78.9k ⭐)
4. ponytail → your agent checks if the code needs to exist before writing it (160k ⭐)
5. security-audit-skill → point it at a repo, get a 6-phase security audit report (25.7k ⭐)
each one installs in 1–2 lines
save this before your next session 🔖
share it with someone who still runs Claude Code bare ♻️
Retrieval returns the five most relevant chunks. Two of them disagree. Now what?
This is the failure mode nobody writes an eval for, and it’s everywhere in enterprise data. Relevance ranking has no opinion about truth — so the model picks whichever source it read first, or quietly blends both into an answer that exists in neither document.
Four patterns, four different fixes:
Same fact, different dates. The 2024 policy and the 2026 revision both match. Prefer the newer and say which version the answer came from. If you can’t tell which is newer, that’s a metadata bug, not a model bug.
Different scopes. A global policy and a country-specific exception. The narrower source wins, and the answer should name the scope it applied.
Draft vs approved. A shared draft ranks just as well as the signed version. Filter by status at index time — asking the model to notice “DRAFT” in a header works until it doesn’t.
Genuinely contradictory. Two approved, current, in-scope sources that disagree. Don’t average them and don’t pick. Surface both, show the citations, and escalate. The honest answer is that your documentation has a conflict, and the AI just found it.
The common thread: recency, scope and status have to be metadata you can filter on. If they only exist as words inside the text, you’ve made truth a ranking problem.
“It feels fast” is a p50 statement. Churn is written at p95.
Illustrative distribution for 10,000 requests through a 3-step agent:
→ p50: 2.1s
→ p75: 3.4s
→ p90: 6.8s
→ p95: 11.2s
→ p99: 28.5s
The median looks great. Meanwhile 1 in 20 sessions waits eleven seconds and 1 in 100 waits almost half a minute — and those aren’t random users. They’re disproportionately the ones with the biggest documents, the longest histories, the most tool calls. Your best accounts live in the tail.
Three things that matter once you start looking at percentiles instead of averages:
Tails multiply in multi-step systems. A request that hits p90 on each of three steps isn’t a p90 request — it’s p99-shaped. Measuring each step separately hides this; you need end-to-end timing per route.
A single slow dependency sets your tail. One retrieval call without a timeout, one provider having a bad five minutes, and the whole distribution stretches.
The fixes are boring and they work. Per-step deadlines, a cheaper fallback path when the budget is blown, visible progress so a long wait feels like work rather than a hang.
Alert on p95. The average will tell you everything is fine right up until renewal.
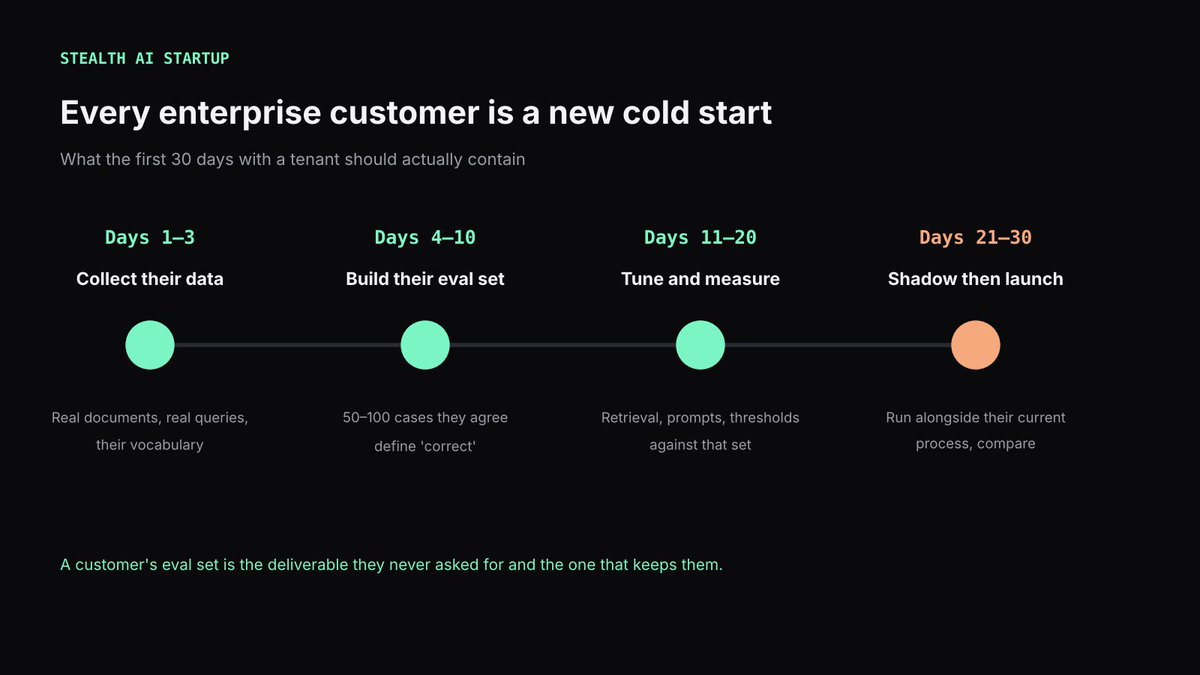
Your product is good. For a new enterprise customer, it starts out mediocre again. 🧊
Their documents are formatted differently, their teams use vocabulary your retrieval has never seen, and their definition of a correct answer isn’t quite anyone else’s. The generic system that delights your existing users lands at “it’s okay” in their first week.
A first 30 days that works: days 1 to 3 collecting their real documents and real queries. Days 4 to 10 building an eval set of 50 to 100 cases they agree define correct. Days 11 to 20 tuning retrieval, prompts and thresholds against that set. Days 21 to 30 running in shadow mode beside their current process, then launching.
The eval set is the part that matters most. It makes quality a number you can both see, instead of an argument in a QBR.
Onboarding an AI product isn’t configuration. It’s calibration. 🎚