I'm really excited about the possibilities this work opens up!
It is an inventive way for parameter decomposition to get more for less.
Great work by Antoine (@teleturnip)!
(a @MATSprogram collaboration)
@arithmoquine Re: the svg bit in your original post, the models are pretty good now. GPT 6 Astra high on the left, Claude Fable 5.1 medium on the right
My team at @GoodfireAI has been cooking up a new way to do interpretability: decompose a language model’s weights, not its activations.
Our decomposition natively handles attention (!) and behaves less like a lookup table and more like a generalizing algorithm. (1/6)
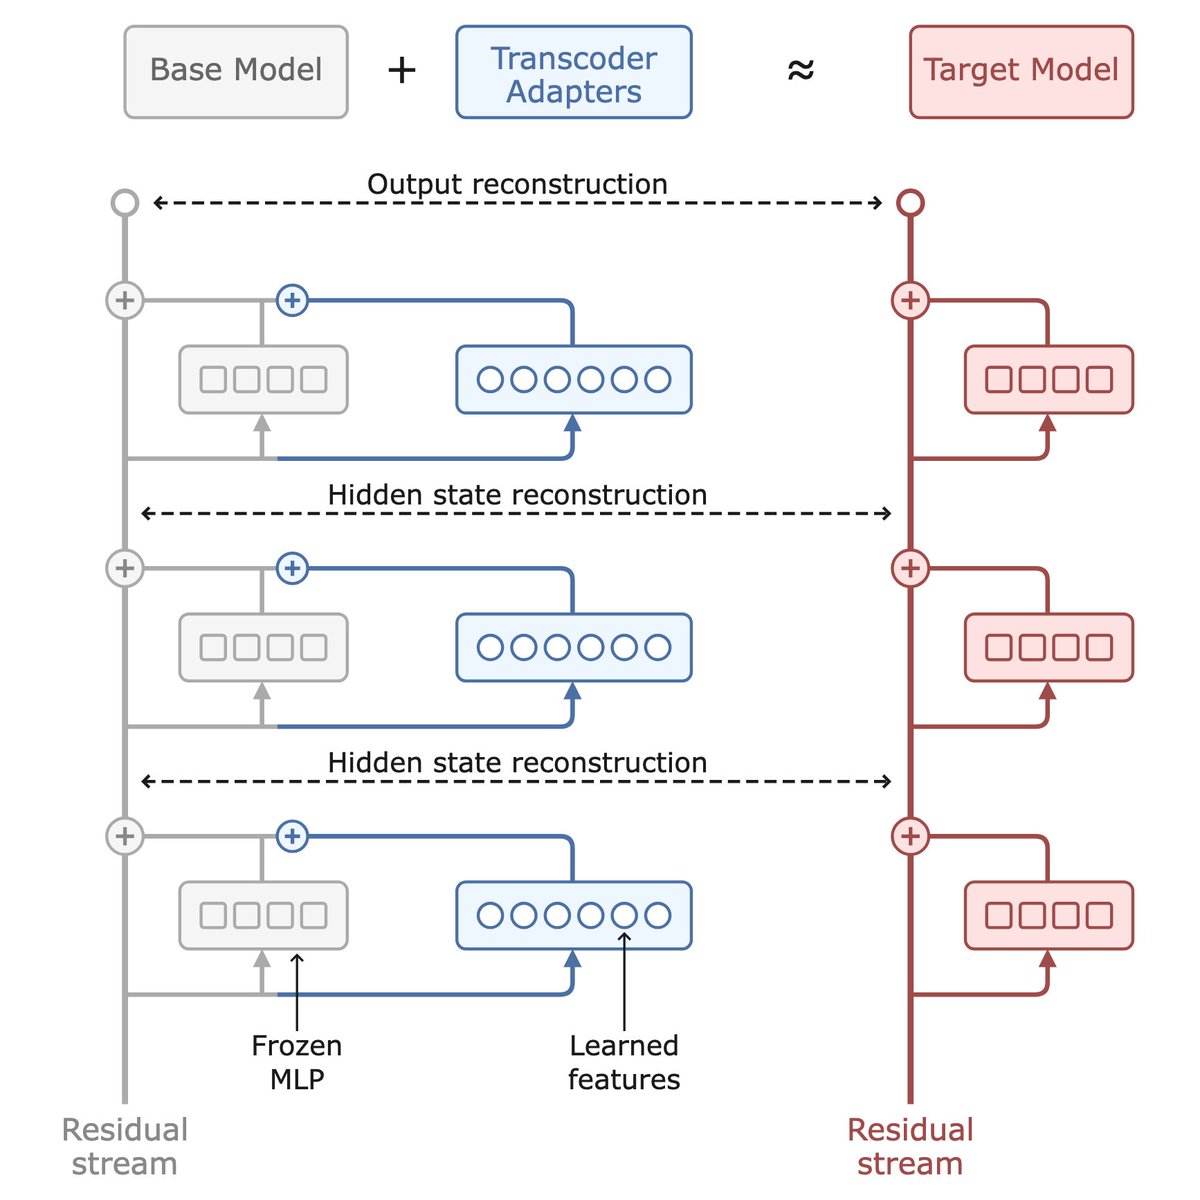
What does reasoning fine-tuning actually change inside a model?
In our new paper, we introduce transcoder adapters to learn sparse, interpretable approximations of how reasoning fine-tuning changes MLP computation. 🧵
Had a blast working on this project with @_danielfb and co 🥂If you're in San Diego you should come by tomorrow to learn how we created curricula over tasks and levels 🤖⚒️🎂
LLMs know how to make a bioweapon! 🦠
But, when we *un*learn harmful knowledge about anthrax, the model underperforms on related concepts.
It is difficult to detect what “ripple effects” a model-edit has on an LLM.
We found a solution🧵👇(Spotlight at MechInterp Workshop)
Check out the paper & try the tools for yourself at https://t.co/U6YNnevQBN
Excited to see what you'll find, reply with your favorite attention heads!