AuraLuxMuse: Adaptive Fusion Modeling for Aesthetic Stage Lighting Design with Music and Expert Guidance
Junyu Deng, Jiale Cao, Mengtian Li, Zhongxia Ji, Ruhua Chen, …
https://t.co/wUo65JJ3qC [𝚌𝚜.𝙼𝙼 𝚌𝚜.𝙰𝙸]
💬Accepted to appear in SIGGRAPH Asia 2026 Conference Papers
MemoCare: An Interactive Multimodal Mobile System for Automated Cognitive Screening
Duy-Cat Can, Mau Minh Phuc Le, Tuan-Khoa Hoang, Hai-Dang Nguyen, Trung-Hieu Do, Dang Minh Ly, …
https://t.co/cDMGC0XrKN [𝚌𝚜.𝙼𝙼 𝚌𝚜.𝙲𝚅 𝚌𝚜.𝙷𝙲]
💬Submitted to the MMM 2027 Demo Track
From Expression to Reaction: Role-aware Visual Transfer and Stimulus-guided Reasoning for Interlocutor Emotion Recognition
Wei Wang, Zhaowu Li, Jianjie Luo, Fu Lee Wang, Lap-Kei Lee, Zhenguo Yang
https://t.co/01HGuUMn6i [𝚌𝚜.𝙼𝙼 𝚌𝚜.𝙲𝚅]
Toward Generative Video Communication: A Dual-Stream Digital Transmission Framework
Bingyan Xie, Longyu Zhou, Tianhao Liang, Yongpeng Wu, Zehui Xiong, Wenjun Zhang, Tony Q. S. Quek
https://t.co/8qnRsmMC9n [𝚌𝚜.𝙼𝙼]
💬Accepted by the IEEE Wireless Communications Magazine
Small Cues, Big Consequences: Learning Pivotal Cues for Multimodal Meme Classification
Akshit Sharma, Prashant W. Patil
https://t.co/euYUsdbxp0 [𝚌𝚜.𝙼𝙼 𝚌𝚜.𝙲𝙻 𝚌𝚜.𝙻𝙶]
💬Accepted to EMNLP 2026 Findings
ROAM-ASD: Robust Open-World Active Speaker Detection with Flexible Multimodal Fusion
Pu Wang, Yujun Wang, Hugo Van hamme
https://t.co/Qxjg0CCX0o [𝚌𝚜.𝙼𝙼 𝚌𝚜.𝙲𝚅 𝚌𝚜.𝚂𝙳 𝚎𝚎𝚜𝚜.𝙰𝚂 𝚎𝚎𝚜𝚜.𝙸𝚅]
💬Submitted to IEEE ICASSP 2027
CogenPVG: Cognitive-Enhanced Reflective Multi-Agent Framework for Persuasive Video Generation
Yuntian Xiao, Shoulong Zhang, Wenfeng Song, Yan Wang, Yi Chen, Shuai Li
https://t.co/iE7ExlbDZI [𝚌𝚜.𝙼𝙼 𝚌𝚜.𝙰𝙸]
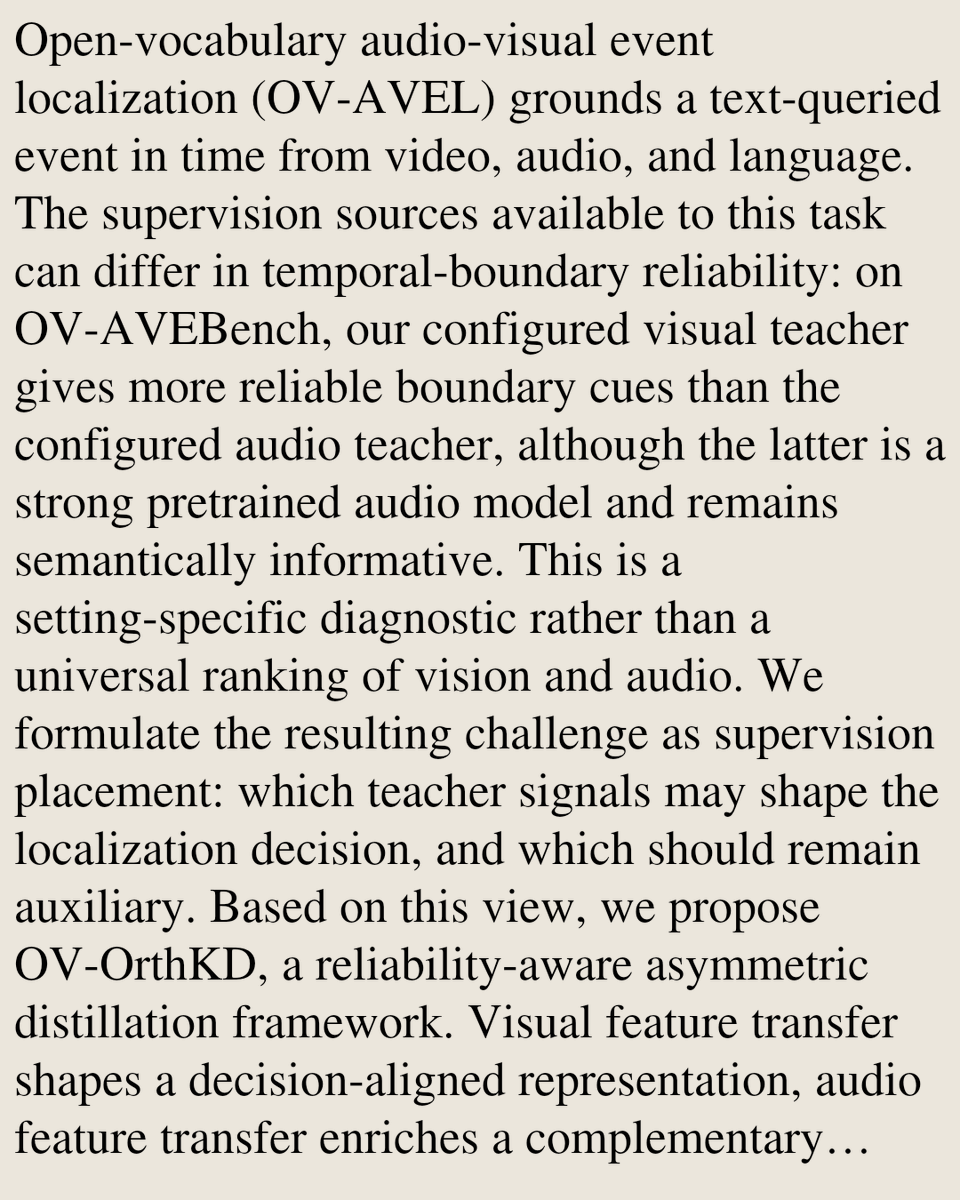
If You Hear It, Help Find It: Orthogonal Knowledge Distillation for Open-Vocabulary Audio-Visual Event Localization
Yi Xu, Cheng Chen, Wenzhuo Lei
https://t.co/GLJ1Mr5WrZ [𝚌𝚜.𝙼𝙼 𝚌𝚜.𝙲𝚅 𝚌𝚜.𝙻𝙶 𝚌𝚜.𝚂𝙳]
💬Accepted to ACM Multimedia 2026 (poster)