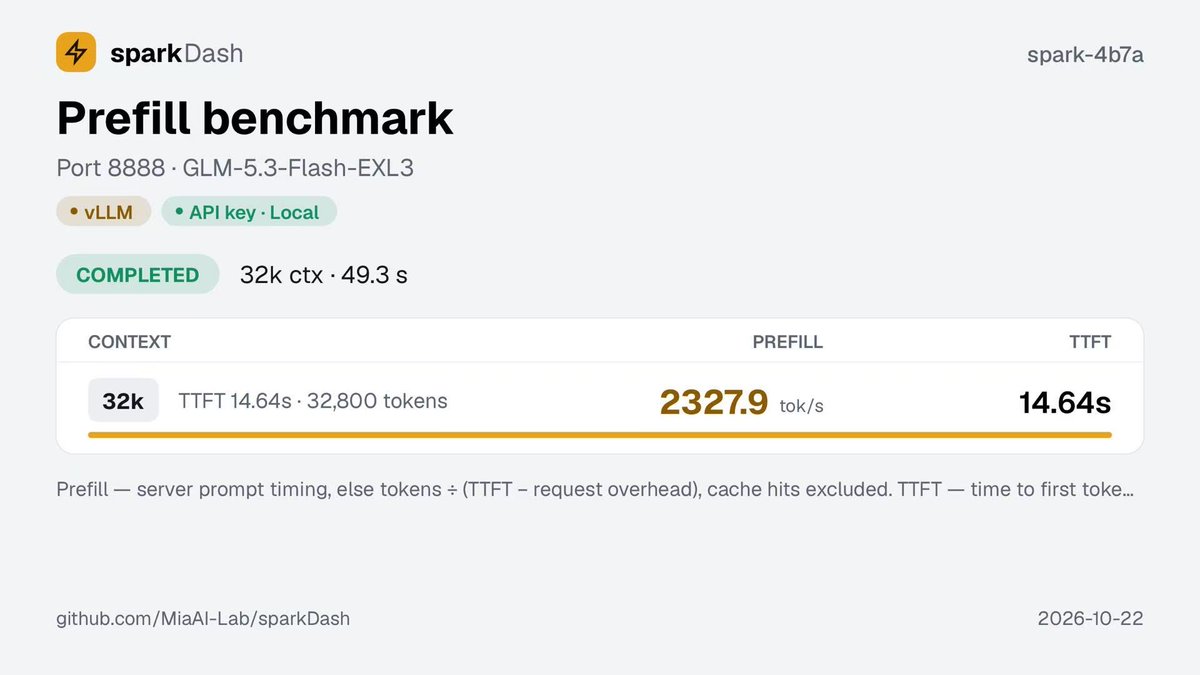
Correction: I found my earlier 100+ tokens/s result was inflated by an API proxy buffering tokens and delivering them in bursts, which distorted SparkDash’s client-side decode measurement.
NVIDIA just released Flare, a local inference server built for DGX Spark and RTX Blackwell GPUs
- Built for long chats, agents and tool calls
- Serves from Rust, no Python
- Plans memory up front
- FP8 KV cache by default
Interesting timing... right around when DeepSeek open-sourced their inference engine.
Link below.