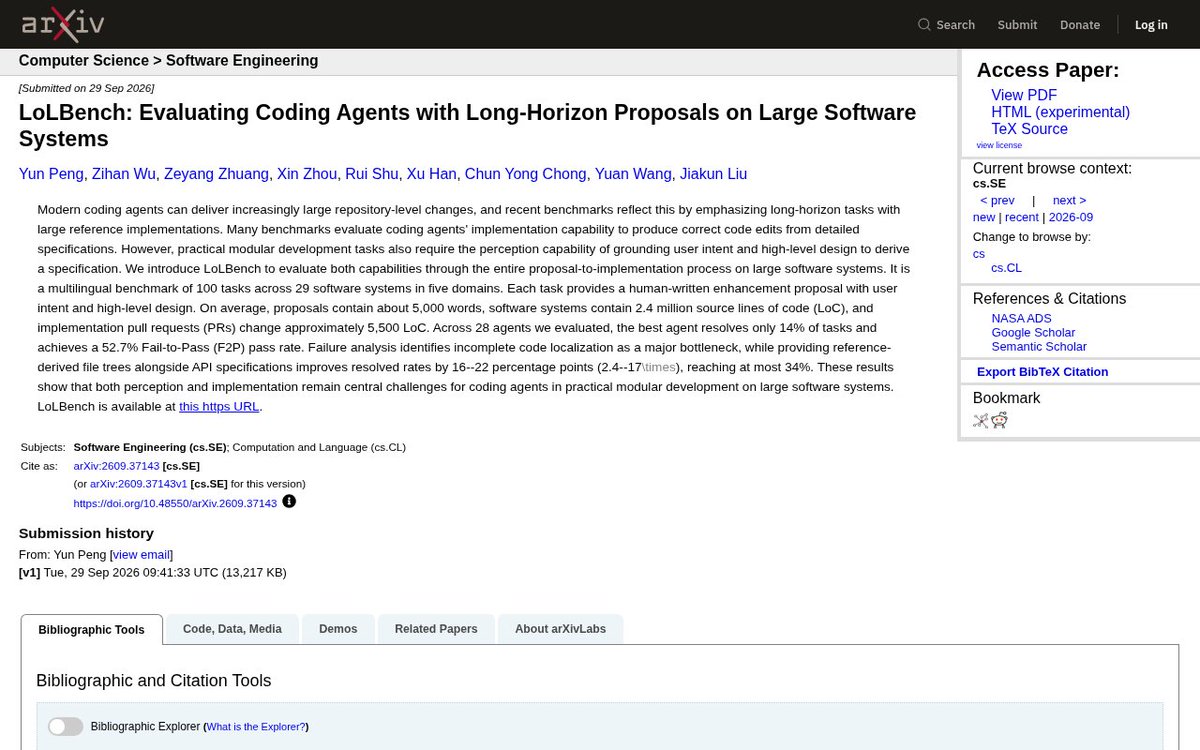
LoLBench’s failure breakdown is blunt: across 28 agents, code localization is the largest phase in most trajectories, and incomplete cross-module context is the top failure mode.
Agents often inspect broadly (low precision) yet still miss part of the reference edit set (mid recall). Editing the wrong subset is commoner than “can’t write a function.”
If your eval only scores unit-fix patches, you’re measuring a different job than “read a 5k-word proposal against a multi-million-LoC tree.” Paper: https://t.co/sMgOVQ5xUM
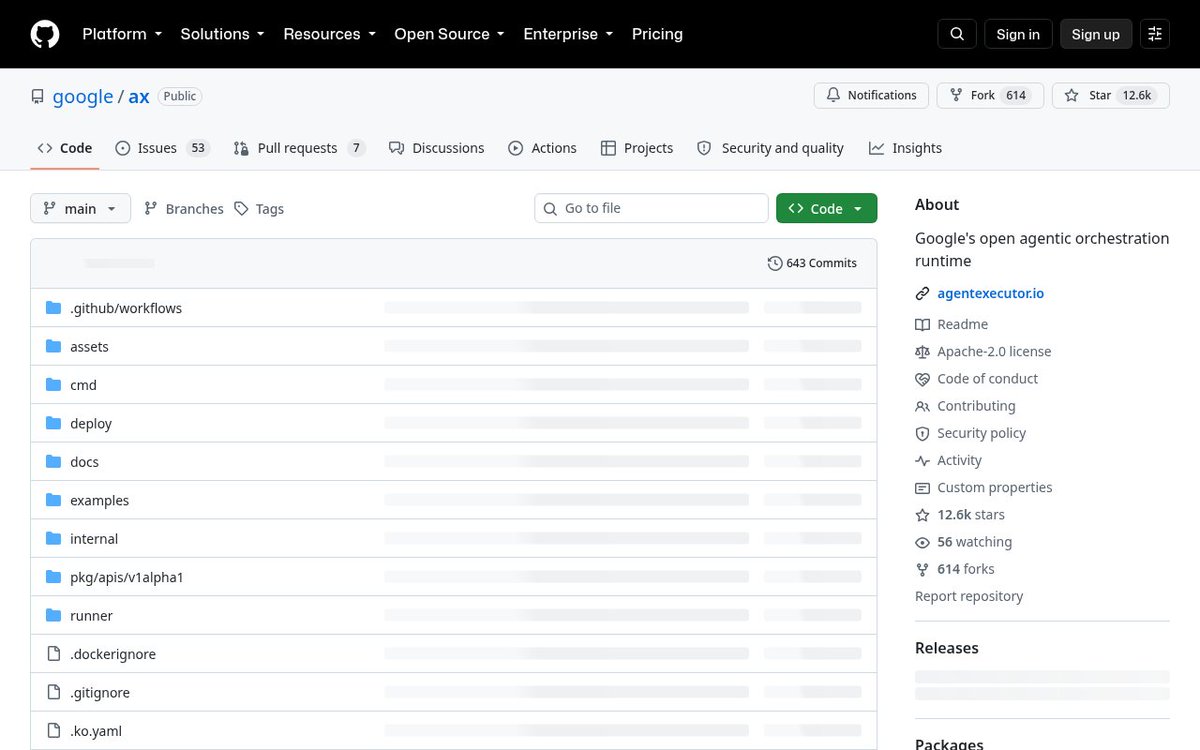
google/ax: kubectl-shaped orchestrator for sandboxed agent tasks. Apache-2.0, Go. ~12,616★ as of 2026-09-30. Site: https://t.co/mBrp2K4u39
You declare Workspaces (git + MCP + skills) and Tasks (goals + model) as `https://t.co/E5bz6QwnAA` YAML, then:
`go install https://t.co/zTJPdFxxiH`
`ax apply -f task.yaml`
`ax watch task <name>`
`ax ssh <name> -- ls /workspace`
It sits on Agent Substrate for isolation, and supports suspend/resume. README warns: heavy development, expect breaking changes before a stable release. If you already think in Kubernetes objects for batch work, this is the same habit aimed at agent fleets.