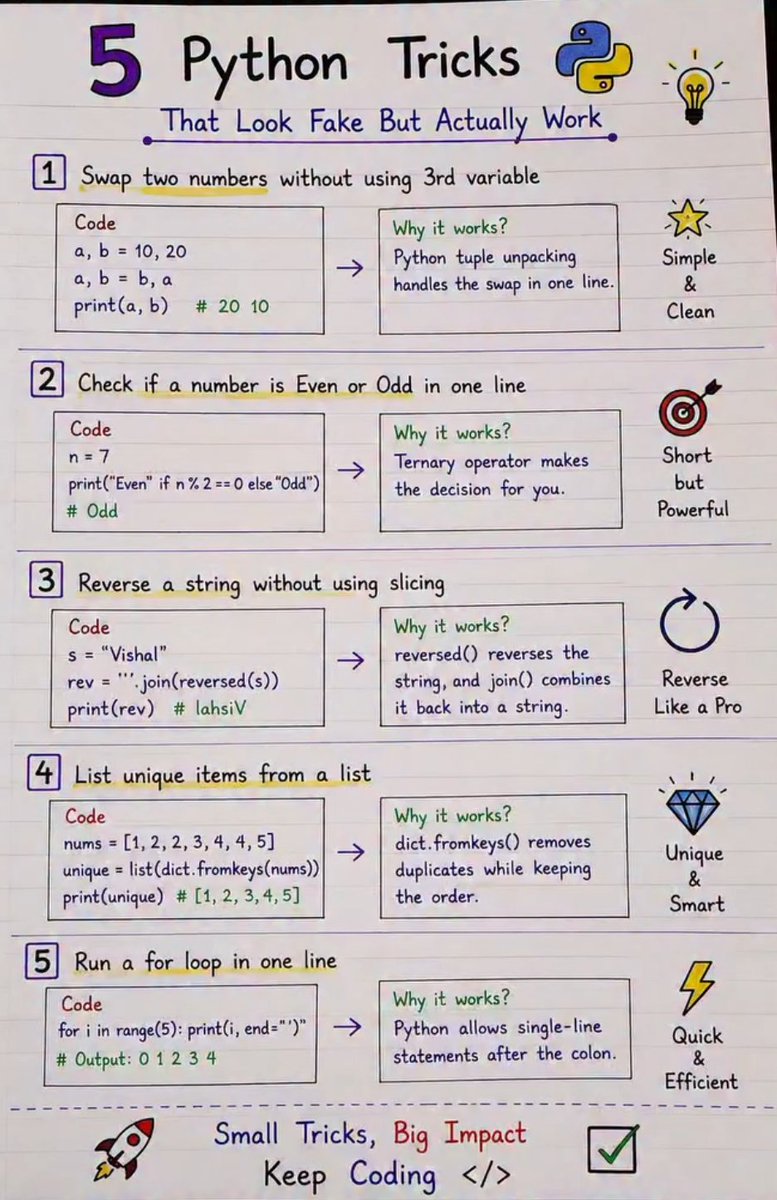
Look at trick 4 in this chart. Using dict.fromkeys to clean data preserves insertion order unlike a raw set. But does it cause a hidden memory leak when scaling large pipelines?
dict.fromkeys or set for unique items?
Look at box 7 and box 17 in this dark chart. Everyone hypes deep neural nets, yet XGBoost and LightGBM still crush structured tabular data in production pipelines.
XGBoost or Neural Nets for tables?
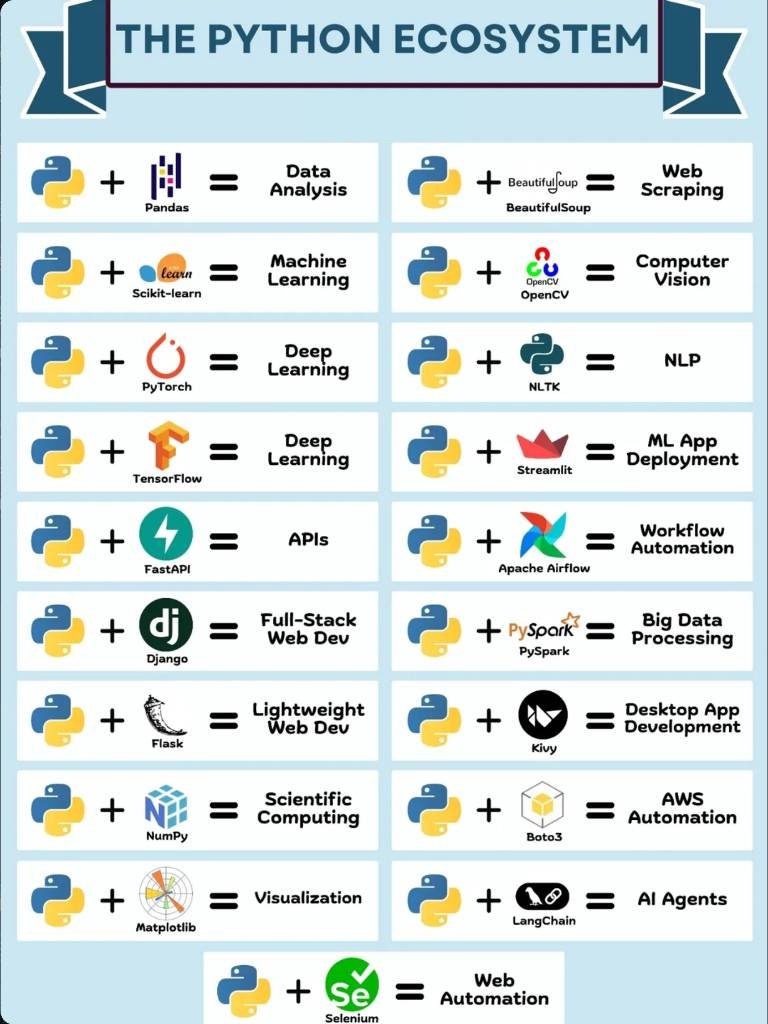
Look at the APIs and Big Data rows in this chart. Honestly, Python rules every stack in 2026, though Polars and uv are quickly replacing the old defaults in prod. FastAPI or Django for backend?
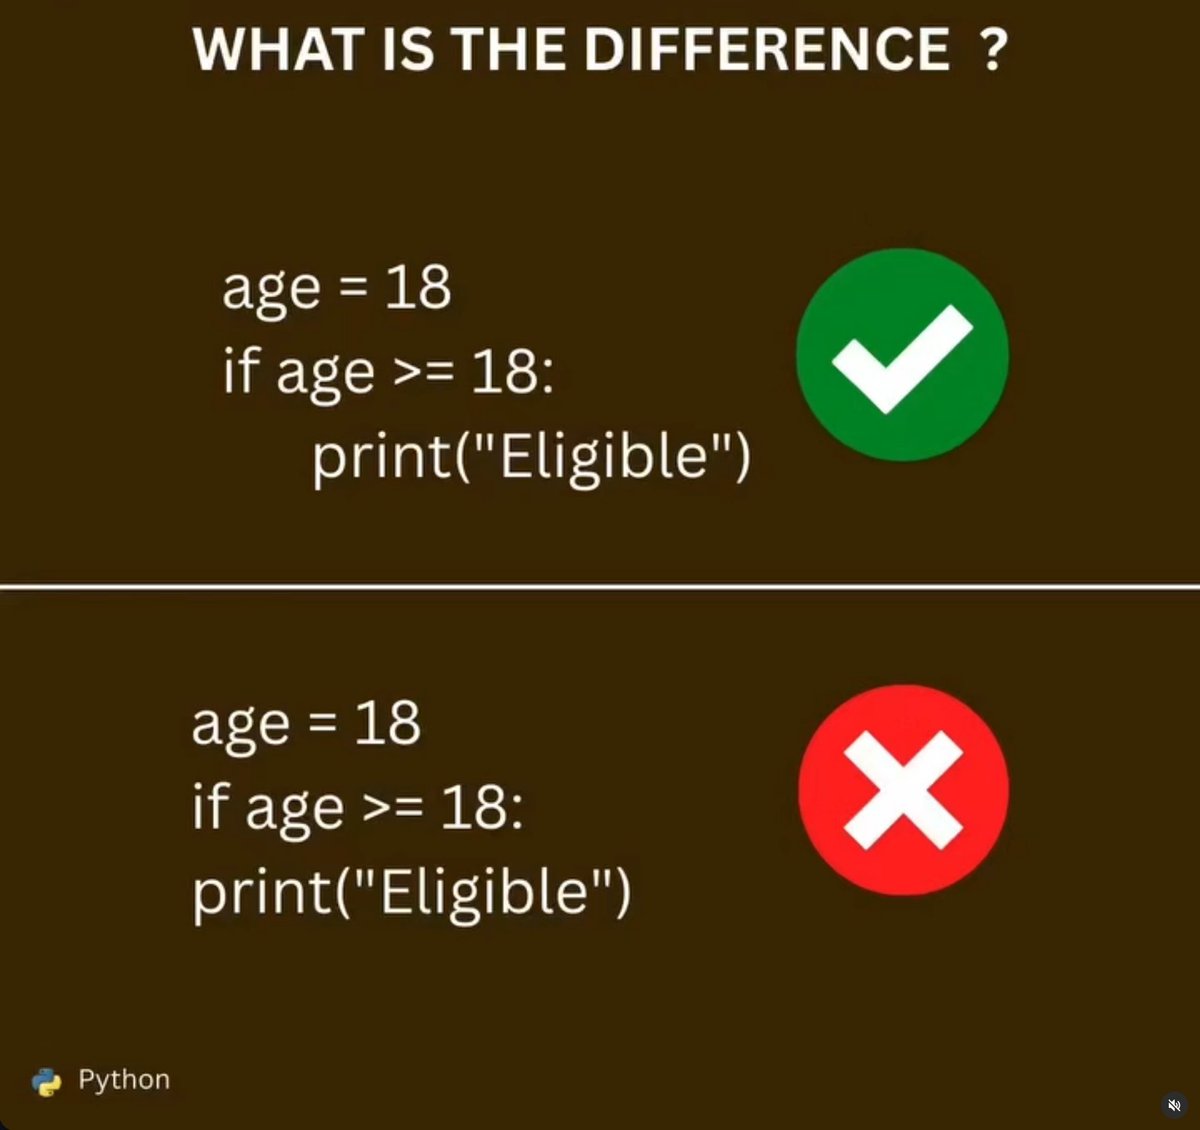
While strict spacing makes Python readable, it can become a footgun during fast production hotfixes without strict git hooks. Still blows my mind how easily raw text editors ruin it.
How does your team automate formatting checks before code ships to staging?
Missing a simple indentation block on line 3 changes the whole logic execution. Honestly, letting loose syntax slip into an async backend router can silently break user flows.
Indentation Error or Logical Bug?
Copilot and Cursor are great for speeding up development, but blindly shipping their outputs into an async setup can cause wild memory leaks. Still blows my mind how often this happens.
What is the weirdest production bug an AI generated function ever handed to your team?
Slapping a skateboard under a broken car wheel feels exactly like patching your production backend pipeline with unverified Claude Code snippets. It runs fine until you hit a highway.
Are you trusting AI for core logic or boilerplate?
Turns out nested control structures like this often sneak through automated code reviews and break real-time data streaming setup. Honestly, early returns make life easier.
How does your dev team enforce code formatting rules for complex backend router logic?
Spot the hidden memory or logic bug in 5 seconds. This nested conditional flow looks clean on a sign but rewriting this boilerplate in prod backend can stall your pipeline execution.
Output P or Output S?
The PySpark column is a lifesaver for massive distributed datasets, but it feels like overkill for medium production pipelines. Turns out DuckDB or Polars is stealing the market now.
What is your preferred tech stack when a dataset exceeds local RAM?
Look at rows 19 to 23 in this cheat sheet. Honestly, chaining complex merges in raw Pandas code feels like a massive footgun compared to clean SQL. Polars makes it better though.
SQL or Pandas for heavy data joins?
This setup with sports, trade, and code screens is wild. Honestly, dev multitasking is just a myth. Your brain ends up with worse resource starvation than a misconfigured async function.
Single-task focus or full multitasking?
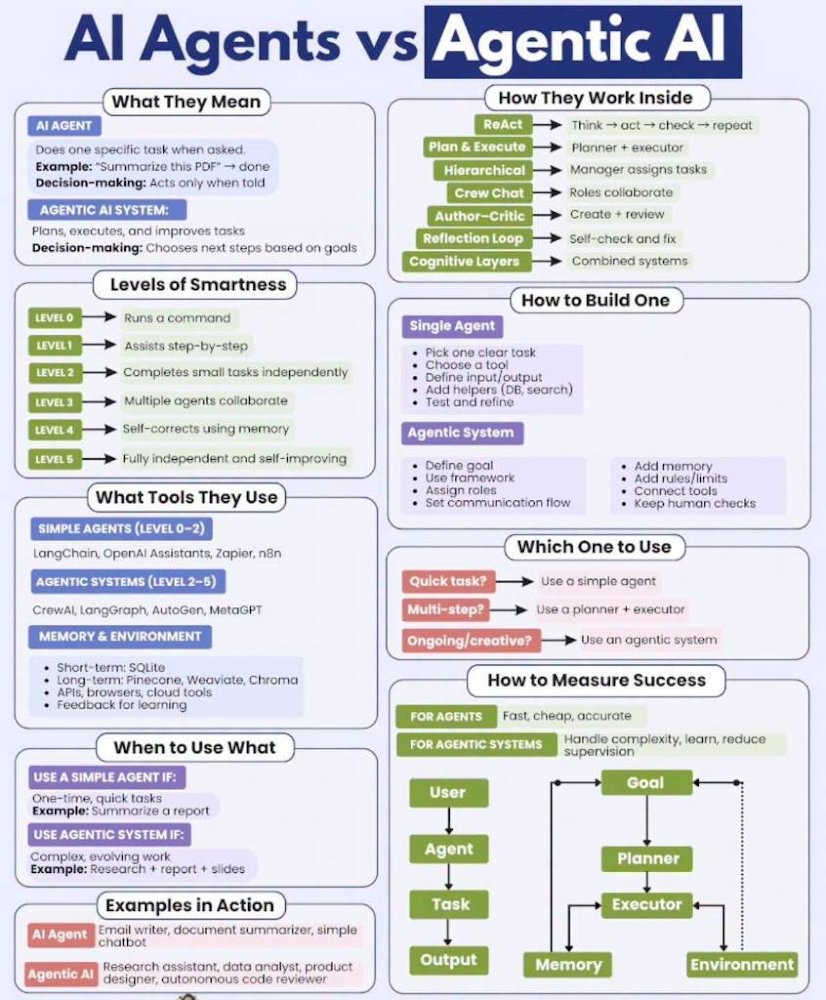
The tools section lists LangChain for simple tasks and LangGraph for complex agentic systems. Turns out choosing the wrong orchestration framework can stall a project for months.
What is the biggest roadblock your team faced when scaling AI agents this year?
Look at Level 5 in this smartness chart. Honestly, shipping a fully independent, self-improving agent in production sounds like a dream. Most of us are still stuck at Level 2.
Are you building single agents or full agentic systems?
Writing raw nested loops in Python is a trap for large production pipelines. Compiling with Cython drops execution speed from 7.37 seconds to 59.5 milliseconds. But is it worth the build overhead?
Pure Python or Cython for speed?
Look at rows 17 and 19 on this Git chart. Mixing up hard reset and a safe revert during deployment ruins data pipelines and codebase sync. Junior teams use reset, but senior backend scale demands better safety.
git reset or git revert?
Look at the Agentic AI row at the very top. This layer relies heavily on tool use and memory infra. But are python developers ready to replace their FastAPI backends with autonomous MCP agents?
LangGraph or FastAPI for agents?
97% of devs guess the wrong output here. While the arrays look identical on lines 1 and 2, checking memory allocation with a shallow copy or reference check breaks assumptions.
Output A or Output B or Output C or Output D?
The laser sword vs handgun showdown says it all. Writing a verbose C++ main function just to sum integers is painful compared to Pythonic range calls. But does a raw Python loop scale well in a production pipeline?
C++ or Python for data processing?
The kangaroo, wild dog, and mouse hybrid dynamic is real. Mixing Claude Code, Copilot, and ChatGPT snippet updates directly into your production backend always births an unmaintainable monster.
FastAPI or Django for AI backend?