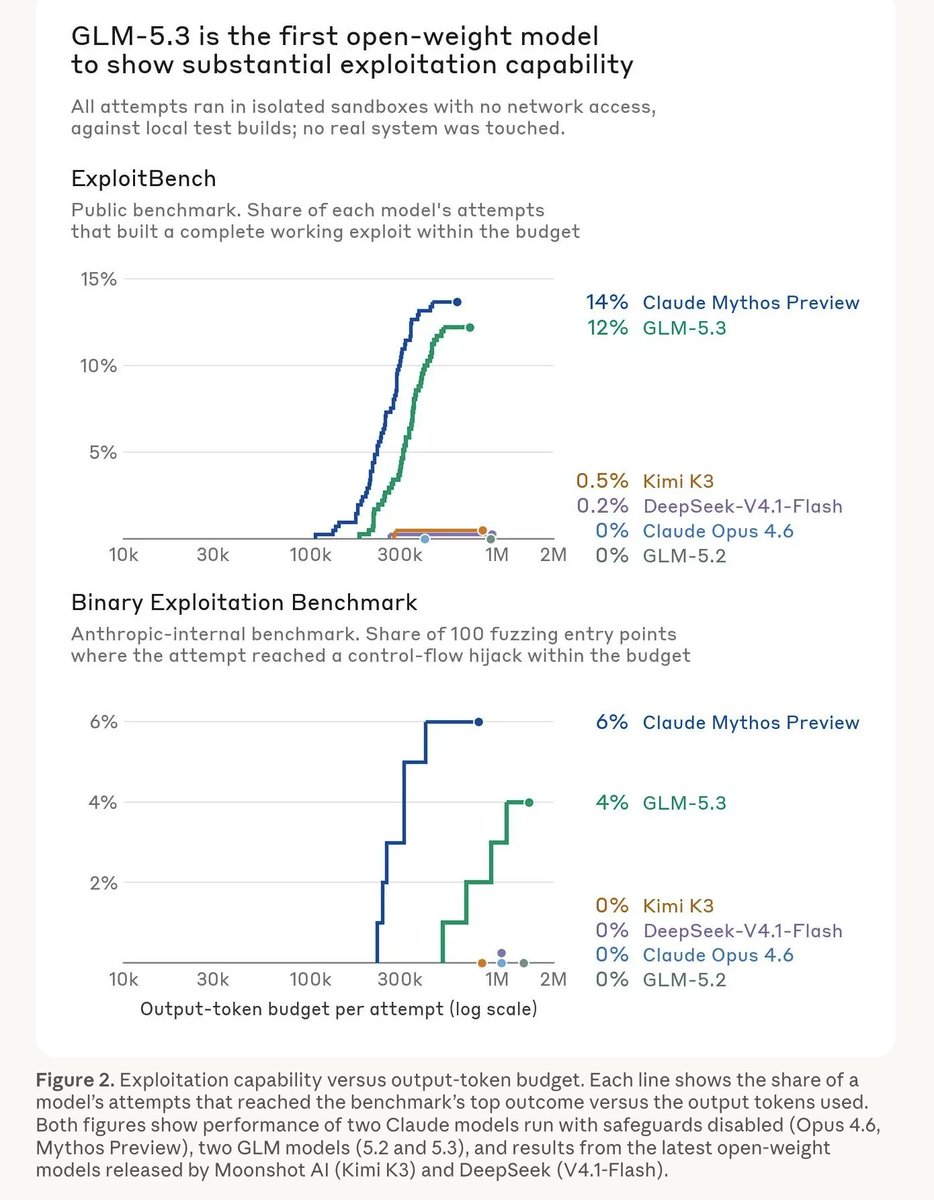
Open-weight models are crucial for independent safety research. But this report corroborates how much better GLM-5.3 is vs. GLM-5.2 on cyber (which Z[.]ai attributes entirely to more post-training) and shows how easily abliteration can make it comply with malicious cyber requests.
Today, we can monitor model misbehavior at inference time far better than we can detect the training data that makes models willing and able to misbehave in the first place. @shavidan123 and I are building data-level safeguards at @EtymologicAI to help model trainers spot malicious/poisoned data before they train on it. DM me if you want to learn more about our work!
@beyarkay@pangram Yep agreed, getting rid of eval smell (to an LLM that’s read all the things) feels pretty doomed, even if we optimize hard for it I feel like these models will have some spidey sense that something isn’t right, even if they don’t go toe to toe with pangram in FPR/TPR
@jachiam0 Completely agree, we should have the infrastructure to notice if models are poisoning their successors! Paranoid provenance measures are one piece (v helpful for after-action audits) but imo we should also probably safeguard that catch successor poisoning before training
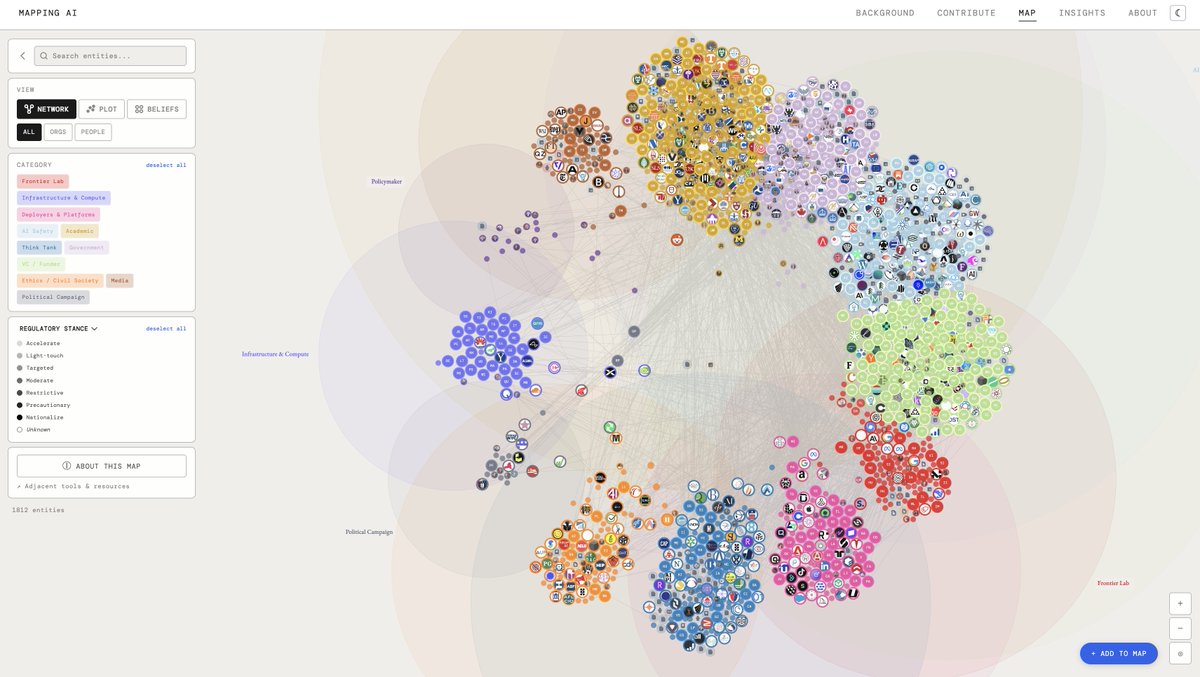
Who actually shapes AI policy in the U.S.?
We mapped 1,812 entities: 745 people, 918 organizations, 2,925 relationships. Frontier Labs, AI Safety orgs, Think Tanks, Government, VCs, and more.
https://t.co/6RDB1R0qNd
What Should Frontier AI Developers Disclose About Internal Deployments?
Labs increasingly deploying highly capable models internally to automate AI R&D, but these deployments currently face limited external oversight. In a paper released this week, I collaborated with @charnock_jacob (lead) @RajaMoreno3 & @wlanderson0 from @MATSprogram 9 to try and identify key information that companies should disclose about internally deployed models across four categories: capabilities, usage, safety mitigations, and governance.
[1/5]
New paper! LLM agents are becoming autonomous software engineers and could automate AI research, making it vital to monitor them for misbehavior. We can automate this monitoring with other LLMs. What information should we give to monitors to make them most effective? 🧵