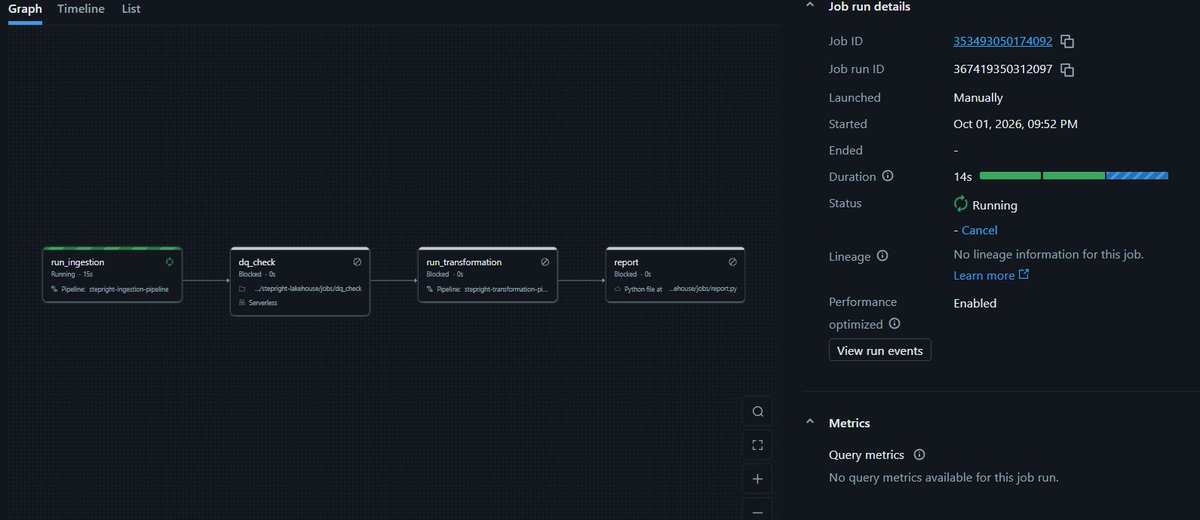
Today I worked on a Databricks orchestration project.
I created a Job with 2 pipelines, a notebook, and a Python script.
Ingested database data into Bronze and split it into valid and quarantined records.
Added a health check to allow or stop the job based on quarantined rows.
Auto Loader is a Databricks feature for incremental file ingestion. It provides efficient file discovery and supports schema inference/evolution. It can ingest files from supported cloud/object-storage locations.
#Databricks
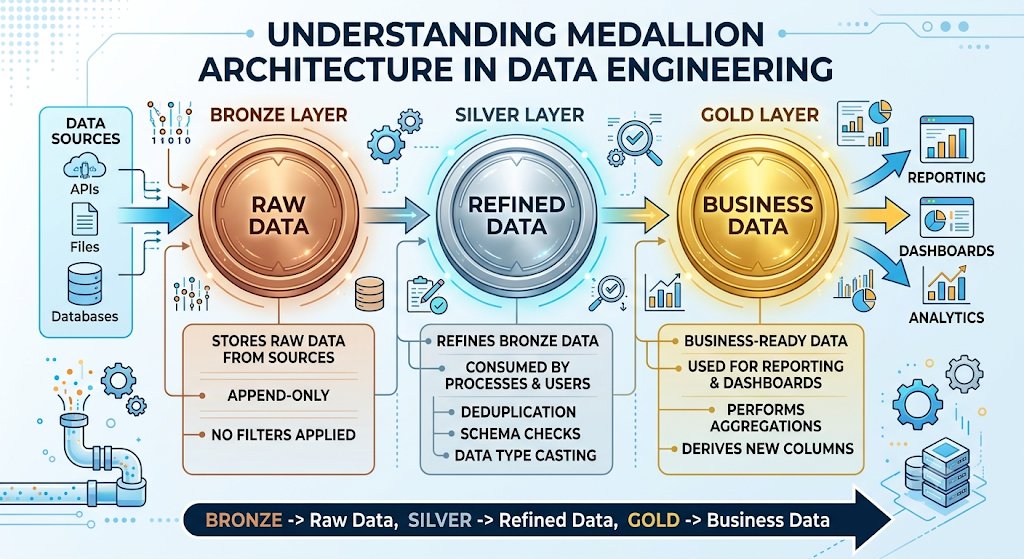
Medallion Architecture -
Bronze - We store the raw data into this layer . It is append only . We do not apply any filter .
Silver - We do some refinement on data stored in Bronze . Deduplication , schema check ,casting data types .
Gold - We apply some aggregation .
#Databricks
With Deletion Vectors, deleted rows are marked instead of rewriting the whole Parquet file. The same concept used with DELETE, UPDATE and MERGE.
I also learned how Delta handles duplicate batch writes using txnAppId and txnVersion to provide exactly-once semantics.
#Databricks
Today I learned about Time Travel and RESTORE in Databricks :-
- Time Travel helps us read data from an older version, while RESTORE rolls the table back to that version.
- If only a few rows are corrupted, restoring the whole table may remove other correct changes.
#Databricks