Proxy benchmarks are usually vendor marketing with no data attached. So we tested our own network — 10,000 requests, zero retries — and published the raw CSV.
99.67% success. Verify, don't trust: https://t.co/tblQ7JVzN7
Old Reddit now walls off logged-out visitors: "accounts are required to access old Reddit."
RSS feeds end Nov 13; the public API by March 2027.
Reddit says RSS became "a common surface for large-scale scraping and automated abuse."
RSS monitors: six days left.
#WebScraping
A tech blog checked its own logs: named AI crawlers asked for 16,194 pages in about six days.
On the night it read the origin log line by line, AI assistants sent back 0 readers. Search engines sent 41.
A challenge rule turned away 13,098 of those requests.
#AIcrawlers
Cloudflare: AI agents, cloud browsers and proxies are all intermediaries. Sites used to just block them. That stops working once most traffic is agentic.
Its fix: a Trusted Agent Delegation coalition, taking it to the IETF so sites can see the user behind the agent.
#AIagents
Cloudflare's blog post adds analytics.
Bot analysis gets a "Personal Assistants" category, with requests per agent.
Account Abuse Protection (early access) shows which agent made each login or sign-up.
Abuse on one account? Block that account, not the agent.
#BotManagement
A Colorado library network says bot connection attempts jumped from ~180M to over 2B per 30 days in a few weeks.
Its director ties most of it to AI training bots. One library had six full outages in weeks.
Scrape like a guest: rate-limit, cache, back off.
#AI#WebScraping
Microsoft Clarity now shows which AI agents visit your site and what they do: search, log in, book, check out.
Microsoft says weekly agent sessions on Clarity nearly doubled in 3 weeks to almost 2M.
It can also test whether an agent can finish a task.
#AIagents#Analytics
Cloudflare's blog post adds analytics.
Bot analysis gets a "Personal Assistants" category, with requests per agent.
Account Abuse Protection (early access) shows which agent made each login or sign-up.
Abuse on one account? Block that account, not the agent.
#BotManagement
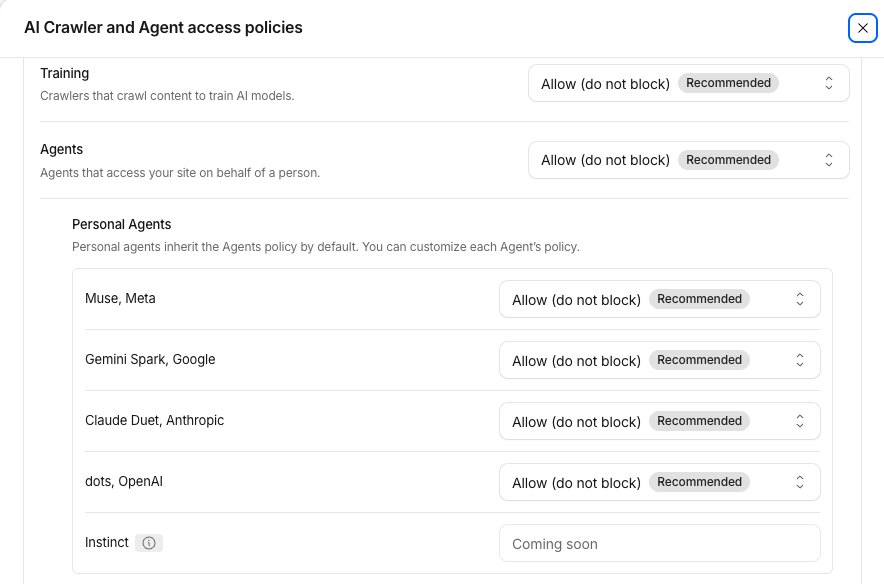
Cloudflare now lets sites set a rule per personal AI agent, not one "agents" bucket.
Listed: Meta Muse, Google Gemini Spark, Anthropic Claude Duet, OpenAI dots.
Default: same as Agents. Cloudflare recommends allow.
Agents get names. Names get rules.
#AIagents#BotManagement
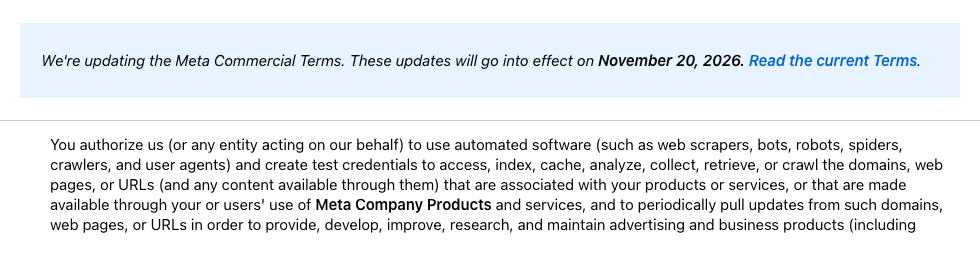
The UK CMA opened a Competition Act case into these Meta terms.
Concern: Meta could take content from businesses' and publishers' sites for its own products, AI included, with no say.
CMA says the rollout is on hold. No decision yet on whether Meta broke the law.
#WebScraping
Update: 10 Norwegian media houses incl. NRK and Schibsted took Meta to Oslo District Court on Oct 27 over these terms.
Today the court barred Meta from rolling them out until their legality is reviewed, plus 1M+ NOK in costs.
Meta: consultation "may take longer than Nov 20."
Cloudflare now lets sites set a rule per personal AI agent, not one "agents" bucket.
Listed: Meta Muse, Google Gemini Spark, Anthropic Claude Duet, OpenAI dots.
Default: same as Agents. Cloudflare recommends allow.
Agents get names. Names get rules.
#AIagents#BotManagement
Publishers say Brave crawled 30B+ webpages without ever naming its bot. No name, nothing to block.
The Daily News, Chicago Tribune and Orlando Sentinel allege this in a complaint filed Nov 2 in SDNY. The NYT sued Brave too. Allegations, not findings.
#WebScraping#AICrawlers
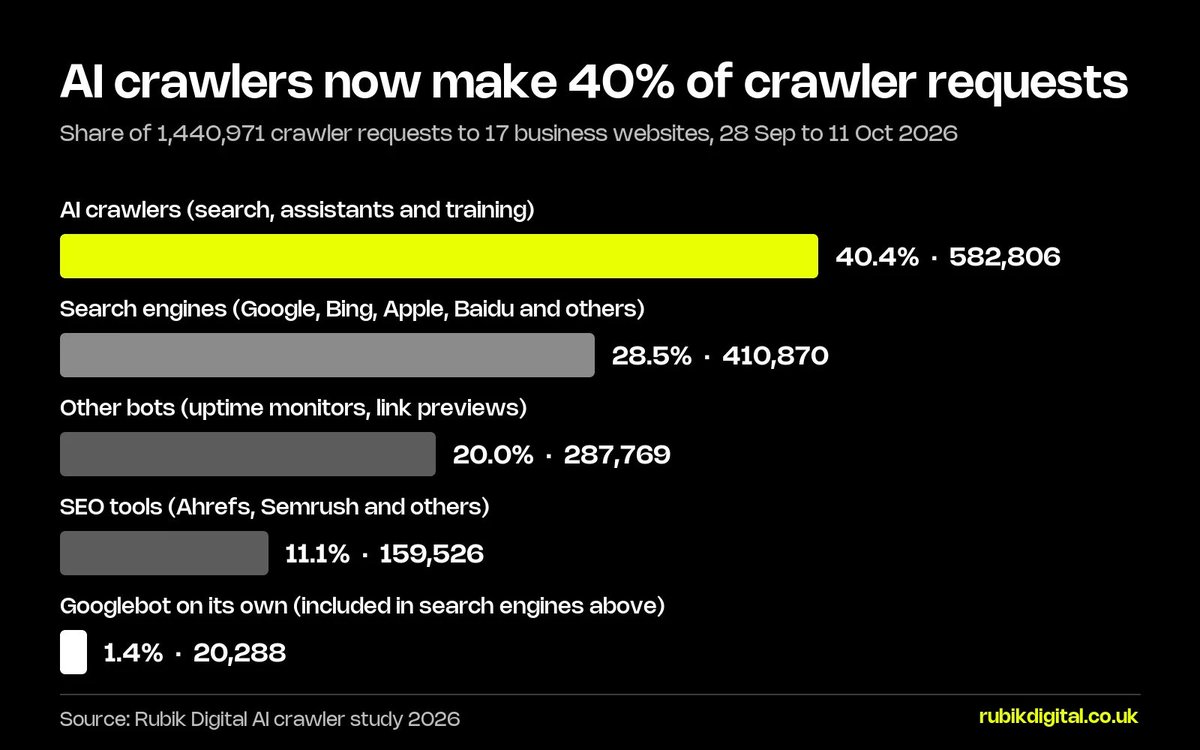
AI crawlers now out-request all search engines combined, at least on 17 UK business sites.
Rubik Digital counted 1.44M crawler requests in 2 weeks: AI bots 40.4%, search engines 28.5%. Googlebot alone: 1.4%.
Meta made 57% of AI requests, OpenAI 38%.
#AICrawlers#WebScraping
SERP APIs now return many Google organic results as https://t.co/c8JwVngaRk redirects, not the site URL.
One test, Oct 30: 2,552 of 4,344 results (58.7%) across 508 pages, 8 countries. Oct 15–21: zero.
Rank trackers matching by domain may show fake drops.
#SEO#WebScraping
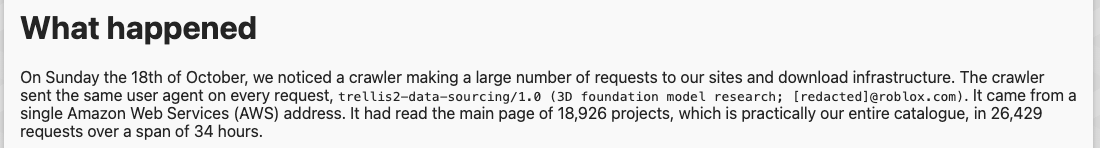
A crawler signed every request: a Roblox research user agent, one AWS IP.
Open3DLab: 26,429 requests in 34h, 145.5 GB taken, robots.txt fetched and ignored.
Roblox says a researcher's agent "mistakenly scraped" it.
Reading robots.txt isn't obeying it.
#WebScraping#AIagents
Google's Gary Illyes: faking Googlebot takes "probably 30 seconds", and robots.txt "is a suggestion".
What identifies Googlebot is the IP, not the UA: reverse DNS to *.googlebot.com, forward DNS back to the same IP, or a match against Google's published ranges.
#SEO#crawlers
Google, OpenAI, Microsoft and Anthropic will honor one robots.txt token to opt out of AI training: __usage_ai-training. Normal Disallow/Allow paths; old parsers skip it.
Google 2027, Microsoft Feb 1 2027, OpenAI coming months, Anthropic implementing.
Training only.
#robotstxt
Update: 10 Norwegian media houses incl. NRK and Schibsted took Meta to Oslo District Court on Oct 27 over these terms.
Today the court barred Meta from rolling them out until their legality is reviewed, plus 1M+ NOK in costs.
Meta: consultation "may take longer than Nov 20."
Meta's new crawl clause now starts Nov 20, not Oct 30.
Businesses on Facebook, Instagram or WhatsApp "authorize" Meta's scrapers and crawlers to fetch any site tied to their products.
"Train" was cut; use is now "advertising and business products." robots.txt isn't mentioned.
US static IPs on Roam: pick one of 27 US cities, including Washington, Atlanta and Seattle, and keep the same IP all month. $4/IP/mo, unlimited bandwidth.
Made for staying logged in to one account from one address.
Server-class IPs, not residential; the order page says so.
GreyNoise: a proxyjacking actor hit 143 edge devices in 34 countries (D-Link, Ubiquiti, SAP gear), installed a bandwidth-sharing app on each, and resold the victims' lines as residential proxies.
The app is legal. Installing it without consent is not.
#proxies#infosec
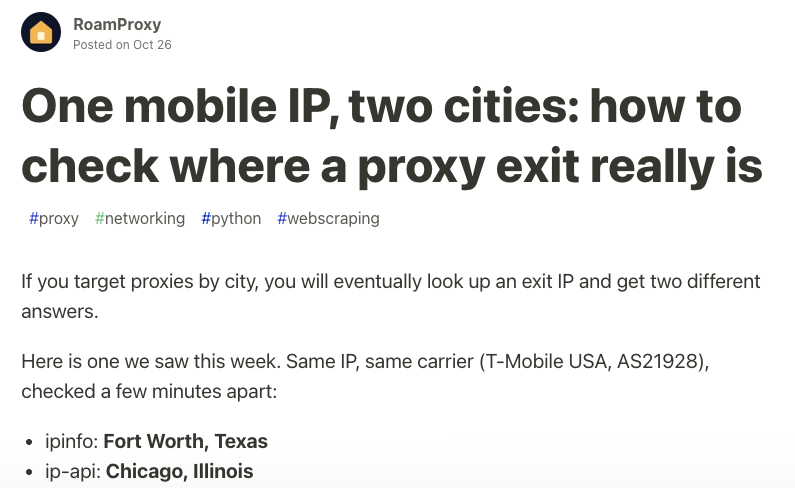
Checking where a mobile proxy exit really is? One IP database isn't enough.
Ask two, then look at the ASN and the mobile flag. If they disagree on the city, trust the region, not the city.
Our write-up, with a small Python script:
https://t.co/uJlvMBQAYz
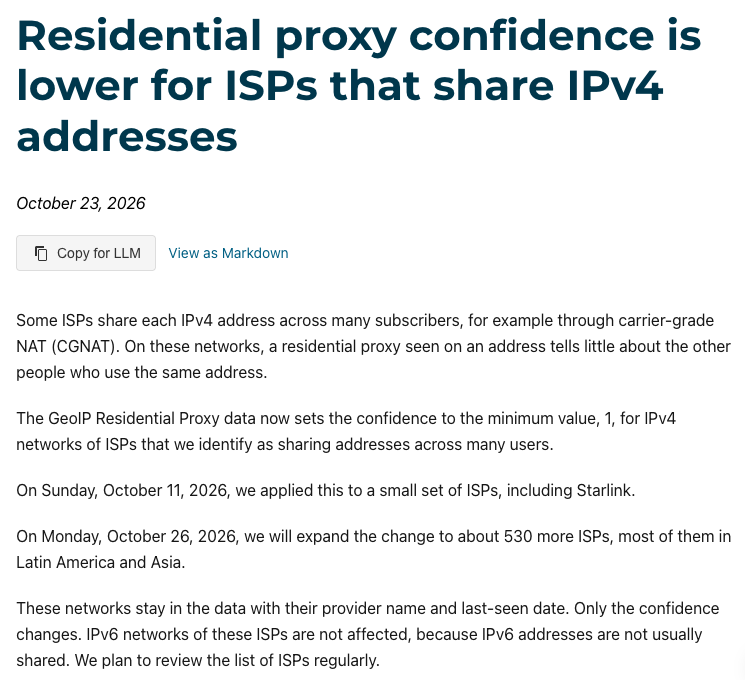
MaxMind now sets residential-proxy confidence to 1, the minimum, for ISPs that share IPv4 via CGNAT: Starlink since Oct 11, ~530 more ISPs from Oct 26.
One proxy on a shared address says little about the others behind it. MaxMind's advice: don't block on a 1.
#proxies#CGNAT
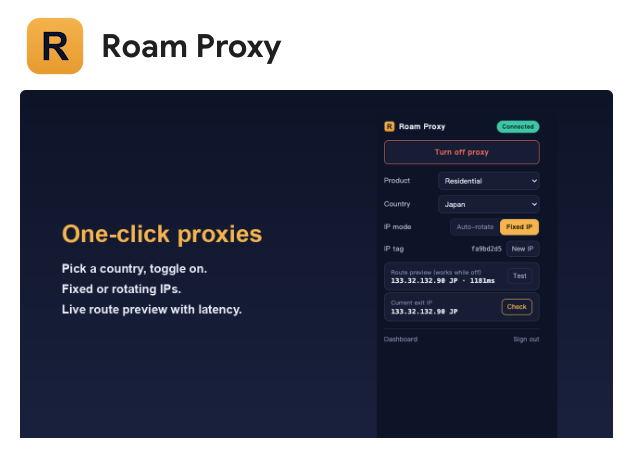
Roam Proxy for Chrome: pick a country, toggle on, and browse through a residential or datacenter IP.
Fixed IP for logins, auto-rotate for the rest. A route preview shows the exit IP and latency before you switch.
Same Roam account and wallet as the API.
https://t.co/p1H6gxy6Ae