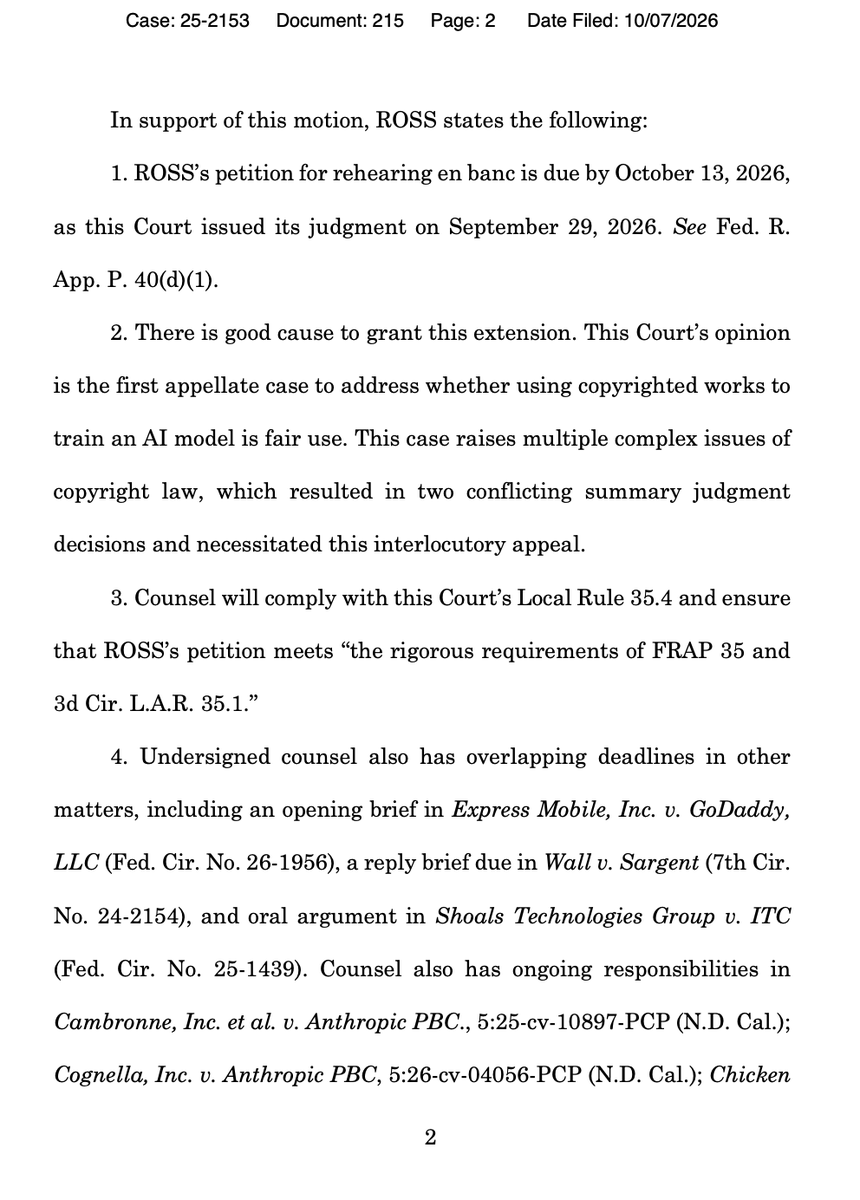
@dary@AnthropicAI Counsel also rejects the argument that if outputs are not infringing then it can't be said to cause market harm, pointing to Ross. His point is that the non-infringing outputs were harmful b/c they created a competitor to Westlaw
“This reasoning is difficult to square with two June 2025 decisions from the Northern District of California... The Third Circuit did not address circularity... Companies should watch whether further review takes up the circularity question.” - @WestlawToday
https://t.co/98g2Y6WtgU
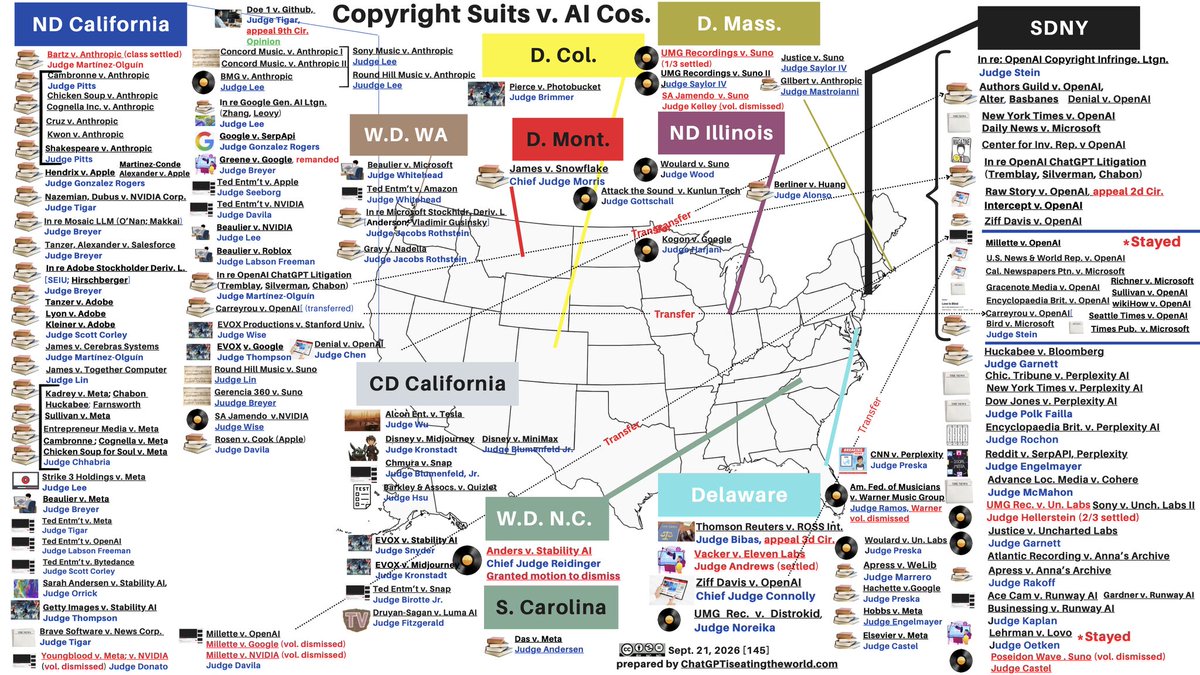
A California federal judge appeared open to Anthropic's defense that using copyrighted song lyrics to train Claude AI is fair use, saying during a daylong hearing that "mash-up" lyrics produced by AI might constitute fair use while also questioning how to "slice and dice" the case's scope. https://t.co/edj2IMfw7I
all these lawsuits are totally sustainable and the hallmark sign of healthy innovation first legal frameworks
really great for the USA’s super intelligence startup ecosystem and a sure fire way to expand competitive US SI capabilities to compete with and beat foreign competitors
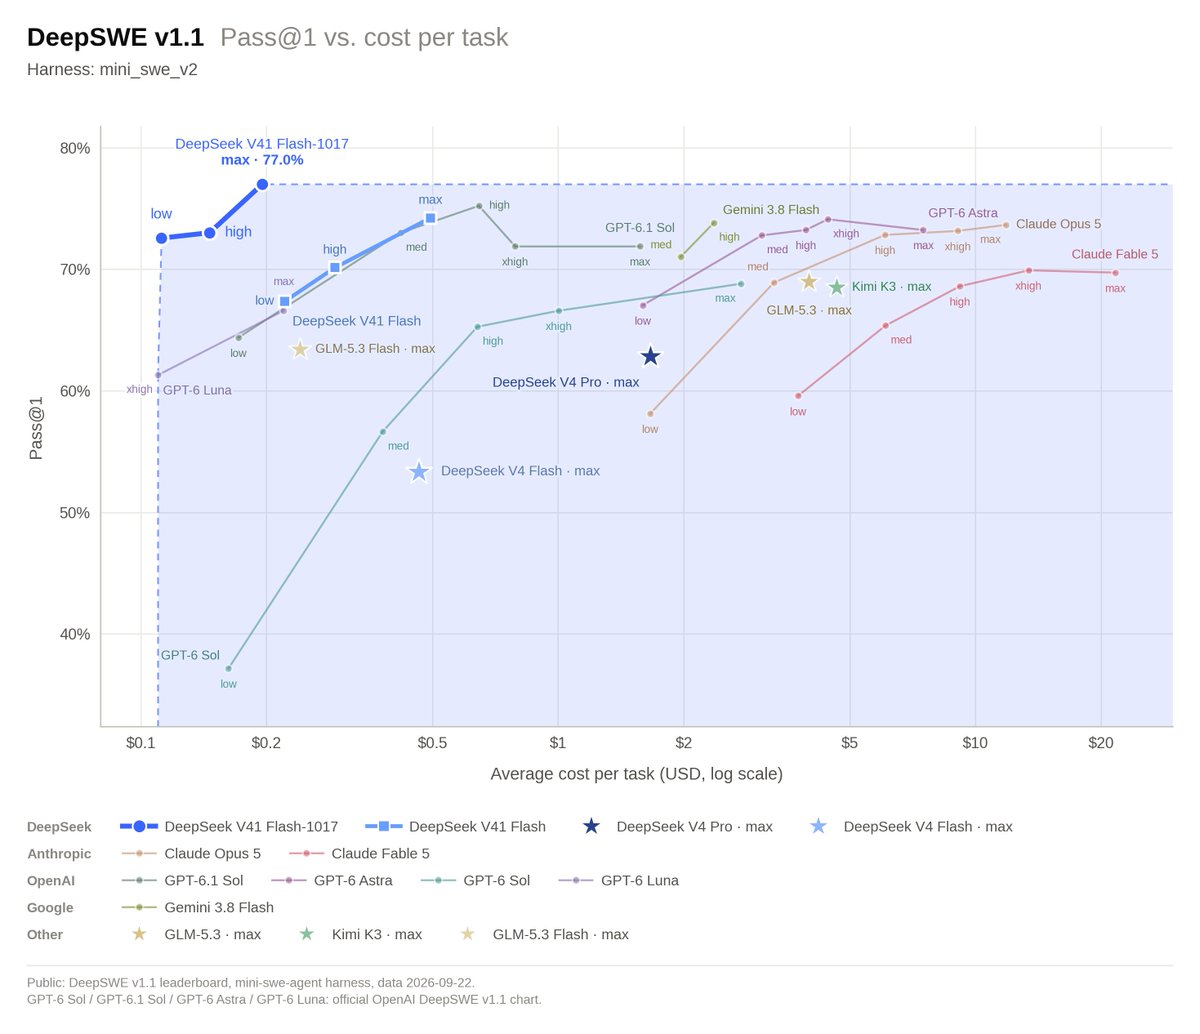
🚀 DeepSeek-V4.1-Flash-1017 is here!
Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost. Now live on our website, app, and API.
🛠️ Optimized for @DeepSeekHarness, Tencent CodeBuddy, WorkBuddy, and more. Upgrade to DeepSeek Harness v0.2.1-rc.1 or later for the best experience with the new model.
1/4
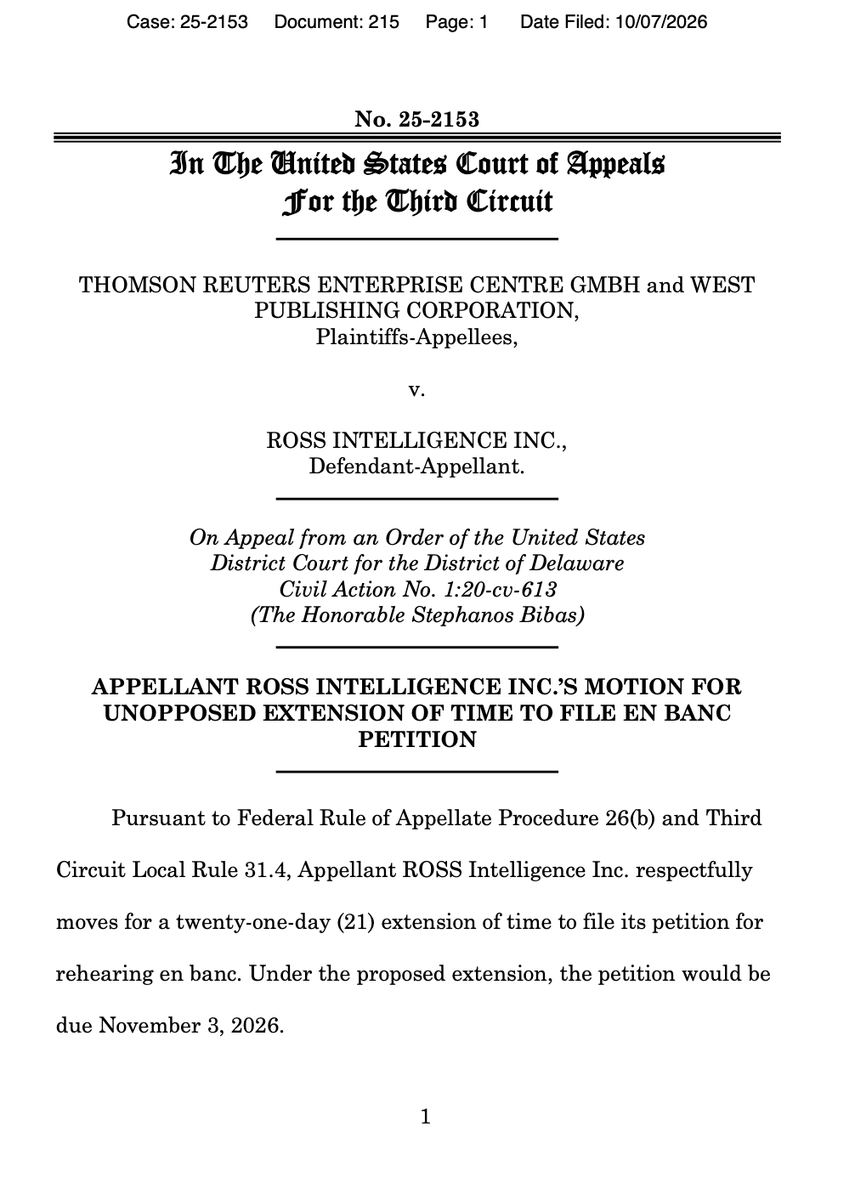
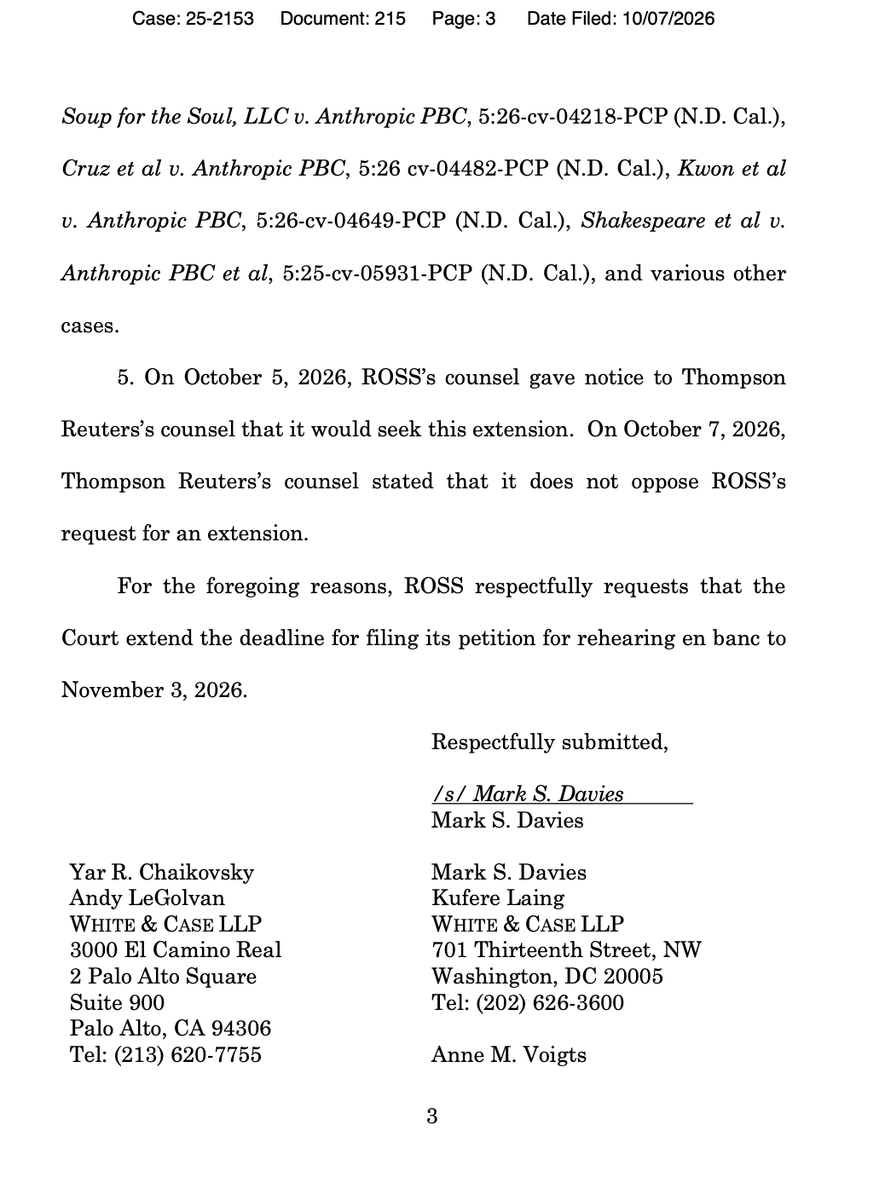
@RossIntel's request for more time to file its formal request for an en bank rehearing of a 3d Cir panel's decision against it in the @ThomsonReuters case has been ministerially granted. Look for that submission by or on 11/3:
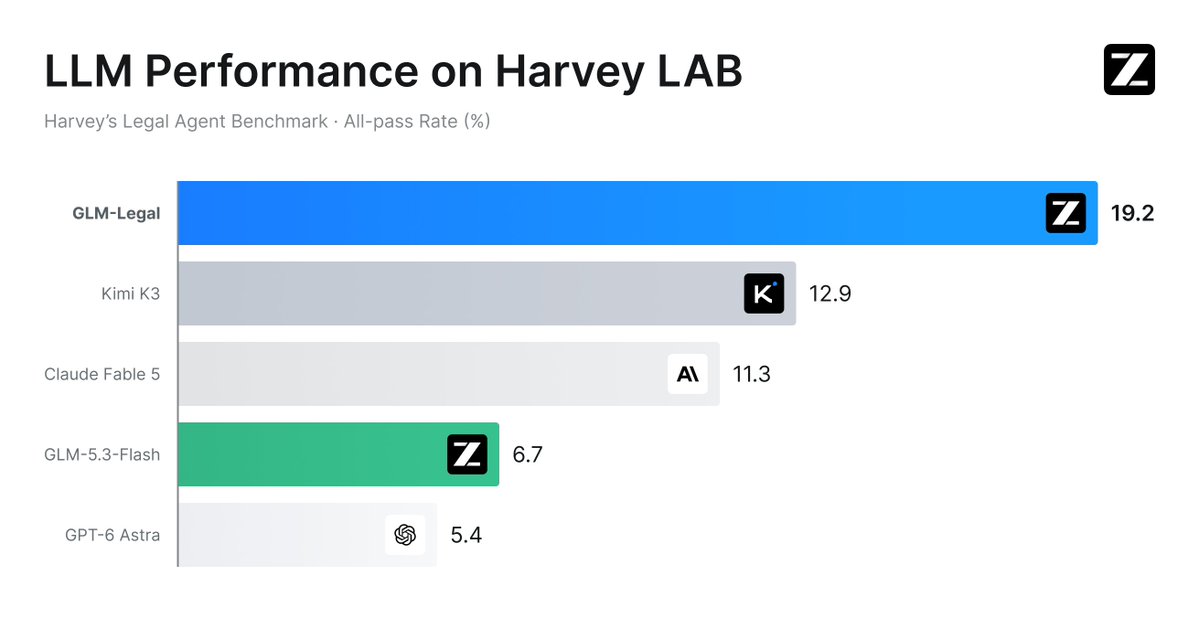
Introducing GLM-Legal
Built on GLM-5.3-Flash, GLM-Legal matches frontier models on mainstream legal benchmarks.
Designed for real legal workflows: contract review, evidence analysis, compliance, and more.
Tech Blog: https://t.co/xOzFqKNyqD
Apply for API Access: https://t.co/dKuoDRIKKz
Try AutoClaw: https://t.co/aGEG5HqTTb
“The Third Circuit, in contrast, having already found the use minimally transformative, credited a training data licensing market as a cognizable derivative market to be considered as part of the fourth fair use factor and did not address the arguments raised in the other two cases.”
https://t.co/lhugPmwi7k
“kinda crazy that government websites will include links to statutes that redirect to westlaw, which requires a subscription. laws should be easily accessible to the public if you want people to follow them.” 👀
kinda crazy that government websites will include links to statutes that redirect to westlaw, which requires a subscription. laws should be easily accessible to the public if you want people to follow them.
The AI bubble is becoming impossible to deny:
Major Wall Street financial firm Jefferies admitted most US AI companies will not be profitable, because Chinese open-source models are winning.
Jefferies warned of "malinvestment" by US Big Tech and "massive capital destruction".
publishers are using AI models trained on their direct competitors unlicensed copyrighted material in order to… compete directly with their competitors whose data the AI their using was trained on WHILE advancing lawsuits against AI model companies for… competing against them?
HarperCollins, Simon & Schuster, and Hachette are using Claude and ChatGPT to email literary agents, write publicity and back-cover copy, design cover art, marketing materials, and draft rejection letters. AI use among authors is apparently also rampant now behind the scenes.
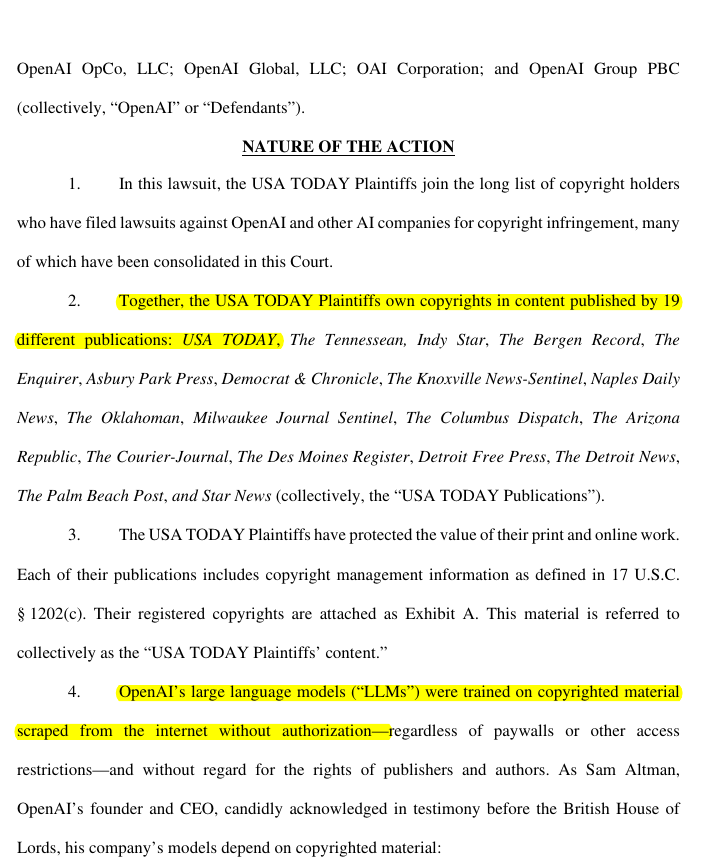
“They say a licensing market for their text already exists, the same derivative market the Third Circuit credited for headnotes. And they add a claim ROSS never had: the training pipeline threw away the byline and the copyright notice.” 👀
USA TODAY Co. filed lawsuit against OpenAI.
And wants $250M from OpenAI and every GPT model trained on its articles destroyed.
The suit, filed in Manhattan federal court by 14 plaintiffs covering 19 papers, says OpenAI copied hundreds of thousands of their stories.