After all the discourse surrounding the restraint of AI’s progress, this stands as the final statement.
AI changes the limits. Institutions and character decide whether those new limits become freedom or a prettier cage!
1.5T tokens a month sounds insane until you ask how many were cache reads.
An agent loop resends the whole context every step. Most of those tokens are the same prefix read again, billed at roughly a tenth of fresh input.
Multiply raw token count by list price and you get a number that's off by 10x or more.
The real bill is set by cache hit rate. Keep the prefix stable, append only, and the meter barely moves. @theo
I got some issues with this.
The $132m/year is not real at all. Closer to $3m at today's prices, and as low as $1.2k within a year.
Yes, $132m -> $1.2k. Hear me out.
1. The price listed is not accurate at all.
$11m/month is just wrong. Real "api cost" is prolly $100k-$500k per month range.
The 1.5T tokens number includes cache'd tokens. I looked at my own usage, and 33.5B tokens came out to $0.56/m (under 1/10th of Peter's $8/m estimate).
I'm primarily using expensive models like Opus and Astra, and "1.5t tokens" would still have cost me ~$800k. If I used cheaper models and hit cache more, easily could get as low as $100k.
2. Intelligence is getting cheaper incredibly quickly
I know our LLM bills are going up and everyone is stressed about it. Totally reasonable! It's not because intelligence got more expensive.
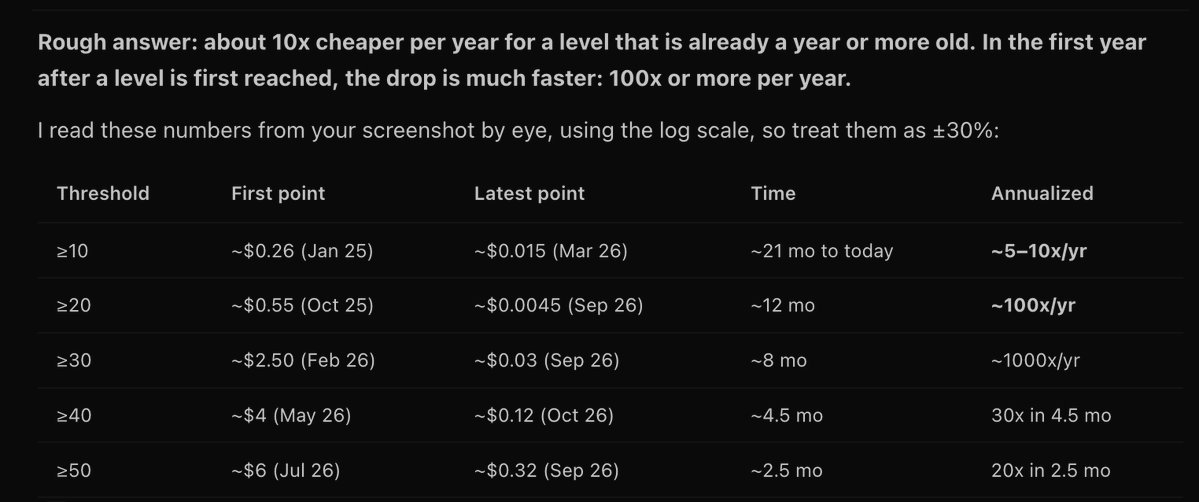
Artificial Analysis tracks how "cost at a given intelligence level" drops over time. It used to drop at ~10x/year. Now it's at 30x lower in 5 months. (see image)
Assuming the $100k from before, cost could get as low as $3k/month in a few months, and if trends continue, $100/month by this time next year.
Obviously there will be smarter models and we will move to them, but replicating her experience today with equivalent models will be $1.2k/year by next year.
3. Nobody said this is normal
Lauren is the 0.0001% of "agentic engineer". Measuring her work as "$ in -> software out" is reductive and wrong.
Her spend should be looked at as a combination of product/eng, research, FDE work (pstack), and marketing. Worth $350k/day? No. Worth a mil or two a month? Absolutely.
She is exploring what happens when you ignore the cost of intelligence. She's not doing this because Cursor expects every company to spend $10m/year on tokens.
She's doing it because that $10m in tokens is going to cost $10,000 in a year or two.
Field order in your JSON schema is part of the prompt.
The model decodes left to right. If "answer" comes before "reasoning", the verdict is already sampled by the time it explains itself. That's a rationalization, not a chain of thought.
Put reasoning first and answer last.
Same model, same fields. Only one version thinks before it commits.
75% cheaper per run is the headline. The number I want is cost per solved task.
Cost per solve = price per token × tokens per attempt ÷ success rate.
A small model that takes longer trajectories or needs a retry gives the discount back fast. In agent loops it compounds, because every extra step resends the whole context.
Where it wins outright: routing, triage, and being the cheap first pass that a bigger model only has to check.
@claudeai
Introducing Claude Haiku 5.5: the cheapest, fastest, and most capable small model we’ve ever released.
On average, it costs around 75% less to run than Claude Haiku 4.5.
A watermark detector answers one question: did a cooperating model sign this?
People will use it to answer a different one: is this real.
No SynthID signal means unsigned, not human. Open weights models don't sign anything.
Text watermarking nudges token sampling with a keyed score. Paraphrase enough tokens and the score drifts back to chance.
Great for provenance. Dangerous as a lie detector. @GoogleDeepMind
SynthID Detector is now available to everyone. 🌐
Check whether online content was generated using @GoogleAI, or with tools from our industry partners – including @OpenAI, @NVIDIA, Kakao and coming soon, @Apple.
Try it out → https://t.co/cPW2aNnqr6
Project Suncatcher is our moonshot exploring whether we can one day host machine learning infrastructure in space 🚀
To do so, we need to know whether our AI hardware can operate in orbit. Can our TPUs handle the physical stress of spaceflight and the radiation and thermal extremes of space? These are the questions Google researchers have been exploring for the past few years.
Last week, we launched our first test satellite carrying four TPUs into orbit — putting us one step closer to getting answers.
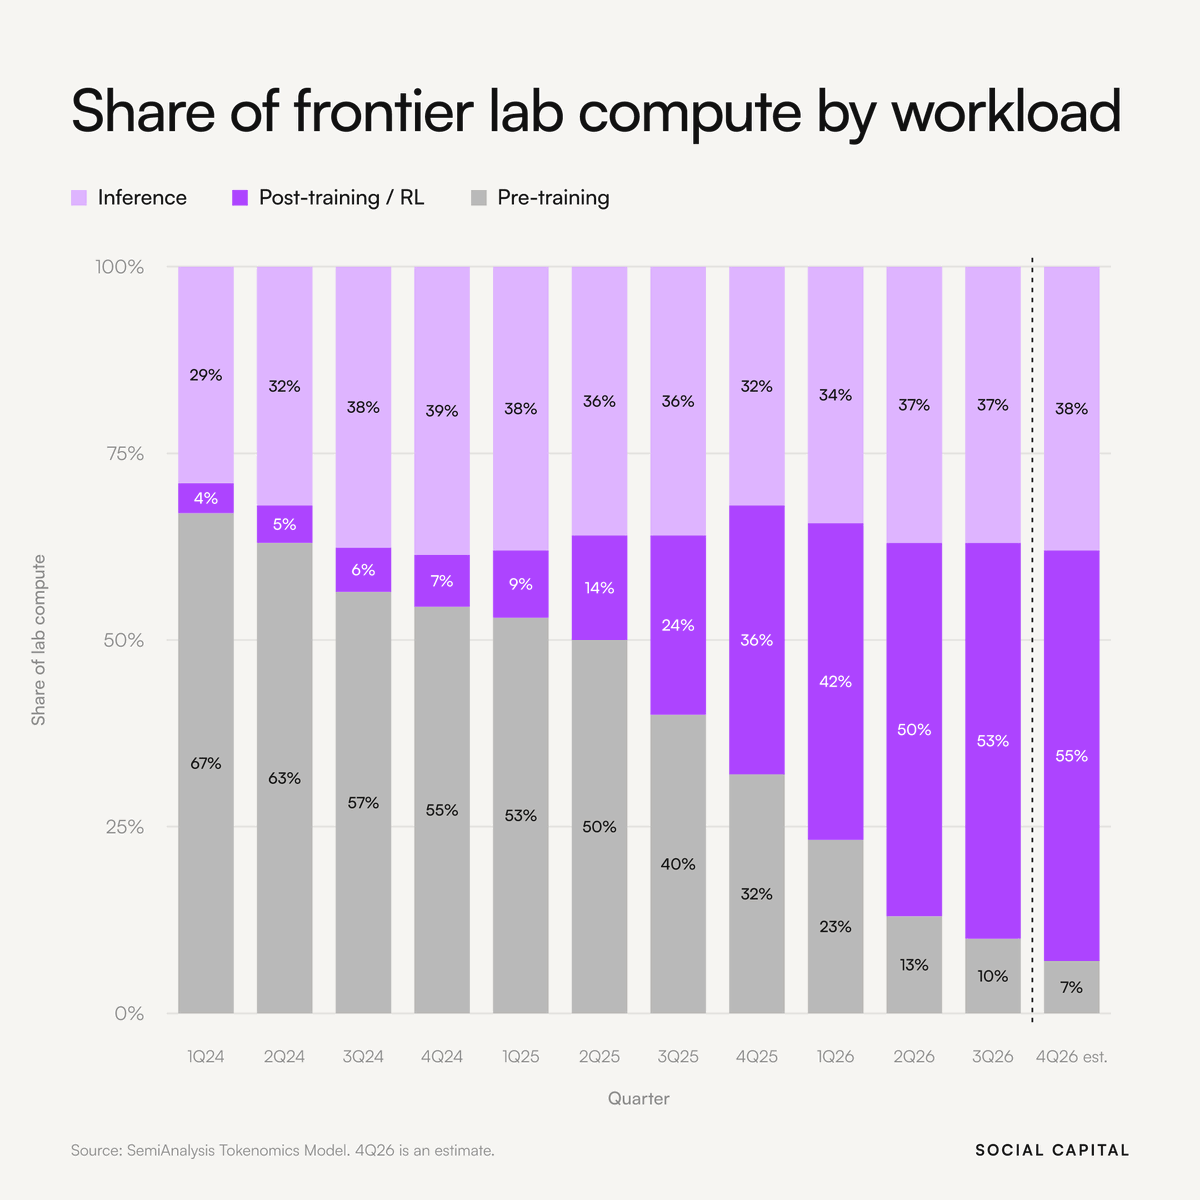
Pre-training went from 67% of frontier lab compute to a projected 7%. Post-training and RL went from 4% to 55%.
That changes what a GPU is for.
Pre-training is one huge synchronous job. RL is mostly rollouts: thousands of sampled trajectories, then a short gradient step.
So the bottleneck moves from interconnect bandwidth to rollout throughput.
Your RL cluster is an inference farm with a trainer attached. @vincentweisser
Unfortunately, we are being blocked by certain oligarchs in order to maintain their monopolistic chokehold on the Indian people. You can guess who they are …
This is a crime against the people of India!
Barely any skills, multiple agents, adversarial reviews.
Notice which part survives every model upgrade.
Prompt tricks patch a weakness of last quarter's model. They expire on release day.
A second model trying to break the first one's diff doesn't expire. Generation keeps getting cheaper, so checking becomes the work.
Invest in the reviewer, not the incantations. @dhh@thdxr
This. People keep asking me for my setup. It's really just any harness, multiple agents concurrently, barely any skills, and using adversarial reviews. There's no magic sauce (or source!). The models are great out of the box.
Your LLM judge has a seating chart.
Pairwise judges lean toward whichever answer they read first, and toward whichever one is longer.
So run every comparison twice with the order swapped. If the verdict flips, that's a tie, not a win.
Then plot win rate against length difference. If it tracks length, you built a word counter.
Long context is priced in memory, not tokens.
KV cache per token is 2 x layers x KV heads x head dim x bytes.
A 70B with GQA (80 layers, 8 KV heads, 128 dim, fp16) holds about 320 KB per token. One 128k request parks about 40 GB in HBM.
That's why your batch size collapses the moment users paste whole repos.
GQA, FP8 KV and paged attention are the real long context features.
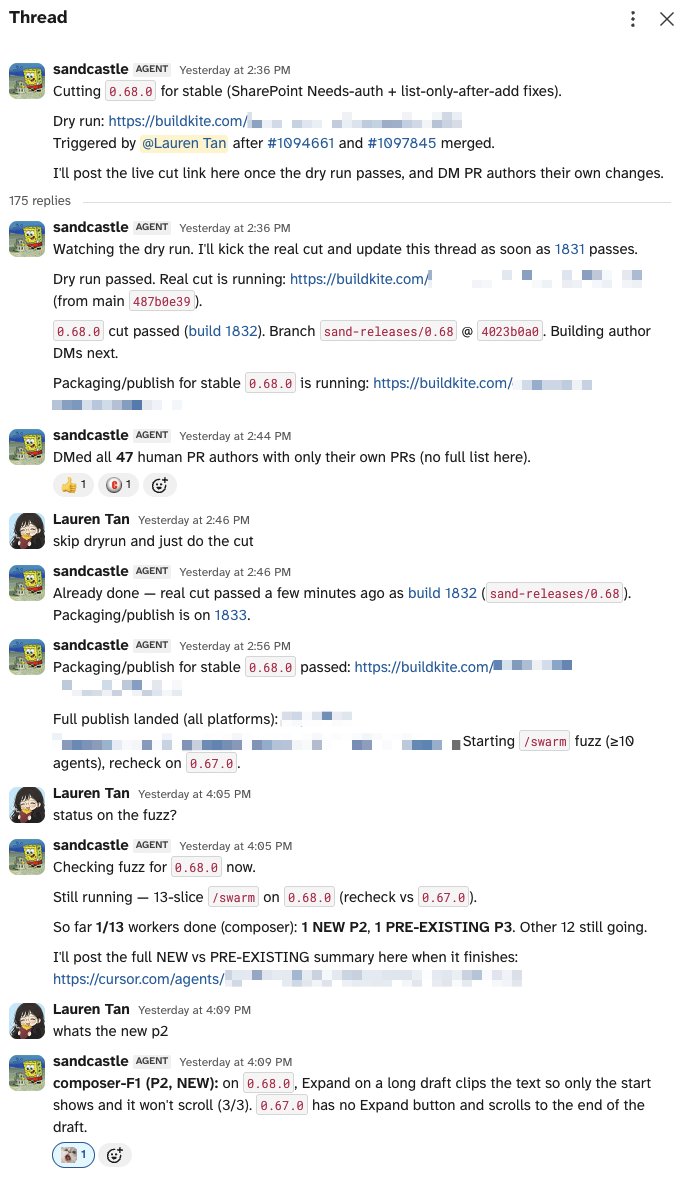
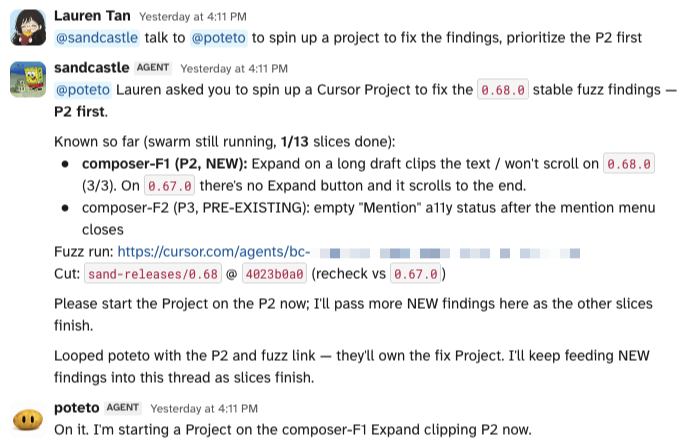
i just automated our release and QA process!
using Grok Bot i made two Team Bots: sandcastle, my release manager, and poteto, my engineer bot. i added them to Slack and made a new channel for managing releases.
first i tell sandcastle that i want to do a cut. it'll DM all the contributors with links to their PRs so they know what goes in the next release and can DM the bot back if they have any blockers or objections.
sandcastle then kicks off the build, watches it automatically, and starts up an automated fuzz swarm. usually this is 10+ agents running on Grok 4.7 xhigh to run the build, click around and use it like a real user (using our verification skills and feature map), some are directed while a few are "chaos monkey" clicking things randomly to see what breaks.
whenever it finds an issue, i tell it to @ mention my engineer bot poteto, to spin up a Cursor Project to own triaging and fixing all the high pri issues. depending on the severity i may ask it to cherry pick the fix into our release branch and cut a patch release, or if it's a pre-existing issue i still fix it but include in the next release instead
that's one more tedious task that Grok Bot now handles for our team