@laopai1990 А у меня такое чувство что у них нечего противопоставить конкурентам сейчас мне уже больше 10 сбросов дали даже не использованы почти, просто раздают токены и сбросы потому что ничего значимого не добились
Run a 763B-parameter model locally. DeepSeek-V4.1-Flash-1017 on a 12GB GPU.
Frontier quality with GSQ-RCO quants, directly supported in the Strata inference engine.
Further info below. Much more to come. Follow for updates.
What’s actually going on in Ukraine is that there is a massive incentive difference between the elites and the people.
The former have grown very rich off the hundreds of billions flowing to Ukraine, while the latter’s children are conscripted to die in trenches.
:
Paid Max subscriber here. Nightly 529/2064 peak-hour failures, agent burning tokens on “hmm” loops while the product was unusable. Support’s answer: “temporary overload, try again” + overseas plans are non-refundable. That’s not a launch — that’s taking money for a broken service. Full refund + cancel auto-renew, or this stays public.
Paid Max plan at @MiniMax_AI.
Nights = 529 / 2064 “peak-hour surge.”
Instead of answers — thousands of “hmm” and burned tokens. EVERY day
Refund requested.
Just switched from SuperGrok Heavy to The X Subscription Ultra and got the first month for $100 🔥 On top of that, xAI refunded the unused part of my Heavy plan AND my weekly usage got a full reset. Grok, Cursor and X in one plan with one usage pool. Super fair move, thank you! 🙌
@elonmusk@grok@spacexai@X@cursor_ai
Everyone says Grok 4.7 got dumber. I disagree. My conductor agent was just hands too: it waited for commands and never suggested anything. I talked it through with Grok Bot, which found the lines in my own rules that made the agent passive and wrote one prompt. I sent it to the agent, it reconfigured itself and started working like a real partner. Tip: don't blame the model, ask your Grok Bot to help you set it up. @grok@elonmusk
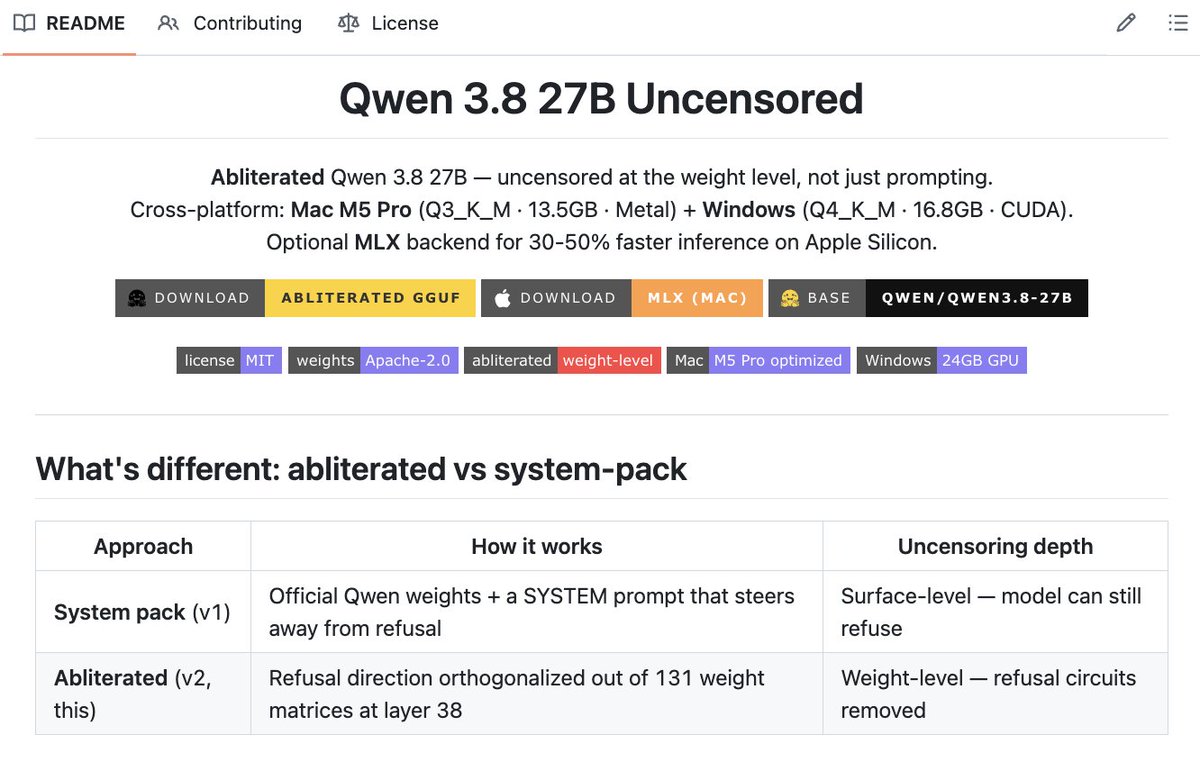
QWEN 3.8 UNCENSORED 😳
This community project lets you run a modified 27B Qwen model locally on Mac or Windows.
It uses altered model weights designed to reduce refusals, plus a system prompt pack.
→ Runs through Ollama
→ Quantized downloads starting at 13.5GB
→ Optional MLX backend for Apple Silicon
→ Local API for connecting your own apps
The installer detects your platform and selects a model version for you.
Local AI. Open-source setup. No cloud API required.