In collaboration with CoreWeave, we show how our autonomous system optimizes LLM inference end to end, from engine configuration to custom GPU kernels: up to 63% more traffic for GLM-5.3, 2x per-user throughput for Qwen3.8-27B, and 10% more throughput for DeepSeek V4.1 Flash. 🔗
If AI can generate CUDA kernels, what does a kernel engineer do now?
The work is shifting from hand-writing every kernel toward building the systems that make AI-generated kernels useful in practice — helping agents learn new hardware, improving search and feedback, and building better ways to verify correctness. Generation is getting cheaper, but correctness is becoming a critical problem. A generated kernel can look faster on a benchmark but fail in production because of race conditions, stream interactions, output reuse, or other subtle bugs. That makes verification and deep hardware expertise more central to the job.
At Standard Kernel, we’re building that infrastructure. Our cofounder @anneouyang spoke with Business Insider about how kernel engineering is changing.
https://t.co/CsK8ccb7jg
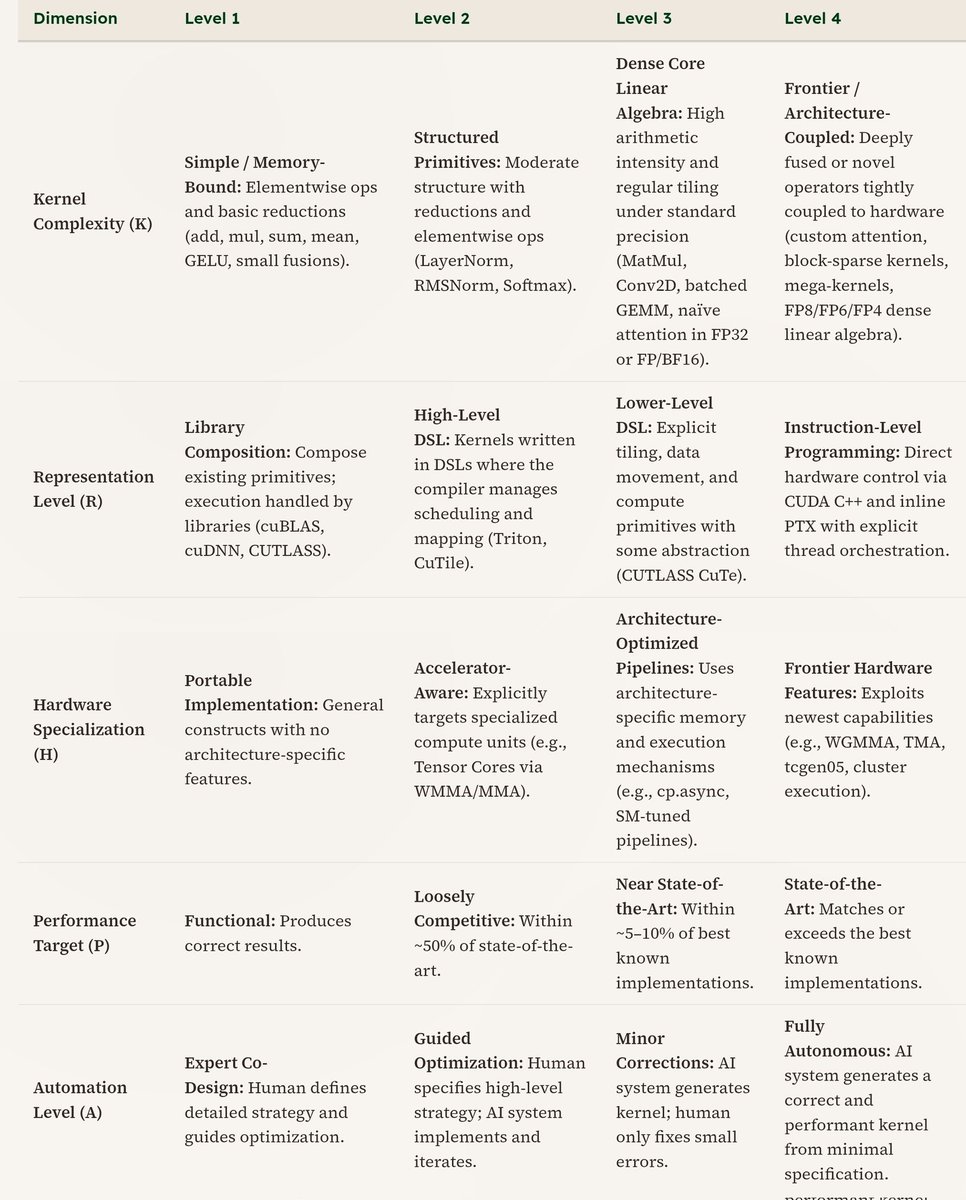
We built a system combining program analysis and LLMs to transform and optimize PTX. By operating at this shared layer across DSLs (e.g. Triton, TileLang, ThunderKittens, CUTLASS), our system learns the best ideas from each and generates kernels that outperform all of them (1/5)
One exciting application: a universal optimization layer across DSLs. High-level DSLs (Triton, CUTLASS, TileLang, ThunderKittens) are powerful but opaque, as they don’t reveal why one outperforms another. By working at the shared PTX layer, we can compare, learn, and compose their best implementations into kernels that outperform them all. (4/5)
We have a utilization problem.
GPUs are running <30% capacity.
@Standard_Kernel (@anneouyang + @ChrisRinard ) unlocks up to 4x performance.
Why we invested: https://t.co/YqovYkPhaO
AI progress increasingly depends on how efficiently workloads run on hardware.
@Standard_Kernel is tackling this challenge at the kernel level, unlocking more performance from modern GPUs.
We're proud to lead their seed with @generalcatalyst, @CoreWeave, @felicis, & @ericsson
It’s rare to find founders so perfectly and uniquely suited to solve a problem, let alone a problem of this magnitude and importance. Proud to lead @Standard_Kernel’s seed round.
Anne is killing it. Here's my quote from the press release
Kernel generation is key for improving performance and efficiency of AI hardware. As fleet sizes for users of AI hardware get larger, and more hardware diversity is introduced, Standard Kernel becomes key to deployment.”
Excited to share @Standard_Kernel's seed round and some reflections on what we’ve learned about kernel generation and what we believe is next. Grateful to our amazing team, supporters, and the broader community pushing this space forward.
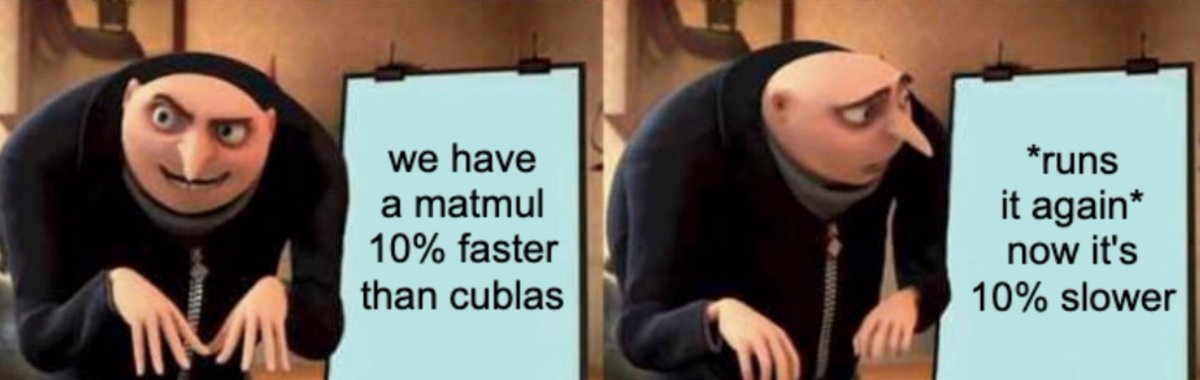
The choice of timing method (CUDA events, CUDA graphs, Nsight Compute, PyTorch profiler, etc.) can result in different measured GPU performance, and the effect depends on the workload. For microsecond-scale kernels, true execution time is often indistinguishable from measurement overhead and system variance. (7/9)
GPU timing is deceptively hard. Power limits, thermal state, clock behavior, caching, and measurement method all affect results in subtle ways. We explored sources of timing variation to obtain more reliable results for kernel benchmarking. (1/9)
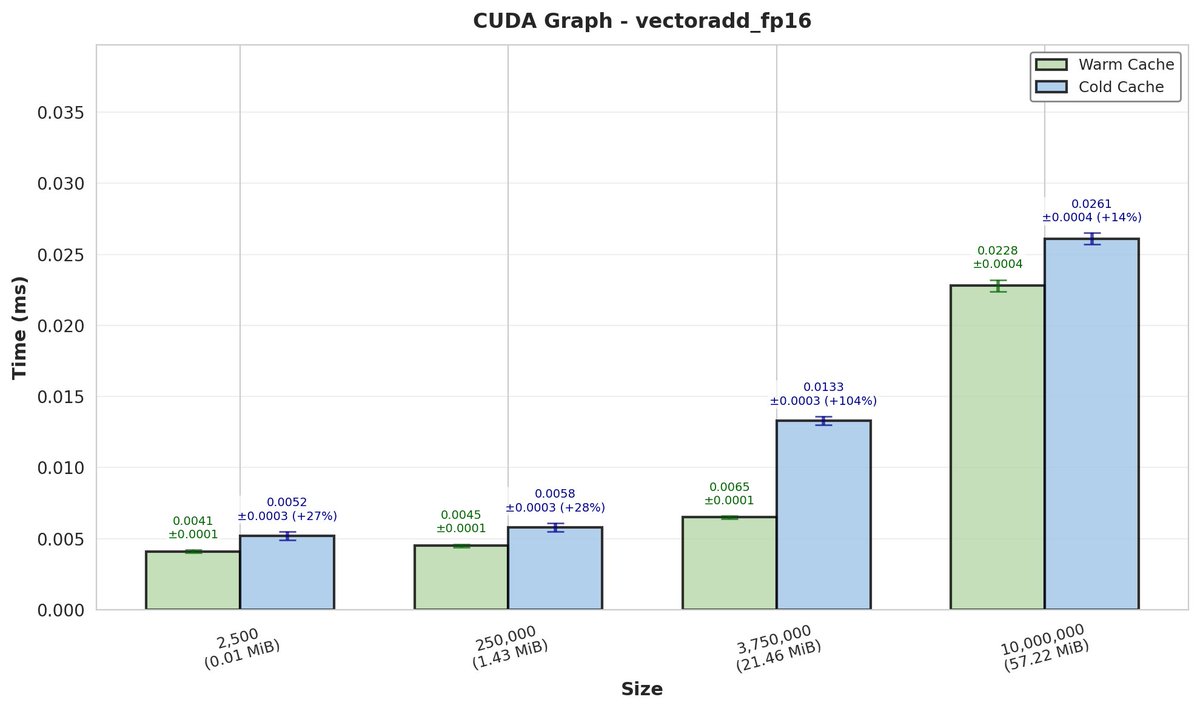
Warm caches can make GPU kernels appear much faster, and sensitivity to cold vs. warm cache varies by workload. Be explicit about which condition you measure, as the appropriate choice depends on the behavior you want to evaluate. (6/9)
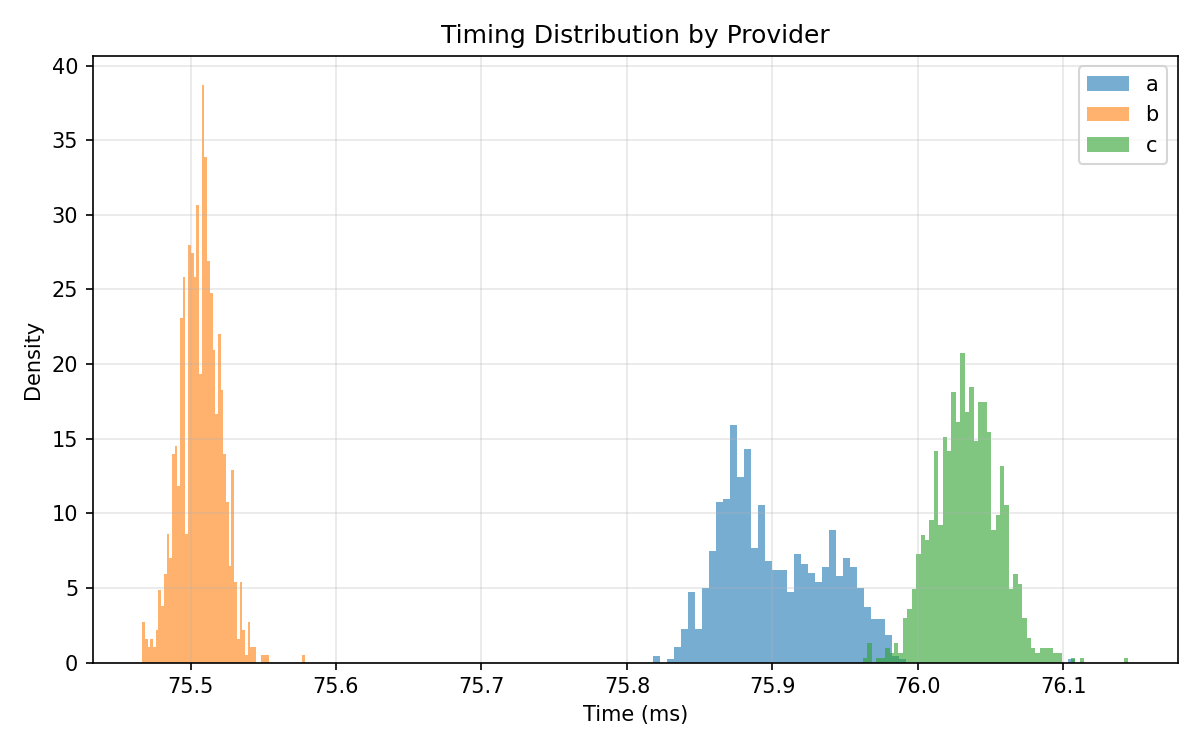
Getting identical hardware from cloud providers is not guaranteed. Across three cloud providers all listing “A100 80GB,” we received different variants with differing clock limits, power caps, and driver environments. When benchmarking an identical GEMM, the runtime distributions formed distinct clusters for each provider. (9/9)
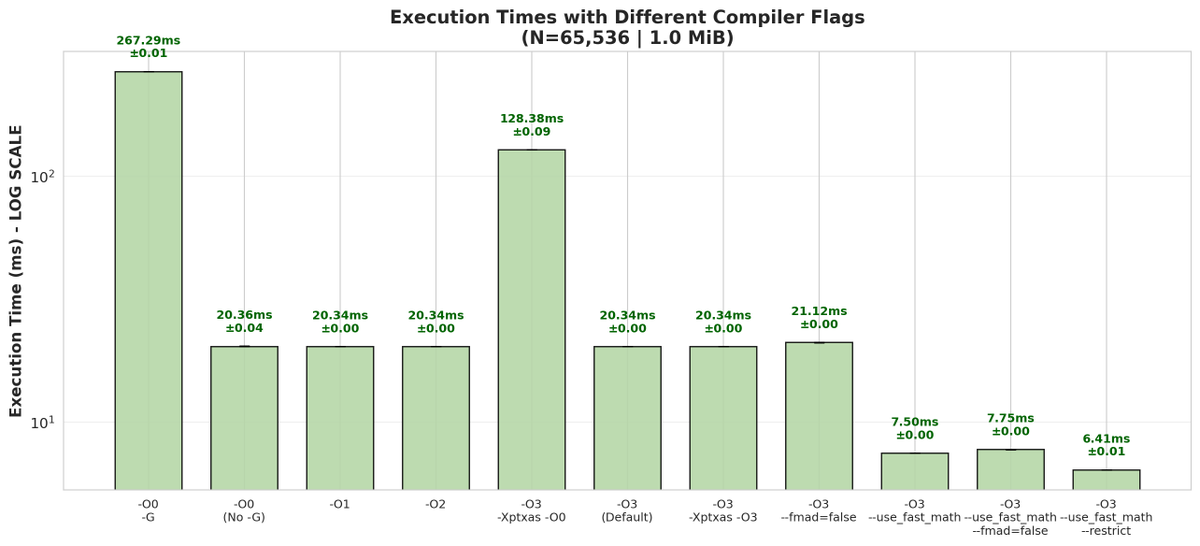
Compilation flags can change GPU performance on the same kernel + hardware. Sensitivity varies by workload, so uncontrolled flags can look like real algorithmic gains when they're just compiler effects. (8/9)