@Discworld_com For PC with ScummVM the music enhancement project with Discworld, the first game, is worth checking out: https://t.co/JlHggwuUVi Sir Terry even gave his blessing to it https://t.co/gbsYLKEQFQ
Crazy to think I've been coming to @Steel_Con for 10 years, I've learned so much and met amazing people over those ten, and applied what I've learned in my career and personal life. Thank you!
Lo-fi girl who? This is lo-fi REACH searching classified corporate archives at 2am 🎧
Listen to the REPLACED soundtrack yourself at 👇
https://t.co/pRrSkZfAtA
Knockoff is now live!
Filter out the knockoff crap brands on Amazon.
Sorry to brands like WNPETHOME, EHEYCIGA, YXYL, LU&MN, JOYIN, TOMY, GODONLIF, YOOJEE, LINGTENG, LANEIGE, VISCOO, BIODANCE, COOFANDY, BALENNZ, TOSY and LUENX.
https://t.co/9mLk0EAsfG
6.
Red Pitaya SDRlab 122-16
This one is more of an exploration and development platform (not a kit), however I still include it here.
It has dual input and output, Zynq 7020 FPGA + 16-bit ADC, and runs as HPSDR-compatible SDR via Pavel Demin's images
https://t.co/7Guw0QOtPb
7/9
Are you integrating Noctua fans into your engineering or other projects? We now offer public 3D CAD models of all our fans for download on our website, intended for mechanical design, renderings or animations: https://t.co/GLCTXDGxR5
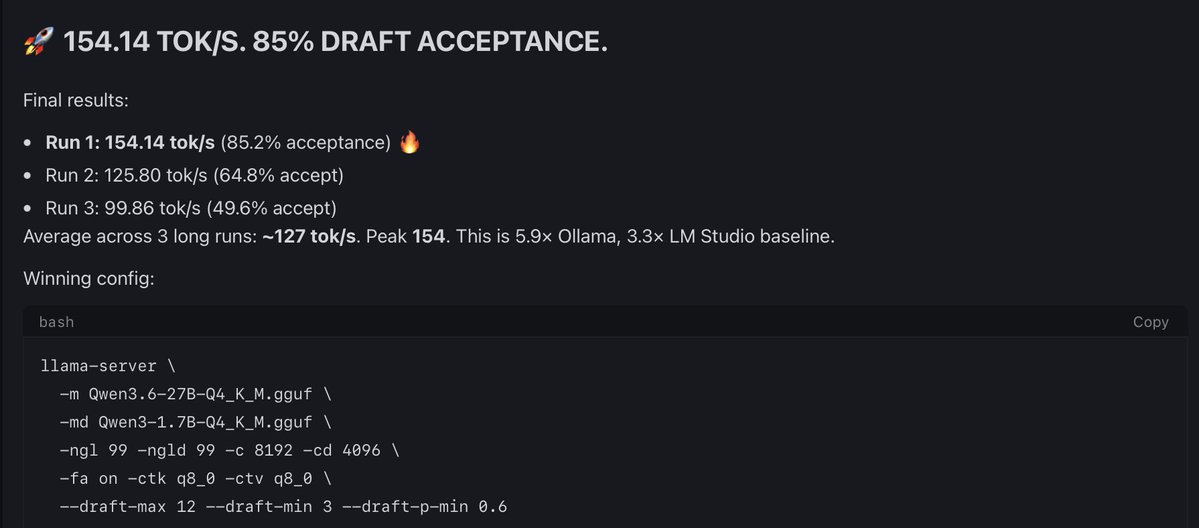
My 4090 went from 26 -> 154 tok/s Qwen 3.6 27B🤯
Same GPU. Same Q4_K_M . No FP8, no extra quant.
The unlock:
ik_llama.cpp + speculative decoding using Qwen3-1.7B as the draft model. 85% acceptance rate.
Full config + benchmarks 👇🏻
Sony PSP 3000 scan is complete. Files can be found here: https://t.co/92tmlIPeWq
Thanks to my Ko-Fi donators: https://t.co/K677bInNr9
Scans sponsored by @MatterandForm : https://t.co/VJ74DQyYWA
Consider donating to help us grow the 3D scan library👍
Remember, tomorrow is our second, and last, big ticket drop. Three sittings, 9:10, 13:00 and 19:00. Make sure you have your F5 fingers ready if you want to make sure you bag one before they sell out.
https://t.co/o3igvpqFH9
I created a nod to Raspberry Pi's legacy by disguising a @Raspberry_Pi 500+ as a BBC Micro, one of the machines that inspired our CEO Eben Upton's journey into computing.
https://t.co/G62yUOunjX
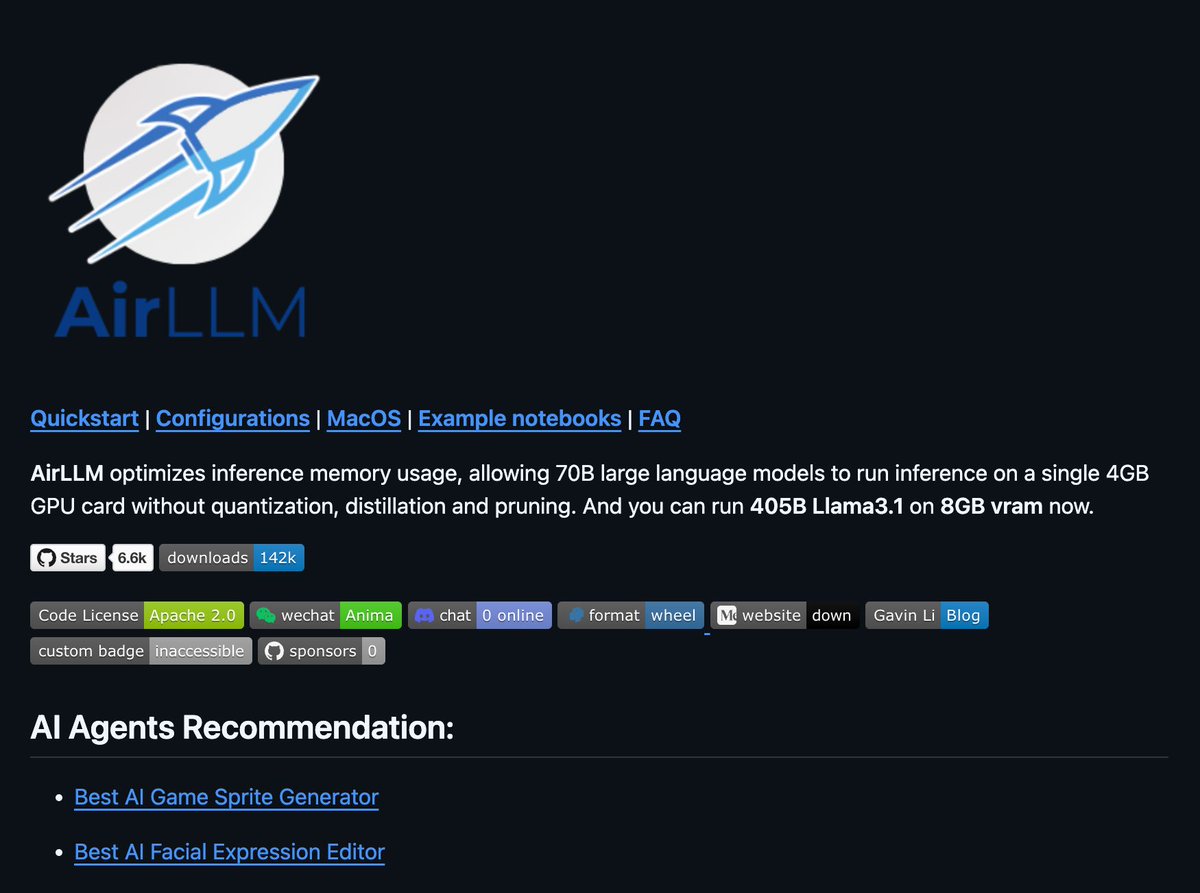
You can now run 70B LLMs on a 4GB GPU.
AirLLM just made massive models usable on low-memory hardware.
𝗪𝗵𝗮𝘁 𝗷𝘂𝘀𝘁 𝗵𝗮𝗽𝗽𝗲𝗻𝗲𝗱
AirLLM released memory-optimized inference for large language models.
It runs 70B models on 4GB VRAM.
It can even run 405B Llama 3.1 on 8GB VRAM.
𝗛𝗼𝘄 𝗶𝘁 𝘄𝗼𝗿𝗸𝘀
AirLLM loads models one layer at a time.
Instead of loading everything:
→ Load a layer
→ Run computation
→ Free memory
→ Load the next layer
This keeps GPU memory usage extremely low.
𝗞𝗲𝘆 𝗱𝗲𝘁𝗮𝗶𝗹𝘀
• No quantization required by default
• Optional 4-bit or 8-bit weight compression
• Same API as Hugging Face Transformers
• Supports CPU and GPU inference
• Works on Linux and macOS Apple Silicon
𝗪𝗵𝗮𝘁 𝘆𝗼𝘂 𝗰𝗮𝗻 𝗱𝗼
• Run Llama, Qwen, Mistral, Mixtral locally
• Test large models without cloud GPUs
• Prototype agents on cheap hardware