Mercury 2 is live 🚀🚀
The world’s first reasoning diffusion LLM, delivering 5x faster performance than leading speed-optimized LLMs.
Watching the team turn years of research into a real product never gets old, and I’m incredibly proud of what we’ve built.
We’re just getting started on what diffusion can do for language.
Constrained decoding for diffusion LLMs done right.
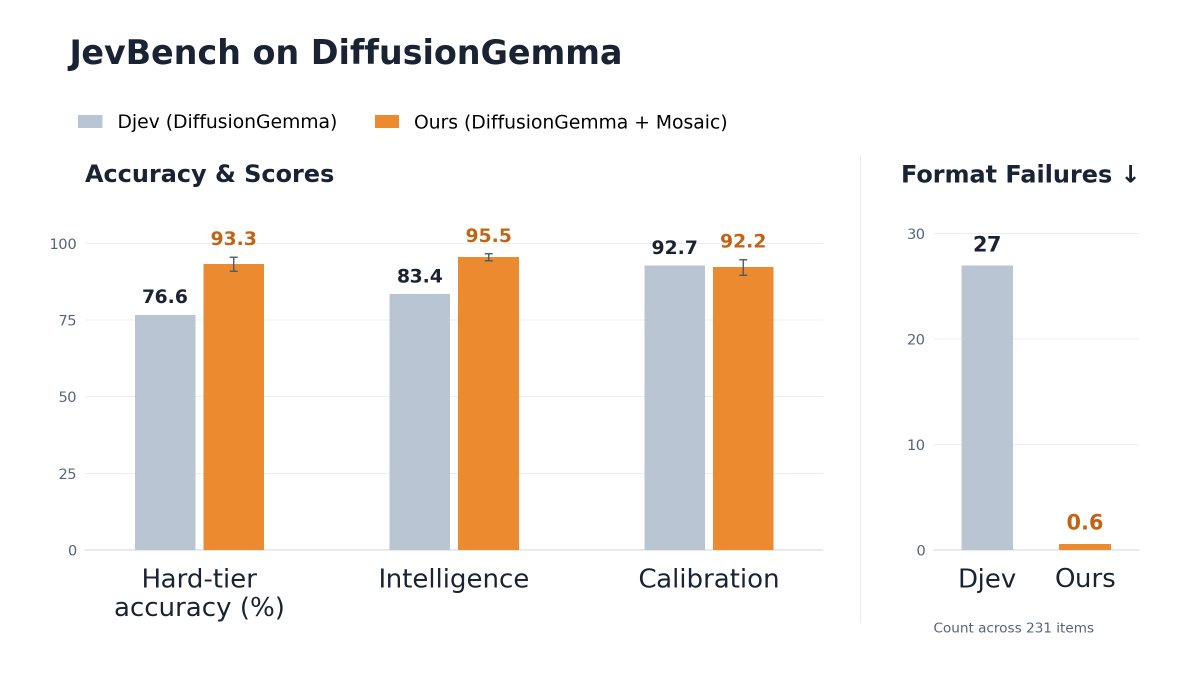
Great work by my student @meihuadang : viewing finite automata as graphical models to enable exact constrained decoding for diffusion LLMs, with big improvements on function calling and JevBench.
Very timely given the rise of Jev-like models. To appear at NeurIPS
Introducing Mosaic 🧩, a constrained decoding framework for diffusion language models.
- significantly improves DLMs' performance on general function calling and JevBench.
- compatible with vLLM, SGLang and HF, supporting DiffusionGemma, LLaDA2, and many others.
1/n 🧵
Introducing Mercury Decide: the most intelligent decision model on @OpenRouter (JevBench v1.4) and one of the fastest.
Up to 14 decisions per second. Watch it go head-to-head with Jev in chess.
Free for early access on OpenRouter: https://t.co/TiW4aVkspG
Mercury Decide from @_inception_ai is live on OpenRouter, free for early access.
It's a decision model: send your app's state and typed questions, and get back typed answers with probabilities attached. Inception reports it as the most intelligent decision model on OpenRouter on JevBench v1.4.
https://t.co/I5YFGyz61E
Today, we’re introducing Mercury Voice, a diffusion LLM specialized for agentic voice applications.
Mercury Voice delivers 2x+ lower latency than models including GPT-6 Luna, Gemma 4 31B, and Claude Haiku 4.5, while beating them on a range of voice benchmarks.
Enterprise customers interested in Mercury Voice can contact us at [email protected] to get access.
@aliansarinik The best training data comes from real enterprise workflows. Unlocking it while preserving privacy is a big deal. Great work from micro1.
Really enjoyed this conversation. We covered what diffusion changes about language models and why there’s still much room for architectural innovation in AI.
rare is the team doing true architectural AI research these days. I talk to the extraordinarily broad and productive researcher Stefano Ermon about his company, latency, and why it’s still worth going after good ideas in the age of scaling
rare is the team doing true architectural AI research these days. I talk to the extraordinarily broad and productive researcher Stefano Ermon about his company, latency, and why it’s still worth going after good ideas in the age of scaling
Today we're excited to announce Mercury 2.5
It’s the most capable diffusion LLM on the market. It is a 40% jump in intelligence over Mercury 2 and runs at over 1,100 tokens/sec on widely available @NVIDIAAI GPUs.
https://t.co/xFnPBuJ577
Mercury 2.5 is available through our API and on @OpenRouter and @Baseten. New accounts include 100M free tokens.
At launch, Mercury 2.5 is 80% off at $0.04/M input and $0.15/M output.
Try Mercury 2.5: https://t.co/3f9Bje64j5
Mercury powers real-time systems with the tightest latency budgets.
@OpenCall_AI uses Mercury to run voice agents on live patient calls. After switching from an AI inference chip provider, p50 latency fell below 200 ms and p99 fell from several minutes to one second. This keeps multi-step reasoning inside the latency budget of a live call.